








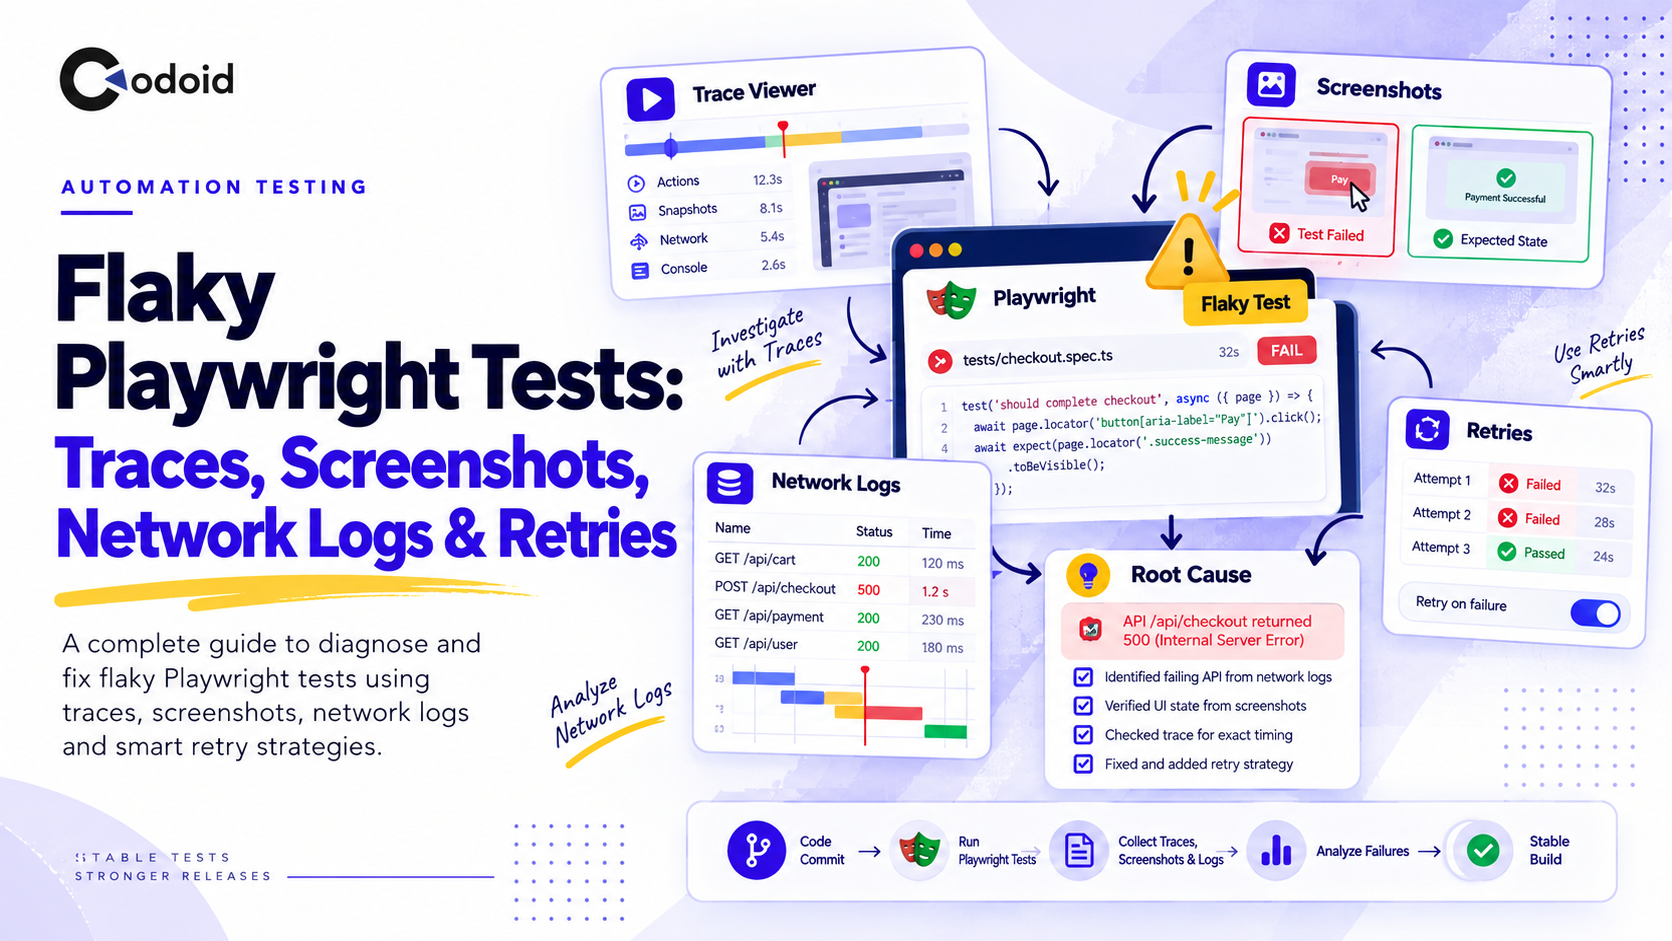
A Playwright test that fails once and passes immediately afterward is more dangerous than it looks. The retry may turn the pipeline green, but it does not explain whether the original failure came from a race condition, unstable test data, an API error, an overlay blocking a click, resource contention, or an actual application defect. The goal of debugging flaky Playwright tests is therefore not simply to make the next execution pass. It is to preserve enough evidence from the failing attempt to determine why the outcome changed.
Playwright provides several complementary debugging signals: traces, screenshots, browser and test logs, network activity, HTML reports, and retries. Used together, they can make intermittent failures reproducible and diagnosable. Used carelessly, particularly retries, they can also conceal instability. This guide uses the current Playwright 1.63-era feature set. Version 1.63 added the retain-on-failure-and-retries trace mode specifically to make comparison between failed and retried executions easier.
Codoid’s QA automation services help teams build reliable Playwright suites that surface instability early instead of hiding it behind retries.
Related Blogs
Playwright Test Architecture: How to Structure Fixtures, Page Objects, Parallel Runs, and CI
Docker Fundamentals for Testers: Images, Containers, Networks, and Volumes
TABLE OF CONTENTS (INTERNAL NAVIGATION)
- What Is a Flaky Playwright Test?
- Why Flaky Playwright Tests Matter
- How Flaky Test Debugging Works
- Configure Playwright to Preserve Evidence
- Reproduce the Problem Before Modifying
- Open the Failing Trace First
- Use Screenshots as State Evidence
- Inspect Network Behavior
- Compare the Failed Attempt with the Retry
- Fix Synchronization or Isolation
- Practical Example: Intermittent Checkout Failure
- Traces vs Screenshots vs Network Logs vs Retries
- Best Practices for Debugging Flaky Playwright Tests
- Common Mistakes When Debugging Flaky Tests
- Troubleshooting Common Flake Patterns
- Playwright Tools for Flaky Test Investigation
- Limitations and Risks
- Conclusion
How Should You Debug Flaky Playwright Tests?
To debug flaky Playwright tests without hiding failures, capture evidence from the original failure, compare it with the retry, and keep the initial failure visible to CI. Use Trace Viewer for execution history and DOM state, screenshots for visual checkpoints, network logs for API and transport failures, and only a small number of retries for additional diagnostic evidence.
For CI quality gates, Playwright’s failOnFlakyTests option is particularly important: a test that fails initially but succeeds on retry can still make the run fail instead of silently becoming a successful build.
Key Takeaways
- Treat retries as diagnostic observations, not as a fix for flaky Playwright tests.
- Use Trace Viewer as the primary CI debugging artifact because it combines actions, DOM snapshots, console output, errors, and network activity.
- Keep
screenshot: 'only-on-failure'for a lightweight visual record, and add named screenshots only around high-risk transitions when necessary. - Inspect both HTTP error responses and transport failures; a
500response does not trigger Playwright’srequestfailedevent. - Preserve both failed and retry traces when actively investigating intermittent failures.
- Use
failOnFlakyTestsor--fail-on-flaky-testswhen a pass-on-retry must not turn an unstable release gate green. - Before adding waits or more retries, check locators, auto-waiting, test isolation, shared state, network dependencies, and parallel execution.
What Is a Flaky Playwright Test?
A flaky Playwright test is a test whose outcome changes between executions even though the intended application behavior and test inputs have not deliberately changed.
Playwright Test formally categorizes a test as flaky when it fails on its first execution but passes on a retry. A test that passes initially is categorized as passed; one that exhausts its retries without passing is failed.
That distinction is useful, but not every intermittent failure is necessarily a bug in the test itself.
A flaky result may expose:
- A race condition in the application
- Unstable or eventually consistent backend data
- Network or dependency failures
- Shared test-account interference
- Differences between CI and local environments
- Brittle selectors
- Missing asynchronous assertions
- Resource pressure under parallel execution
- A real product defect that occurs only under specific timing conditions
A consistently reproducible failure is different. If the same input fails every time for the same reason, it is a deterministic failure rather than a flake.
The debugging objective for flaky Playwright tests is to determine which variable changed between the failing and passing executions.
Why Flaky Playwright Tests Matter
flaky Playwright tests reduce the value of automation because developers stop being able to interpret a failing pipeline as a meaningful signal.
The common response, “rerun it,” creates a more serious problem. A defect may remain present while the second execution happens to avoid the conditions that exposed it.
Retries can make this especially misleading. When Playwright retries a failed test, it does not simply continue inside the same broken browser. Following a failure, Playwright shuts down the worker process and starts another worker with a new browser before performing the retry.
That reset is useful for isolation, but it also means:
A passing retry proves that the test passed in a fresh execution environment. It does not prove that the original failure was harmless.
For example, if the first run fails because two parallel tests modify the same customer account, the new worker may retry after the conflicting test has finished. The retry passes, but the underlying concurrency defect remains.
How Flaky Test Debugging Works
A useful debugging workflow correlates four types of evidence rather than relying on one artifact in isolation:
- Trace: What actions occurred, what Playwright waited for, and what the DOM looked like around the failure?
- Screenshot: What did the rendered page visibly look like at a specific moment?
- Network evidence: Did the expected request happen, what HTTP status was returned, and did transport fail?
- Retry comparison: Did the same action succeed after the worker and browser were reset?
The sequence is important.
A failed screenshot may show a spinner. The trace can reveal which action was waiting behind that spinner. The Network tab can reveal that /api/orders returned 503. A passing retry can then show the same endpoint returning 201.
That evidence points toward a very different root cause than simply increasing a locator timeout.
Step-by-Step: Configure Playwright to Preserve Evidence
1. Keep Retries Small and Make Flaky Tests Visible in CI
A practical starting configuration is:
    // playwright.config.ts
    import { defineConfig } from '@playwright/test';

    const flakeDebug = process.env.FLAKE_DEBUG === '1';

    export default defineConfig({
      retries: process.env.CI ? 1 : 0,

      // A fail-then-pass result still fails the CI run.
      failOnFlakyTests: !!process.env.CI,

      reporter: [
        ['html', { open: 'never' }],
        ['list'],
      ],

      use: {
        screenshot: 'only-on-failure',

        trace: flakeDebug
          ? 'retain-on-failure-and-retries'
          : 'on-first-retry',
      },
    });
Playwright recommends on-first-retry for routine CI tracing rather than recording every test because tracing every execution has a performance cost. Playwright 1.63 additionally provides retain-on-failure-and-retries, which keeps relevant executions so a failing attempt can be compared with its retry.
This gives two useful operating modes:
- Normal CI: low-overhead trace collection on the first retry.
- Flake investigation: preserve failed and retried executions for comparison.
The important setting is failOnFlakyTests. Without it, a failing attempt that later passes can leave the overall run successful. Playwright also exposes the equivalent --fail-on-flaky-tests command-line option.
2. Reproduce the Problem Before Modifying the Test
Avoid immediately adding another timeout or retry. First establish how frequently and under which execution conditions the problem appears.
For example:
FLAKE_DEBUG=1 npx playwright test tests/checkout.spec.ts --repeat-each=20
--repeat-each executes the selected test repeatedly and is useful for exposing intermittent timing problems.
Then compare the result with single-worker execution:
    FLAKE_DEBUG=1 npx playwright test tests/checkout.spec.ts \
      --repeat-each=20 \
      --workers=1
Playwright supports --workers=1 specifically to disable parallel execution.
This comparison provides an immediate clue:
- Flaky with normal parallelism but stable with one worker: investigate shared accounts, data, ports, databases, rate limits, or other shared resources.
- Flaky in both modes: focus more strongly on application timing, network dependencies, selectors, assertions, or environment differences.
Twenty executions here are a diagnostic sample, not proof that the problem is permanently fixed if all twenty pass.
3. Open the Failing Trace Before Editing the Test
Use:
npx playwright show-trace path/to/trace.zip
or open the trace from Playwright’s HTML report.
Trace Viewer provides considerably more context than a screenshot. It can show:
- Actions and their duration
- Before, action, and after DOM snapshots
- The locator used
- Playwright’s action log
- The source line
- Test errors
- Browser and test console messages
- Network requests and responses
- Attachments
- Browser and execution metadata
The timeline can also filter console and network information to the period surrounding a particular action.
Start at the failed action and work backward.
For a failed click, ask:
- Did the locator resolve to the intended element?
- Was the element stable?
- Was it enabled?
- Was another element intercepting pointer events?
- Did navigation or rendering occur immediately before the failure?
- Was the expected API response already delayed or failing?
Playwright automatically checks actionability conditions such as visibility, stability, event reception, and enabled state before actions such as locator.click(). A timeout can therefore mean more than “the element was not found.”
4. Use Screenshots as State Evidence, Not as Your Complete Debugger
Enable automatic failure screenshots:
    use: {
      screenshot: 'only-on-failure',
    }
Playwright supports off, on, and only-on-failure screenshot modes, with artifacts normally stored in the configured test output directory.
A failure screenshot is useful for immediately spotting:
- Cookie banners
- Modal overlays
- Validation messages
- Logged-out sessions
- Loading indicators
- Wrong routes
- Unexpected empty states
- Layout differences
Its limitation is causality.
A screenshot tells you what the page looked like at one instant. It usually cannot tell you why it reached that state.
For a known flaky transition, attach a named checkpoint:
    import { test, expect } from '@playwright/test';

    test('places an order', async ({ page }) => {
      await page.goto('/checkout');

      await test.step('submit order', async step => {
        const screenshot = await page.screenshot({ fullPage: true });

        await step.attach('before-submit', {
          body: screenshot,
          contentType: 'image/png',
        });

        await page.getByRole('button', {
          name: 'Place order',
        }).click();
      });

      await expect(
        page.getByRole('heading', { name: /thank you/i })
      ).toBeVisible();
    });
Playwright can attach files or buffers to tests and individual test steps, allowing the evidence to appear in supporting reports.
Do this selectively. Capturing screenshots after every action creates noise and artifact overhead while Trace Viewer already records a visual timeline when tracing is enabled.
5. Inspect Network Behavior Instead of Guessing About Backend Timing
A UI failure may actually be a network failure.
Trace Viewer’s Network tab displays requests made during the test and exposes information including method, status, duration, headers, request bodies, and response bodies. Network activity can also be filtered to the actions selected in the trace timeline.
For important transitions, make the backend dependency explicit:
    const orderResponse = page.waitForResponse(response =>
      response.url().endsWith('/api/orders') &&
      response.request().method() === 'POST'
    );

    await page
      .getByRole('button', { name: 'Place order' })
      .click();

    const response = await orderResponse;

    expect(response.status()).toBe(201);

    await expect(
      page.getByRole('heading', { name: /thank you/i })
    ).toBeVisible();
Notice that waitForResponse() is registered before clicking the button. This prevents the test from missing a fast response that occurs immediately after the click. Playwright’s network documentation uses the same promise-before-action pattern.
You can also add targeted logging during an investigation:
    page.on('requestfailed', request => {
      console.error(
        '[transport failure]',
        request.method(),
        request.url(),
        request.failure()?.errorText
      );
    });

    page.on('response', response => {
      if (response.status() >= 500) {
        console.error(
          '[server error]',
          response.status(),
          response.url()
        );
      }
    });
The second listener matters because requestfailed does not mean “the server returned an error status.”
Playwright considers responses such as 404 and 503 successfully completed HTTP requests. requestfailed is emitted when the browser fails to obtain a response because of a transport-level problem such as a network error or timeout.
Without this distinction, an engineer may search for requestfailed events and incorrectly conclude that the network was healthy even though the application received a 500.
6. Compare the Failed Attempt with the Retry
The highest-value question is often not “why did this fail?” but:
What is different between the failed trace and the passing trace?
Compare:
| S. No | Signal | Failed attempt | Passing retry |
|---|---|---|---|
| 1 | Locator | Same target? | Same target? |
| 2 | DOM | Overlay, stale state, missing data? | Expected state present? |
| 3 | Action duration | Near timeout? | Immediate? |
| 4 | API status | 4xx or 5xx? | Expected 2xx? |
| 5 | Request timing | Slow or absent? | Normal? |
| 6 | Console | JavaScript error? | No error? |
| 7 | Authentication | Session expired? | Fresh session? |
| 8 | Test data | Conflicting record? | Available record? |
| 9 | Parallel activity | Competing test? | Conflict gone? |
Playwright 1.63‘s retain-on-failure-and-retries mode is particularly useful here because it was designed to retain traces that allow failed and retry executions to be compared.
7. Fix the Synchronization or Isolation Problem, Not the Symptom
Suppose the trace shows:
    const text = await page.locator('.status').textContent();
    expect(text).toBe('Complete');
If .status changes asynchronously, this assertion observes one instant in time.
Prefer:
    await expect(
      page.locator('.status')
    ).toHaveText('Complete');
Playwright’s web-first assertions automatically retry until their condition succeeds or the assertion timeout expires. Playwright explicitly warns that non-retrying assertions against asynchronously changing pages can create flaky Playwright tests.
Likewise, avoid:
await page.waitForTimeout(3000);
followed by an assumption that three seconds must be enough.
Wait for the actual application condition instead:
    await expect(
      page.getByRole('button', { name: 'Continue' })
    ).toBeEnabled();
or, when a backend response is the true synchronization boundary:
    const responsePromise = page.waitForResponse('**/api/profile');

    await page
      .getByRole('button', { name: 'Save' })
      .click();

    await responsePromise;
The test becomes resilient to reasonable timing variation without concealing a real timeout when the expected condition never occurs.
Practical Example: Debugging an Intermittent Checkout Failure
Consider this CI failure:
    TimeoutError: locator.click: Timeout 30000ms exceeded
    Locator: getByRole('button', { name: 'Place order' })
The retry passes.
A tempting change is:
    await page
      .getByRole('button', { name: 'Place order' })
      .click({ timeout: 60000 });
That increases tolerance but provides no evidence that thirty seconds was actually the problem.
A better investigation follows the evidence.
Preconditions
The checkout test:
- Creates a cart
- Loads
/checkout - Fills payment details
- Clicks Place order
- Expects a confirmation page
Evidence From the Failed Trace
Imagine the trace shows:
- The button exists and is visible
- A loading overlay appears above it
- Playwright repeatedly reports that another element receives pointer events
/api/shipping/quotetakes unusually long- The request eventually returns
503 - The application does not remove the loading overlay
The screenshot merely shows a spinner.
The network evidence explains why it remained there.
The action log explains why Playwright correctly refused to click the button.
The passing retry then shows:
/api/shipping/quotereturning200- The overlay disappearing
- The button becoming actionable
- The click completing immediately
The root cause is therefore not “Playwright cannot click the button.” The test exposed an application and dependency path in which a failed shipping request leaves checkout blocked.
Increasing the click timeout would have hidden the useful symptom while leaving the underlying behavior unchanged.
Traces vs Screenshots vs Network Logs vs Retries
| S. No | Debugging signal | Best question it answers | Main advantage | Main limitation | Recommended use |
|---|---|---|---|---|---|
| 1 | Trace | What sequence of events caused the failure? | Combines actions, DOM snapshots, logs, source, network data, and errors | More artifact and storage overhead | Primary CI debugging evidence |
| 2 | Screenshot | What did the user-visible page look like? | Fast visual diagnosis | No execution history or causality | Automatic on failure; targeted checkpoints when needed |
| 3 | Network logs | Did an API request fail, stall, or return unexpected data? | Reveals backend and transport problems | Does not explain every DOM or actionability problem | Inspect Trace Network tab and log critical endpoints |
| 4 | Retry | Does the behavior change in a fresh execution? | Supplies a second observation | Can hide failures if treated as success | Keep count low and report flakes explicitly |
The tools answer different questions. A reliable debugging process correlates them rather than selecting one as a universal solution.
Best Practices for Debugging Flaky Playwright Tests
Need Help Stabilizing Your Playwright Test Suite?
Talk to a Playwright ExpertMake Pass-on-Retry Visible to the Pipeline
Use:
failOnFlakyTests: !!process.env.CI
for quality gates where intermittent failures require investigation.
A retry can still collect useful evidence without allowing the build to appear stable.
Preserve the First Meaningful Failure
on-first-retry is efficient for general CI debugging, but when actively investigating a flake, preserving the failed execution itself is valuable.
On current Playwright versions, use:
trace: 'retain-on-failure-and-retries'
when comparing failed and retried attempts is worth the additional artifact cost.
Prefer State-Based Synchronization
Use locators, auto-waiting actions, web-first assertions, and explicit network expectations instead of arbitrary sleeps.
Playwright performs actionability checks automatically and provides retrying assertions specifically for asynchronous browser behavior.
Test Parallelism as a Diagnostic Variable
If a problem disappears with:
npx playwright test --workers=1
investigate shared server-side state rather than leaving the whole suite permanently serialized.
Playwright recommends isolated tests, and parallel workers should not depend on shared in-memory state. Teams that need help structuring this layer can benefit from reusable Playwright fixtures that isolate resources per worker.
Give Parallel Tests Independent Data
Separate test users, carts, organizations, records, and temporary resources where tests modify server-side state.
Playwright’s authentication guidance specifically recommends separate accounts per parallel worker for scenarios that modify shared server-side state.
Use Test Locks Only for Genuinely Shared Resources
Playwright 1.63 introduced named test locks. Tests sharing a lock do not execute concurrently, which can be useful for a truly exclusive external resource.
For example:
    test(
      'updates global billing settings',
      { lock: 'billing-settings' },
      async ({ page }) => {
        // ...
      }
    );
Do not use locks as a blanket solution for poorly isolated tests. Separate test data remains preferable when the system allows it.
Track First-Attempt Failures, Not Only Final Failures
Your flake metrics should distinguish:
- First-attempt pass
- Fail then pass
- Fail after all attempts
Otherwise, adding retries can improve the reported pass rate while actual test stability gets worse.
Related Blogs
Common Mistakes When Debugging Flaky Playwright Tests
| S. No | Mistake | Why it happens | Impact | Recommended fix |
|---|---|---|---|---|
| 1 | Increasing retries until CI becomes green | Retry appears cheaper than investigation | Instability becomes normalized | Keep retries limited and fail CI on flaky results where appropriate |
| 2 | Adding waitForTimeout() |
Failure looks timing-related | Makes tests slower without proving readiness | Wait for observable UI or network state |
| 3 | Looking only at screenshots | Screenshot is easy to inspect | Root cause remains unknown | Correlate screenshot with trace and network activity |
| 4 | Treating every requestfailed absence as network success |
Event name is misleading | HTTP 4xx and 5xx failures are missed | Inspect response statuses as well |
| 5 | Recording traces for every test | Maximum evidence seems safer | Increased runtime and storage indefinitely | Use targeted trace modes |
| 6 | Using force: true to bypass |
Click is blocked intermittently | Can hide a real overlay or UI bug | Determine why the element cannot receive events |
| 7 | Sharing one mutable test account across workers | Setup is simpler | Cross-test interference | Use independent resources or deliberate locking |
| 8 | Raising global timeouts | Slow CI causes failures | Real performance and synchronization problems become harder to detect | Increase only the timeout that has a justified requirement |
| 9 | Assuming a passing retry proves the test is healthy | Final result is green | Initial failure is discarded | Treat pass-on-retry as a distinct flaky state |
Troubleshooting Common Flake Patterns
Why does my Playwright test pass locally but fail in CI?
Start by comparing environment and execution conditions rather than increasing timeouts.
CI may have different CPU availability, browser versions, worker counts, network latency, authentication state, environment variables, or test data. Run the failing test repeatedly, preserve its trace, then compare normal parallel execution with --workers=1.
If the single-worker run is stable, shared state or resource contention becomes a stronger hypothesis. If both fail, inspect the trace for synchronization, network, and actionability differences.
Why is locator.click() timing out when the button is visible?
Visibility is only one of Playwright’s actionability checks.
For a normal click, Playwright also checks that the element is stable, receives pointer events, and is enabled. An overlay can therefore leave a button visibly present while preventing the click.
Open the failing trace and inspect its action log before using force: true.
Why does the retry pass when the first attempt failed?
The retry occurs after Playwright restarts the failed worker and its browser.
A fresh worker can remove several conditions that existed during the original run:
- Stale browser state
- Worker-scoped setup state
- Timing overlap with another test
- Temporary dependency failure
- Shared-data conflict
Compare the first failure and retry rather than treating the retry as proof that the original error can be ignored.
Why do I see an HTTP 500 but no requestfailed event?
Because an HTTP 500 is still an HTTP response.
Playwright emits requestfailed when the browser cannot obtain an HTTP response, for example because of a network-level failure. Error statuses such as 404 and 503 still complete as HTTP requests.
Monitor response status codes separately:
    page.on('response', response => {
      if (response.status() >= 400) {
        console.log(response.status(), response.url());
      }
    });
Why is a flaky test stable with –workers=1?
The test may depend on a resource another worker can modify concurrently.
Common examples include:
- One shared user account
- A fixed database record
- The same shopping cart
- A global configuration setting
- Rate-limited test credentials
- Shared file paths
- External systems that permit only one active operation
Use independent test resources where possible. If the resource is inherently exclusive, limit concurrency only around that resource rather than serializing unrelated tests.
Why does increasing the timeout make the flake disappear?
Because the test is being given more time, not necessarily because the synchronization problem has been fixed.
Inspect what consumed the additional time. If the application legitimately needs longer under a documented condition, a targeted timeout may be correct. If the timeout merely gives an uncertain race more opportunities to succeed, replace it with an observable readiness condition.
Playwright Tools for Flaky Test Investigation
Trace Viewer
Best for post-failure CI diagnosis.
npx playwright show-trace trace.zip
Trace Viewer exposes actions, DOM snapshots, logs, console events, network requests, errors, attachments, source locations, and execution metadata. Playwright recommends traces over standalone videos and screenshots for CI debugging.
The hosted Trace Viewer at trace.playwright.dev processes uploaded traces in the browser rather than transmitting their contents externally.
HTML Report
Use:
npx playwright show-report
The HTML report allows tests to be filtered by states including passed, failed, skipped, and flaky, then opened for detailed errors, steps, and attached artifacts. For a deeper walkthrough, see Codoid’s test reports guide.
UI Mode
Use:
npx playwright test --ui
UI Mode is useful while reproducing a problem locally and automatically provides tracing for interactive debugging.
Playwright Inspector
Use:
npx playwright test tests/example.spec.ts --debug
Playwright Inspector is useful when the problem can be reproduced locally and you need to step through actions or inspect locators.
–repeat-each
Use:
npx playwright test flaky.spec.ts --repeat-each=20
Repeated execution helps turn an intermittent failure into observable evidence. Avoid interpreting a small number of successful repeats as proof of long-term stability.
retryStrategy: ‘isolated’
Current Playwright versions also support:
    export default defineConfig({
      retries: 1,
      retryStrategy: 'isolated',
    });
With the isolated strategy, retries run after other tests have finished and are executed one by one in a single worker, reducing interference between retries and the rest of the suite. Playwright documents this as an alternative to the default immediate retry strategy.
This can be a useful diagnostic tool for concurrency-related flakes, but it should not become a substitute for fixing shared-state problems.
Limitations and Risks
Traces Can Contain Sensitive Information
Trace Viewer’s Network tab can expose request headers, response headers, request payloads, and response bodies.
Treat trace archives as potentially sensitive CI artifacts. Apply suitable access controls and retention policies, particularly when test systems use real-looking credentials, tokens, customer-like data, or internal APIs.
More Artifacts Create Runtime and Storage Costs
Recording every trace, video, and screenshot from every successful test can be expensive on large suites. Capture detailed artifacts conditionally instead of assuming maximum recording is always desirable.
Retries Change Execution Conditions
Because failed workers are replaced, a retry does not reproduce the original environment perfectly. It is a new observation.
This is why the failing attempt itself is often the most valuable artifact.
A Network Trace Does Not Explain Every Backend Problem
Browser-level network evidence can show what the browser sent and received. It cannot show an internal queue, database lock, service-to-service request, or backend exception that was never returned to the browser.
Correlate browser traces with server logs or distributed tracing when necessary.
A Test Can Expose a Product Flake Rather Than a Test Flake
Do not assume intermittent behavior belongs to automation code.
If the trace proves that the application sometimes leaves an overlay visible, returns inconsistent data, or fails an API request, the automated test may be accurately detecting nondeterministic product behavior.
Conclusion
Effective debugging of flaky Playwright tests is an evidence problem, not a retry-count problem. Use Trace Viewer to reconstruct the failing sequence, screenshots to understand visual state, and network evidence to identify backend or transport failures. Then compare the first failure with the retry to determine which condition changed.
Retries remain useful when they provide another observation. They become harmful when they erase the significance of the first one. A strong CI strategy therefore does both: retain enough evidence to diagnose the failure and keep fail-then-pass tests visible as flaky. With failOnFlakyTests, targeted tracing, web-first assertions, explicit network synchronization, isolated test data, and controlled parallelism, Playwright retries can help investigate instability without converting instability into a false green build.
Codoid’s QA automation services help teams design Playwright suites that surface flakes early, preserve the right evidence, and keep release gates meaningful.
Need Help Stabilizing Your Playwright Test Suite?
Talk to a Playwright ExpertFrequently Asked Questions
-
Should I enable trace: 'on' for every Playwright test?
Usually not for routine CI. Playwright warns that tracing every execution is performance-heavy and recommends on-first-retry for CI debugging. During an active flake investigation, retain-on-failure-and-retries can provide more useful failed-versus-passing comparisons.
-
How many retries should a Playwright test have?
Use the smallest number that serves your diagnostic or resilience policy. A single retry often provides the critical second observation without repeatedly rerunning an unstable test. More retries increase runtime and increase the chance that intermittent instability becomes visually buried. Whatever count you select, report fail-then-pass executions separately from first-attempt passes.
-
Can Playwright fail CI when a test passes on retry?
Yes. Configure failOnFlakyTests: true or run npx playwright test --fail-on-flaky-tests. Playwright will then return an error when a test is classified as flaky instead of allowing recovered failures to behave like an entirely successful run.
-
Are screenshots enough for debugging Playwright CI failures?
No. Screenshots are excellent state evidence, but they do not show the chain of events leading to the state. Trace Viewer is more complete because it combines screenshots and DOM snapshots with actions, logs, errors, source code, console messages, and network activity.
-
Should I use force: true when a Playwright click is flaky?
Only when bypassing the normal actionability behavior is genuinely part of the intended test. A forced click can suppress checks that would otherwise reveal that an overlay or another element is intercepting user interaction. Inspect the trace first and determine why the target cannot receive the event.
-
How can I tell whether parallel execution causes the flake?
Repeat the test under its normal execution conditions, then repeat it with --workers=1. If failures reliably occur only with multiple workers, investigate shared external state, resource limits, or test-data collisions. Playwright provides single-worker execution specifically for disabling parallelism during this type of diagnosis.







Comments(0)