by Rajesh K | Sep 30, 2026 | Accessibility Testing, Blog, Latest Post |
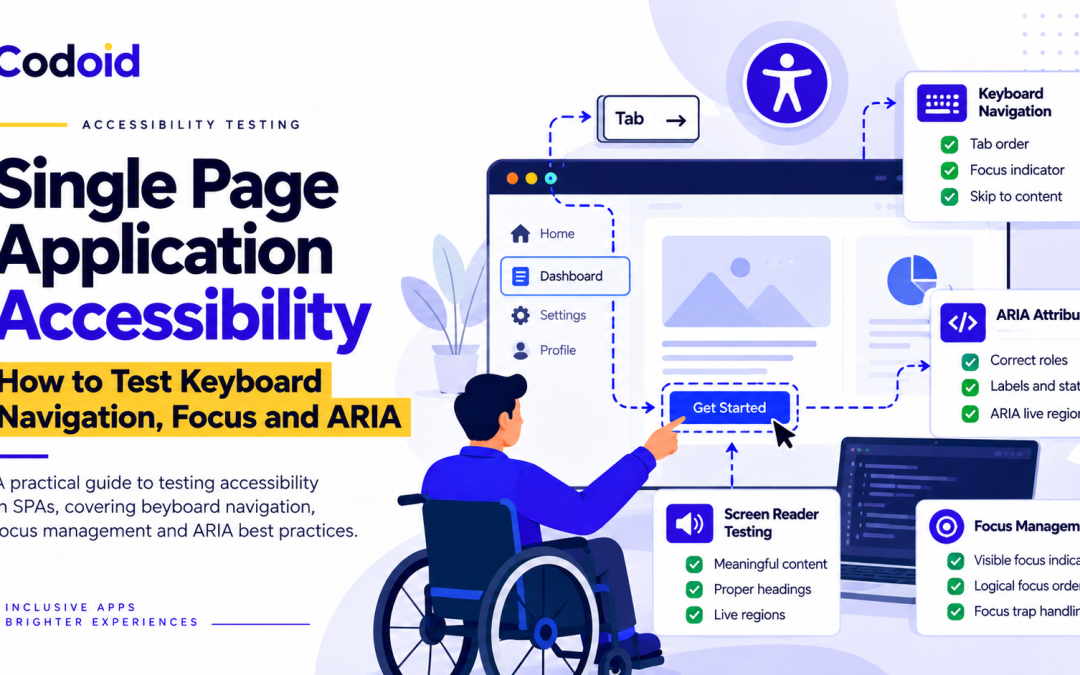
Single-page applications (SPAs) can deliver fast, app-like experiences, but they also change some of the assumptions built into traditional web accessibility testing. Navigation may occur without a full page reload. Components appear and disappear asynchronously. Focus can remain on elements that no longer exist. Visual updates may happen without being announced to assistive technologies. As a result, testing only the initial DOM, or running an automated accessibility scan once after page load, is not sufficient. Single-page application accessibility has to validate what happens between application states, not just what exists in each state.
This guide covers how to test SPAs for keyboard navigation, focus management, dynamic content, and ARIA updates. It combines WCAG 2.2 requirements with practical testing techniques, real tooling examples, and a state-transition matrix that turns vague accessibility review into a repeatable test method.
Codoid’s accessibility testing services apply these same principles to help teams validate SPAs against WCAG 2.2 and real assistive technology.
How Should Accessibility Testing Be Performed for a Single-Page Application?
Single-page application accessibility testing should validate every important UI state transition for four things: keyboard operability, predictable focus, programmatically exposed state changes, and appropriate announcements of dynamic content. Tests should combine keyboard-only and screen-reader testing with automated checks performed after routes, dialogs, filters, validation messages, and other dynamic states have changed.
WCAG 2.2 provides the core requirements: functionality must be keyboard operable, focus order must preserve meaning and operation, focus must remain visible, component names and states must be programmatically available, and status messages must be exposed to assistive technology without unnecessarily taking focus.
Key Takeaways
- Test state transitions, not only routes or static DOM snapshots.
- Complete every critical workflow using only the keyboard and verify both focus order and focus visibility.
- Move focus deliberately when an SPA transition behaves like navigation, but avoid stealing focus for ordinary in-place updates.
- Use ARIA states such as
aria-expanded, aria-selected, and aria-invalid to expose control state; use live regions only when an announcement is actually required.
- Test dynamic status messages with real assistive technology because a correct DOM does not guarantee the expected spoken experience.
- Run automated accessibility checks after important components and states become visible, then supplement them with manual testing.
What Is Single-Page Application Accessibility?
Single-page application accessibility is the process of verifying that users can perceive, understand, navigate, and operate an application as JavaScript changes its interface without traditional full-page navigation.
It includes testing:
- Client-side route changes
- Keyboard navigation and custom widgets
- Programmatic focus movement
- Modals, menus, drawers, tabs, and disclosures
- Loading indicators and progress updates
- Search and filter results
- Form validation
- Toasts and notifications
- ARIA roles, names, properties, and states
- Live-region announcements
- Browser history navigation
- Content added, removed, reordered, or replaced asynchronously
The key difference is timing. A server-rendered page can often be evaluated after it finishes loading. An SPA may expose dozens of materially different accessibility states from the same document. This is why SPA accessibility testing requires a transition-based approach rather than a static one.
WCAG explicitly addresses one SPA-specific consequence under Success Criterion 2.4.2: when distinct SPA views change dynamically, the document title should also change to describe the current view.
Why Is SPA Accessibility Testing Different from Conventional Page Testing?
An SPA frequently preserves the browser document while replacing substantial portions of its contents. That can create a mismatch between what sighted users perceive and what keyboard or assistive-technology users experience.
For example, selecting an Orders navigation link might visually replace a dashboard with an Orders screen. A sighted user immediately sees the new heading. But if keyboard focus remains on the now-removed navigation link, or falls back to the document body, a screen-reader user may receive little useful indication that navigation succeeded.
The same issue occurs at smaller scales:
- A search result count changes without being announced.
- A button visually changes from collapsed to expanded while
aria-expanded remains false.
- A modal appears, but focus stays behind it.
- A modal closes, but focus does not return to a logical control.
- A sticky notification covers the currently focused button.
- A custom menu responds to clicks but has no keyboard interaction model.
- A validation error appears next to a field but is absent from the accessibility tree.
WCAG 2.2 requires keyboard operability under SC 2.1.1, logical sequential focus under SC 2.4.3, visible focus under SC 2.4.7, and, for Level AA, requires a focused component not to be completely obscured by author-created content under SC 2.4.11.
How Does Accessibility Work During an SPA State Transition?
A useful way to test an SPA is to treat each interaction as a pipeline:
    User action
        |
        v
    Application state change
        |
        v
    DOM update
        |
        v
    Focus decision
        |
        v
    Accessibility-tree update
        |
        v
    Assistive-technology output
A defect can occur at any point in that chain.
Consider a product-search filter:
- A keyboard user activates Filters.
- The application opens a filter panel.
- The DOM renders additional controls.
aria-expanded changes from false to true.- Focus either remains on the disclosure button or moves according to the chosen interaction pattern.
- Assistive technology receives the updated expanded state.
- The user changes a filter.
- Search results update asynchronously.
- Focus remains where the user was working.
- A status region announces, for example, “18 products found.”
Testing only step 3 would miss most of the accessibility behavior. This is why SPA accessibility testing must cover the entire pipeline, not just the DOM at rest.
A State-Transition Accessibility Matrix
For every important transition, record and verify the following:
| S. No |
Test dimension |
Question to answer |
| 1 |
Trigger |
Can the action be initiated without a pointer? |
| 2 |
Keyboard model |
Do the expected keys perform the expected actions? |
| 3 |
Focus destination |
Where is focus before and after the transition? |
| 4 |
Focus order |
Is the next sequential focus target logical? |
| 5 |
Focus visibility |
Is the focused component visible and unobscured? |
| 6 |
Semantics |
Does the accessibility tree expose the correct role and name? |
| 7 |
State |
Do properties such as expanded, selected, pressed, or invalid update? |
| 8 |
Announcement |
Does the user need an announcement, and if so, is it appropriately polite or urgent? |
| 9 |
Orientation |
Did the page title, heading, or current-navigation state change when navigation occurred? |
| 10 |
Recovery |
Can the user close, undo, go back, or otherwise leave the new state with the keyboard? |
This matrix turns vague accessibility review into a repeatable test method for single-page application accessibility.
Step-by-Step Process for SPA Accessibility Testing
1. Map Critical Routes, Components, and State Transitions
Start with user workflows rather than individual components.
A useful coverage model includes:
- Entry into a route
- Navigation between SPA views
- Opening and closing overlays
- Expanding and collapsing content
- Submitting forms successfully
- Triggering validation failures
- Starting and completing asynchronous operations
- Filtering or sorting collections
- Adding or deleting data
- Using browser Back and Forward navigation
The goal is to identify every transition where the user’s context, focus target, accessible state, or available information could change.
2. Establish a Semantic Baseline Before Testing Behavior
Before testing interactions, inspect the rendered view for semantic problems such as:
- Missing accessible names
- Invalid ARIA attributes
- Incorrect roles
- Incorrect heading structure
- Duplicate IDs that affect references
- Incorrect
aria-labelledby or aria-describedby references
- Interactive controls incorrectly hidden from the accessibility tree
WCAG SC 4.1.2 requires user-interface components, including script-generated controls, to expose programmatically determinable names and roles and to keep user-settable states, properties, and values available to assistive technologies.
Prefer native HTML controls where they provide the required behavior. W3C’s ARIA Authoring Practices Guide emphasizes that adding an ARIA role does not automatically supply the keyboard behavior users expect from that role.
For example, prefer:
<button type="button">Save changes</button>
over:
<div role="button" tabindex="0">Save changes</div>
The second implementation requires the application to reproduce button keyboard behavior correctly.
How Do You Test Keyboard Navigation in an SPA?
A complete keyboard test answers more than “Can I tab to everything?”
Start from the beginning of each critical workflow and put the pointer aside. Use Tab, Shift+Tab, Enter, Space, Escape, and any arrow-key interactions required by the component pattern.
Verify that:
- Every pointer-driven action has an equivalent keyboard path unless the underlying function inherently depends on path-based movement.
- Focus enters controls in an order that preserves meaning and operability.
- Focus never disappears into non-interactive or hidden content.
- Users can leave ordinary components without becoming trapped.
- Modal interfaces deliberately contain their tab sequence while open.
- Custom composite widgets follow the keyboard conventions associated with their pattern.
- A visible focus indicator remains available.
- Sticky headers, banners, chat widgets, cookie controls, and other overlays do not completely hide the component receiving focus.
These behaviors map directly to WCAG’s Keyboard, Focus Order, Focus Visible, and Focus Not Obscured requirements.
Do Not Assume Every Component Should Use Tab for Every Internal Item
ARIA widgets can have their own keyboard interaction models. For example, some composite widgets use Tab to enter and leave the component and arrow keys for movement inside it.
Implement the interaction model for the component you actually built rather than inventing a keyboard convention. ARIA Authoring Practices Guide documents expected keyboard models for common patterns.
Focus Management and Route Changes
When a route change represents a genuine change of context, consider the following sequence:
- Update the document title.
- Render the destination view.
- Move focus to a meaningful destination such as the main heading or main content container when the navigation represents a genuine change of context.
- Ensure the focus indicator remains visible.
- Continue normal keyboard navigation from that location.
For example:
    <main id="main-content" tabindex="-1">
        <h1>Orders</h1>
    </main>

    function announceRoute(viewTitle) {
        document.title = `${viewTitle} | Example Store`;
        requestAnimationFrame(() => {
            document.querySelector('#main-content').focus();
        });
    }
tabindex="-1" allows an element to receive programmatic focus without adding it to the ordinary sequential tab order.
Do Not Move Focus for Every DOM Update
A route change and a filter update are different.
If a user is typing in a search field and the results refresh underneath it, automatically moving focus to the results can interrupt the task. In that case, focus should normally remain in the input while a status message communicates the result.
A good test question for single-page application accessibility is:
Did this interaction change the user’s context, or did it merely update information within the current task?
Treat those two cases differently.
How Should Focus Work in Dialogs and Modal Overlays?
Modal dialogs need explicit focus behavior.
When a modal dialog opens:
- Focus moves to an appropriate element inside the dialog.
- Tab and Shift+Tab remain within the dialog while it is active.
- Escape normally closes the dialog.
- Content outside the modal is unavailable for interaction.
- The dialog has an accessible name.
aria-modal="true" is used only when the interface actually behaves modally.
When the dialog closes, focus usually returns to the control that opened it, unless the completed action logically makes a different destination more appropriate.
W3C’s modal-dialog pattern documents these behaviors and also notes that initial focus does not always belong on the first button. For long or structurally complex dialog content, a static heading or introductory element with tabindex="-1" can provide a more understandable starting point.
Test both directions: open, interact, close, continue.
A dialog is not accessible merely because focus is successfully trapped inside it; focus also has to enter and exit meaningfully.
How Do You Test ARIA Live Regions Reliably?
Do not test live regions by inspecting markup alone. A live region may contain perfectly valid HTML and still fail to produce a useful announcement in the browser and screen-reader combinations your users rely on.
For reliable behavior, create the live region before the update whenever possible:
<div id="cart-status" role="status"></div>
Later:
    document.querySelector('#cart-status').textContent =
        'Wireless keyboard added to cart';
Assistive technologies generally announce changes to live regions rather than treating their initial contents as updates. MDN recommends establishing the region before changing its content, and W3C techniques similarly demonstrate pre-existing containers for dynamic error messages.
Test actual output for:
- Whether the update is announced
- Whether it is announced once rather than repeatedly
- Whether the complete message is understandable
- Whether it interrupts unrelated speech unnecessarily
- Whether rapid consecutive updates overwrite or flood announcements
- Whether loading and completion messages occur in the expected order
Do not use an assertive live region as a substitute for good focus management.
When Should an Announcement Be Used?
Consider these three cases for SPA accessibility testing:
- The user is already focused on the changed component. If a disclosure button changes from collapsed to expanded, update its state. A separate live-region announcement is generally unnecessary because the component’s state itself can communicate the change.
- Information changes elsewhere without taking focus. This is a common use case for a status message. The
status role has an implicit aria-live="polite" value and an implicit atomic behavior, making it appropriate for advisory updates.
- The information is urgent. Use assertive announcements sparingly.
role="alert" is intended for important, time-sensitive information. Excessive assertive announcements can interrupt the user’s current speech and make an application harder to use.
How Do You Validate ARIA State Updates?
ARIA testing should verify the accessibility tree after interaction, not simply the source attributes before interaction.
Common state transitions include:
| S. No |
Interaction |
State to verify |
| 1 |
Expand or collapse control |
aria-expanded |
| 2 |
Toggle button |
aria-pressed |
| 3 |
Tab or option selection |
aria-selected |
| 4 |
Current SPA navigation item |
aria-current |
| 5 |
Invalid form input |
aria-invalid and associated error information |
| 6 |
Loading region |
aria-busy where appropriate |
| 7 |
Modal dialog |
aria-modal plus correct dialog semantics |
For each state, verify three levels:
    DOM
        |
        v
    Accessibility tree
        |
        v
    Actual assistive-technology experience
A passing DOM assertion alone does not prove that the component is usable.
W3C notes that incorrect ARIA can misrepresent a visual interface to assistive technologies. Native semantics should therefore be preferred where possible.
Practical Example: Testing an SPA Product-Search Workflow
Consider an e-commerce SPA with these interactions:
- /products loads without a full browser refresh.
- A Filters disclosure opens category filters.
- Selecting filters updates results asynchronously.
- A Quick view button opens a modal.
- Selecting a product navigates to a client-side product-details route.
- Adding the item to the cart produces a non-modal confirmation.
Preconditions
The test begins on /products with:
- A descriptive document title
- An
h1 identifying the current view
- A filter disclosure button
- A results region
- An empty status region already present in the DOM
Expected Test Sequence
1. Open Filters With the Keyboard
Expected:
- Enter or Space activates the native button.
- The panel becomes visible.
aria-expanded changes to true.- Focus behavior remains consistent with the disclosure pattern.
2. Select a Filter
Expected:
- The selection is operable with the keyboard.
- Focus remains on the user’s current control unless there is a strong reason to move it.
- Results update.
- A status message such as “18 products found” is announced.
- The user is not forced to navigate through the results to discover that the filter worked.
3. Open Quick View
Expected:
- Focus moves into the modal.
- Keyboard focus cannot move behind it.
- Escape closes it.
- The modal has an accessible name.
- Focus returns to the Quick view button after closing.
4. Open a Product
Expected:
- The SPA route changes.
- The document title changes to the product name.
- The new main view is identifiable.
- Focus is deliberately placed at an appropriate point in the new context.
- The next Tab continues logically.
5. Add the Product to the Cart
Expected:
- The add-to-cart control remains usable.
- A polite status announcement confirms the action.
- Focus is not unexpectedly transferred to the cart or toast unless the interaction explicitly requires that context change.
Typical Failures This Scenario Detects
- Filter button visually opens a panel but leaves
aria-expanded="false".
- Updated result count is visible but silent.
- Modal opens while focus stays on the underlying page.
- Modal closes and focus falls to
body.
- Product route changes while the page title remains “Products.”
- Focused controls disappear after state updates.
- The add-to-cart toast is injected and removed visually without an accessible announcement.
SPA Accessibility Testing vs Traditional Multi-Page Testing
| S. No |
Factor |
Traditional multi-page application |
Single-page application |
| 1 |
Navigation |
Browser loads a new document |
JavaScript may replace a view without reloading |
| 2 |
Page title |
Commonly supplied by the new document |
Must be updated deliberately for distinct SPA views |
| 3 |
Initial focus |
Browser naturally establishes a new document context |
Application may need deliberate focus management |
| 4 |
Dynamic updates |
Often limited |
Common throughout the interaction lifecycle |
| 5 |
ARIA state changes |
Component-dependent |
Frequently tied to reactive state |
| 6 |
Live regions |
Useful for AJAX updates |
Often important for asynchronous status information |
| 7 |
Test timing |
Usually after page load |
After every meaningful UI state transition |
| 8 |
Automation |
Scan each page |
Scan routes plus dynamically revealed and mutated states |
| 9 |
Manual testing |
Still required |
Especially important because focus and announcement timing are behavioral |
The underlying accessibility requirements are not unique to SPAs. What changes is the number and complexity of states that must be exercised.
Best Practices for Testing Accessible SPAs
Test User Journeys Rather Than Isolated Pages
A defect often appears while moving between states. Include accessibility assertions in end-to-end workflows such as checkout, authentication, search, account management, and data-entry processes.
Prefer Native HTML Before Adding ARIA
Native controls provide built-in keyboard and semantic behavior. Use ARIA to communicate semantics or states that native HTML cannot adequately express rather than recreating native behavior unnecessarily. W3C’s APG summarizes this principle as “No ARIA is better than Bad ARIA.”
Separate Focus Changes from Announcements
Moving focus is a major interaction change. Live regions are non-focus announcements. Decide which mechanism matches the event instead of applying both automatically.
Keep Route-Change Logic Centralized
If every feature implements client-side navigation differently, accessibility behavior will drift. Centralize responsibilities such as:
- Document-title updates
- Main-content focus
- Current-navigation state
- Scroll behavior
- Route-loading status
Test the Rendered State, Not Only Component Source
Accessibility defects frequently depend on CSS, portals, overlays, asynchronous rendering, or component composition. Browser-level testing is essential.
Test Actual Browser and Assistive-Technology Combinations
ARIA support is ultimately an interoperability question. Test representative combinations used by the intended audience instead of assuming that correct markup guarantees identical behavior everywhere.
Add Accessibility Checks to Regression Tests
Once a defect is found, for example focus not returning after a modal closes, add an automated assertion where practical so the same behavior does not silently regress. Teams building this layer often benefit from QA automation services that integrate accessibility checks directly into existing pipelines.
Troubleshooting Common SPA Accessibility Problems
Why does focus disappear after client-side navigation?
The previous focused element was probably removed during rendering, leaving the browser without a useful destination.
Verify document.activeElement after navigation and inspect what happens when the originating component unmounts. Then establish a route-transition policy that moves focus to a stable, meaningful destination after the new view renders.
Do not automatically apply the same behavior to simple in-place updates such as filtering.
Why does the screen reader not announce updated search results?
The new content may not qualify as a programmatically exposed status message, or the live region may have been created at the same time as its already-populated message.
Keep a stable role="status" container in the DOM and update its text when the result operation completes. WCAG SC 4.1.3 specifically addresses status messages that should be available to assistive technology without receiving focus.
Why is an ARIA control clickable but unusable with the keyboard?
ARIA changes semantics; it does not automatically implement keyboard behavior.
A div with role="button" still needs the interaction behavior users expect from a button. Whenever possible, replace it with an actual button. For custom widgets that do not have a native equivalent, implement the corresponding APG keyboard pattern.
Why does a modal trap users after it closes?
The application may remove the modal without restoring focus.
Record the invoker when the modal opens and restore focus when it closes, except when the completed action creates a new workflow location that is more logical. W3C’s dialog guidance describes both returning focus to the invoking element and cases where another destination is appropriate.
Why is keyboard focus technically present but invisible?
CSS may remove the browser outline, an overlay may cover the control, or a sticky header or footer may obscure it.
WCAG 2.4.7 requires a visible focus indicator, while WCAG 2.4.11 requires the focused component not to be entirely hidden by author-created content. Test responsive layouts and persistent overlays as well as desktop defaults.
Tools and Implementation Options for SPA Accessibility Testing
Accessibility testing works best as a layered process.
Browser and Accessibility-Tree Inspection
Browser developer tools can help inspect accessible names, roles, properties, computed states, and the accessibility tree. Use them while debugging, but do not treat tree inspection as a replacement for actual interaction testing.
Automated Rule Engines
Tools based on engines such as axe-core can identify many programmatically detectable accessibility problems and can be integrated into component, integration, and browser tests.
W3C cautions that evaluation tools cannot determine accessibility by themselves; some checks require human judgment.
Playwright With axe-core
Playwright’s accessibility-testing documentation demonstrates integrating @axe-core/playwright and recommends scanning UI after interactions reveal the state being tested. It likewise notes that automated testing must be combined with manual assessment.
Example:
    import { test, expect } from '@playwright/test';
    import AxeBuilder from '@axe-core/playwright';

    test('Orders SPA route exposes accessible state', async ({ page }) => {
        await page.goto('/dashboard');

        const ordersLink = page.getByRole('link', { name: 'Orders' });
        await ordersLink.focus();
        await page.keyboard.press('Enter');

        await expect(page).toHaveTitle(/Orders/);

        const heading = page.getByRole('heading', {
            level: 1,
            name: 'Orders'
        });
        await expect(heading).toBeFocused();

        const results = await new AxeBuilder({ page }).analyze();
        expect(results.violations).toEqual([]);
    });
The important idea is that the scan occurs after the route transition, not just on the original dashboard.
ARIA Snapshots
Current Playwright versions can also assert an accessibility-tree representation using ARIA snapshots. This can help detect regressions in roles, accessible names, hierarchy, and ARIA-derived states.
For example:
    await expect(page.getByRole('main')).toMatchAriaSnapshot(`
      - heading "Products" [level=1]
      - button "Filters" [expanded=false]
    `);
ARIA snapshots are useful regression signals, but they do not tell you whether a keyboard workflow makes sense or whether a screen reader announced a live update at an appropriate time.
Manual Screen-Reader Testing
Use representative browser and assistive-technology combinations from your supported environment to verify:
- Initial orientation
- Heading and landmark navigation
- Control names and states
- Client-side route changes
- Dynamic announcements
- Error handling
- Modal behavior
- Reading order
- Focus restoration
A valid ARIA attribute is not the same as a validated user experience.
What Automation Can Validate and What It Can Miss
Automation is strongest at detecting deterministic markup and semantic problems.
It can often identify issues such as:
- Invalid ARIA attributes
- Missing accessible names
- Certain role or property mismatches
- Some structural defects
- Certain contrast failures
It is much weaker at answering experiential questions such as:
- Is this the correct place for focus after navigation?
- Is the focus sequence understandable?
- Is an announcement useful or distracting?
- Did the screen reader announce a dynamic message at the right time?
- Is this custom widget’s keyboard model intuitive and complete?
- Does returning focus here preserve the user’s workflow?
W3C explicitly states that tools cannot automatically check every accessibility aspect and that knowledgeable human evaluation remains necessary.
For that reason, an SPA accessibility pipeline should use automation to increase coverage, not to eliminate manual accessibility testing.
Limitations and Risks
Screen-Reader Behavior Can Vary
Browsers and assistive technologies communicate through platform accessibility APIs. Support can vary by combination, especially for complex ARIA patterns and live-region timing.
Test the environments that matter to your users.
Automated Snapshots Can Become Brittle
Large accessibility-tree snapshots can fail because of legitimate content changes. Prefer focused assertions around important structures and states instead of treating an entire application tree as immutable.
Excessive Focus Management Can Be as Harmful as Insufficient Focus Management
An application that never moves focus can leave users disoriented after route changes. An application that moves focus after every state update can constantly interrupt them.
Base the decision on whether the interaction actually changes context.
Live Regions Can Become Noisy
Multiple independent components producing simultaneous announcements can create a confusing experience. Treat announcements as part of interaction design rather than sprinkling aria-live across the DOM.
APG Examples Are Patterns, Not Drop-In Production Guarantees
W3C notes that APG examples are illustrative and should be tested with the target browser and assistive-technology combinations before production use.
Need Help Testing Accessibility in Your Single-Page Application?
If your SPA handles client-side routing, dynamic content, or complex ARIA patterns, and you need to validate keyboard navigation, focus management, or screen-reader behavior, Codoid can help. Our accessibility specialists test against WCAG 2.2 using real browser and assistive-technology combinations, then integrate automated checks into your regression pipeline.
Talk to an Accessibility Testing Expert
Conclusion
Effective single-page application accessibility testing is fundamentally transition testing. Do not stop at asking whether the rendered DOM contains valid accessibility markup. Verify what happens when users navigate, expand, submit, filter, wait, fail, recover, open overlays, close overlays, and move between client-rendered views.
A reliable testing strategy combines four layers:
- Keyboard-only workflow testing
- Deliberate focus and route-transition testing
- Accessibility-tree and ARIA-state validation
- Screen-reader testing of dynamic announcements
Automated scanners and browser-level assertions should then preserve as much of that behavior as practical in regression tests. The practical next step is to inventory your application’s highest-value state transitions and apply the state-transition accessibility matrix to each one. That produces a test suite based on how the SPA actually behaves rather than treating a highly dynamic application as a collection of static pages.
Codoid’s accessibility testing services can help you build this layered testing model and validate your SPA against WCAG 2.2 and real assistive technology.
Frequently Asked Questions
-
Does every SPA route change need programmatic focus?
Not every DOM update needs focus movement. For a client-side transition that effectively behaves like navigation to a distinct page or view, deliberately establishing a meaningful focus location can help users understand the new context. For an in-place operation such as sorting, filtering, expanding content, or saving a setting, preserving focus is often more appropriate. Evaluate the interaction rather than applying a global "focus after every render" rule.
-
Should an SPA announce every route change with aria-live?
Usually not as a default strategy. Distinct SPA views should have meaningful document titles, and a route may also use deliberate focus management to establish context. Adding a live announcement on top of those signals can create redundant output. Test the actual experience and add an announcement only where it provides information users otherwise miss.
-
What is the difference between focus management and a live region?
Focus management changes the user's active interaction point. A live region allows assistive technology to announce updated information without moving focus. Use focus when the user's context or workflow has genuinely moved; use a live region for relevant background or status information that should be communicated while the user remains where they are.
-
Which ARIA role should be used for a normal success notification?
For a non-urgent status such as "Changes saved" or "12 results found," role="status" is usually appropriate because it provides polite live-region behavior. role="alert" should be reserved for messages requiring immediate attention because assertive announcements can interrupt current speech.
-
How often should accessibility scans run in an SPA?
Run automated checks during development and CI against representative application states, not only once per URL. At minimum, cover critical routes plus dynamically revealed states such as open dialogs, validation errors, expanded controls, authenticated views, and populated search results. Re-run manual keyboard and assistive-technology scenarios when changes affect routing, interaction patterns, overlays, forms, or dynamic messaging.
-
Is correct ARIA enough to make a custom SPA component accessible?
No. Correct ARIA can expose semantics and state, but the component must also provide the expected keyboard interaction, focus behavior, visual presentation, and usable interaction model. W3C specifically warns that assigning an ARIA role does not cause browsers to implement that role's keyboard behavior.
by Rajesh K | Sep 29, 2026 | API Testing, Blog, Latest Post |
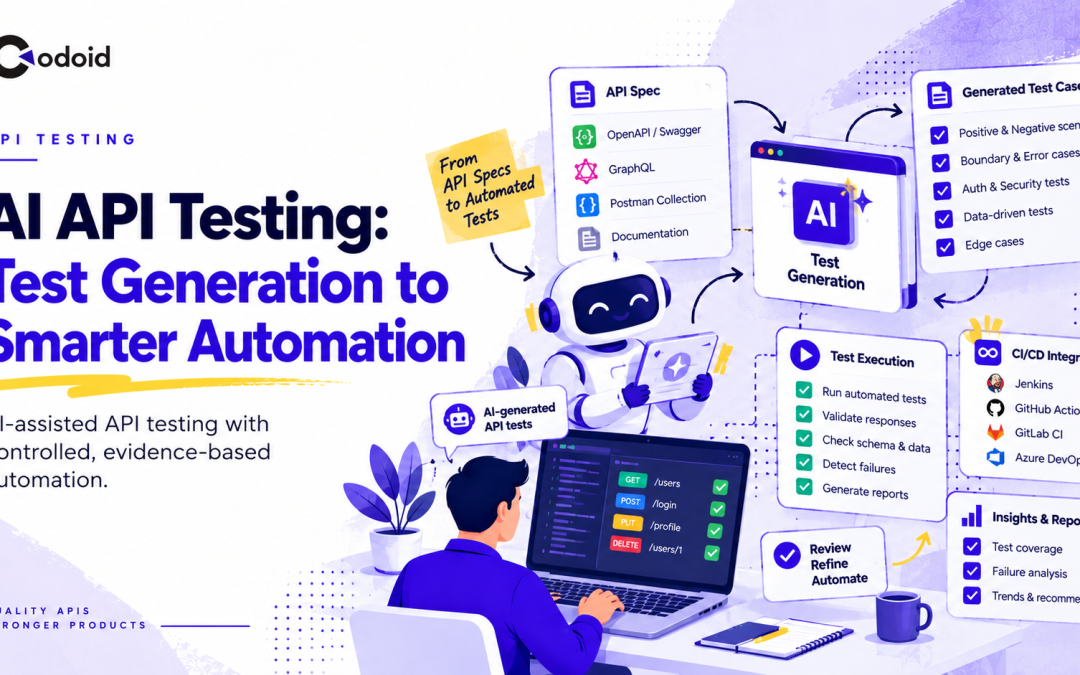
AI API testing starts from a hard truth: an API can return the expected status code, satisfy its response schema, and still behave incorrectly. Imagine an order service that creates two orders when a client retries the same request. Both responses contain valid JSON. Both include legitimate order IDs. A test that checks only the status code and response structure may pass, even though the business operation has been duplicated. Now imagine the opposite problem: hundreds of tests fail because a shared authentication fixture expired. The application may be healthy, but engineers must still separate the underlying setup failure from its downstream symptoms.
These examples illustrate three useful places to apply AI to API testing specifically: deciding what to test, interpreting failures, and coordinating automation. If your team is testing distributed services more broadly, see our related guide on microservices API testing strategy for the layered testing approach this AI layer sits on top of.
How should AI be used in API testing?
The engineering challenge is to gain AI’s capabilities without surrendering control over correctness. AI should propose scenarios and explanations; explicit contracts, approved business rules, and executable assertions should determine pass or fail. Our API and backend testing services team applies this same hybrid model, using AI to widen coverage while keeping every pass/fail decision anchored to a reviewed assertion.
Automated test generation is not inherently AI-driven. Schemathesis generates property-based tests from API schemas, while Microsoft’s RESTler infers dependencies between operations and explores stateful request sequences. These approaches already provide capabilities beyond manually scripted examples.
Language models introduce another mechanism: interpreting descriptive context and proposing domain-relevant combinations. Research systems such as AutoRestTest combine language models with dependency graphs and reinforcement learning rather than relying on unconstrained text generation alone.
A practical implementation should follow the same hybrid principle:
| S. No |
Activity |
Useful AI contribution |
What should remain explicit |
| 1 |
Test case generation |
Interpret requirements and propose scenarios, data variations, and workflows |
Supported operations, fixtures, expected behavior, and safety limits |
| 2 |
Failure analysis |
Organize evidence, suggest related failures, and rank hypotheses |
Observed results, evidence references, and confirmation checks |
| 3 |
Automation |
Recommend test priorities and maintenance changes |
Mandatory coverage, execution permissions, and approval rules |
The goal is not to replace the test framework with a conversational model. It is to place a controlled reasoning layer around established testing infrastructure.
1. Test Case Generation: From API Descriptions to Meaningful Coverage
Ground generation in authoritative context
An OpenAPI description provides a machine-readable starting point: operations, parameters, request bodies, responses, and security requirements. It gives a generator a defined interface to work with instead of requiring it to invent one.
For a useful generation workflow, supplement that interface with approved business rules, authorization policies, fixture definitions, and existing regression tests.
Consider a hypothetical order API. Its relevant context might establish that:
- Quantity must be an integer between 1 and 10.
- Repeating an identical creation request with the same idempotency key must not create another order.
- Customers cannot read another tenant’s orders.
- An order can be cancelled only before shipment.
These rules describe different dimensions of correctness. A request schema can express the quantity constraint, but the generator also needs the approved meaning of an idempotent retry and the permitted lifecycle transitions.
Keep this context versioned. Retrieve documentation for the API revision under test, and record which requirement supports each proposed assertion. When documentation and implementation disagree, report the conflict rather than silently selecting whichever behavior makes the test pass.
Observed behavior is evidence about the system, not automatically the definition of correct behavior.
Generate a coverage model before generating scripts
A useful first output is a scenario matrix, not a directory full of test files.
For the hypothetical order API, ask the model to propose coverage across several dimensions:
| S. No |
Coverage dimension |
Example scenario |
Required oracle |
| 1 |
Valid boundaries |
Create orders with quantities 1 and 10 |
Both values are accepted under the documented contract |
| 2 |
Invalid inputs |
Submit 0, 11, null, or a string quantity |
The documented validation error occurs without creating an order |
| 3 |
Authorization |
Read a real order using another tenant’s identity |
Access is denied according to the approved policy |
| 4 |
Stateful behavior |
Create, cancel, then retrieve an order |
The persisted state reflects the permitted transition |
| 5 |
Idempotency |
Repeat an identical request with the same key |
The same logical order is returned without duplicate creation |
| 6 |
Concurrency |
Submit overlapping requests with the same key |
The documented duplicate-handling invariant holds |
| 7 |
Metamorphic behavior |
Change page size while reading a fixed collection |
The complete result set remains equivalent under a stable snapshot |
Authorization deserves explicit treatment. OWASP describes broken object-level authorization as a failure to verify whether the authenticated user may act on the particular object identified in a request, not merely whether that user can access the endpoint.
For that reason, pair a negative authorization test with a positive control: first establish that the resource exists and its owner can read it, then attempt access using a different identity. Otherwise, a missing fixture could produce a denial response and create false confidence.
Similarly, stateful tests should obtain real resource identifiers from earlier responses instead of guessing them. Schemathesis documents this approach by chaining operations and using response values as inputs to subsequent calls.
Use AI to propose meaningful relationships. Let the runner manage identifiers, credentials, setup, and cleanup.
Keep the test oracle independent
A test oracle is the mechanism that decides whether an observed result is correct.
An AI-generated request without a defensible oracle is an experiment, not yet a reliable regression test.
Use different checks for different questions. Schema validation checks response structure. Business assertions check rules such as “a cancelled order cannot transition to shipped.” State inspection checks whether a failed request created unwanted records. Consumer-driven contracts check interactions that actual clients depend on; Pact, for example, generates contracts from consumer tests and verifies those expectations against providers.
When an exact expected response is unavailable, consider an approved invariant or metamorphic relation. For example, changing pagination size should not change the complete collection returned under the same stable snapshot.
However, the model must not invent that relation. Pagination behavior, ordering guarantees, consistency windows, and filtering rules must support it.
A particularly dangerous workflow is to show the model the application’s current response and ask it to generate the expected response for the same test. That can turn an existing defect into an approved expectation.
Prefer constrained test plans over arbitrary executable code
Instead of immediately requesting Python or JavaScript, ask the model for a declarative plan using an approved vocabulary.
A generation instruction could be:
Using only the supplied API operations, fixtures, and requirement IDs, propose tests for uncovered behavior. Select approved execution templates and assertion references. Do not invent expected status codes. Mark scenarios with missing requirements as unresolved.
An illustrative output might be:
{
"case_id": "order-replay-boundaries",
"operation_id": "createOrder",
"template": "repeat_create_then_query",
"fixture": "isolated_tenant_with_stock",
"parameters": {
"quantity": [1, 10]
},
"assertion_refs": ["ORDER-IDEMPOTENCY-001"],
"source_refs": [
"openapi@api-revision:createOrder",
"order-rules@rules-revision:ORDER-IDEMPOTENCY-001"
]
}
Validate more than JSON syntax. Confirm that the operation exists, the fixture is available, the template permits the requested action, and the assertion reference resolves to an approved rule.
Also distinguish plan validation from API-input validation. Negative tests intentionally contain invalid API inputs. Rejecting every payload that violates the API schema would eliminate precisely the cases a negative-testing workflow needs.
The model proposes the plan; a controlled compiler or reviewed implementation turns it into executable tests.
A practical example: testing idempotent order creation
The following example implements the proposed replay scenario using pytest and HTTPX. Pytest parametrization runs the same behavior against multiple inputs, while an HTTPX client provides shared request configuration and connection management.
This is an illustrative API contract, not a universal definition of idempotency: the first POST /orders returns 201 with a string id. An identical request using the same Idempotency-Key, within its retention window, returns 200 with that same ID. A filtered GET /orders provides a read-after-write-consistent result containing items and total.
The CI environment must provision an isolated tenant, a scoped token, and an in-stock SKU. It must also destroy the tenant after the run, including when tests fail.
# test_orders.py
import os
from collections.abc import Iterator
from uuid import uuid4

import httpx
import pytest


@pytest.fixture
def api() -> Iterator[httpx.Client]:
    required = ("API_TEST_BASE_URL", "API_TEST_TOKEN", "TEST_SKU")
    missing = [name for name in required if not os.getenv(name)]
    if missing:
        pytest.fail(f"Missing test configuration: {', '.join(missing)}")
    with httpx.Client(
        base_url=os.environ["API_TEST_BASE_URL"],
        headers={
            "Authorization": f"Bearer {os.environ['API_TEST_TOKEN']}"
        },
        timeout=httpx.Timeout(10.0, connect=3.0),
        follow_redirects=False,
    ) as client:
        yield client


@pytest.mark.parametrize(
    "quantity",
    [1, 10],
    ids=["minimum-quantity", "maximum-quantity"],
)
def test_create_order_is_idempotent(
    api: httpx.Client,
    quantity: int,
) -> None:
    reference = uuid4().hex
    headers = {"Idempotency-Key": uuid4().hex}
    payload = {
        "sku": os.environ["TEST_SKU"],
        "quantity": quantity,
        "client_reference": reference,
    }
    first = api.post("/orders", json=payload, headers=headers)
    assert first.status_code == 201, (
        f"Initial creation returned {first.status_code}"
    )
    order_id = first.json()["id"]
    assert isinstance(order_id, str) and order_id
    replay = api.post("/orders", json=payload, headers=headers)
    assert replay.status_code == 200, (
        f"Replay returned {replay.status_code}"
    )
    assert replay.json()["id"] == order_id
    listing = api.get(
        "/orders",
        params={"client_reference": reference},
    )
    assert listing.status_code == 200
    result = listing.json()
    assert result["total"] == 1
    assert len(result["items"]) == 1
    assert result["items"][0]["id"] == order_id
    assert result["items"][0]["quantity"] == quantity
With the environment configured, run it using:
python -m pip install pytest httpx
python -m pytest -q test_orders.py
Pin dependencies in the project’s lockfile when adopting the example.
Notice what the test does, and does not, establish. It checks both response identity and the visible number of persisted orders. It does not prove that inventory was reserved only once or that a downstream event was emitted only once. Those effects require additional observers and assertions.
It also tests sequential replay, not overlapping requests. Concurrency testing needs a separate scenario with controlled overlap and its own evidence collection.
Finally, HTTPX’s connect, read, write, and pool timeouts are operation-specific limits, not a complete wall-clock deadline for the test suite. Configure a separate CI execution deadline.
2. Failure Analysis: From Error Messages to Evidence-Backed Hypotheses
Generating tests is only part of the problem. The next challenge is explaining what a failure actually means.
Related cloud-incident research provides a useful architectural example: RCACopilot combines runtime diagnostic collection with language-model-based categorization and explanations. Its results concern cloud incidents, however, and should not be assumed to transfer directly to a particular API test suite.
For API testing, build an evidence-first workflow rather than asking a model to diagnose an isolated stack trace.
Create a structured failure bundle
Before invoking AI, collect the test and requirement revisions, expected and actual results, sanitized request details, fixture identity, execution attempt, deployment version, and relevant diagnostic references.
Include distributed traces when available. OpenTelemetry defines standard HTTP attributes such as http.request.method, http.response.status_code, and the server-side route template http.route, which can provide consistent fields for comparing failures across services.
Keep the bundle focused. A specific assertion, its request sequence, and the relevant downstream spans are generally a better input design than an unrestricted dump of unrelated logs.
Also preserve the distinction between a response and a transport failure. “The API returned an unexpected status” and “the client never received a response” require different investigations.
Separate observations from interpretation
An analysis result should distinguish established facts, hypotheses, alternative explanations, and the next checks needed to discriminate between them.
Suppose a follow-up investigation of the order test produces this illustrative report:
Observed: Two requests used the same tenant, payload, and idempotency key. Both returned 201, with different order IDs. A subsequent state query found two orders.
Hypothesis: The second request bypassed or failed the deduplication lookup.
Alternative explanations: The requests reached instances with inconsistent configuration, or the server calculated different internal key scopes.
Next checks: Compare the computed deduplication keys, inspect the relevant request paths, and repeat against a controlled deployment configuration.
This is useful because every proposed explanation has a verification path.
By contrast, “the cache is broken” is not a root-cause analysis unless the evidence establishes that conclusion.
Require references to the trace, log event, assertion, or configuration supporting each factual observation. Allow the model to return “insufficient evidence.” A confidence number should not replace missing diagnostics.
Group failures without merging unrelated defects
Use deterministic attributes for initial grouping: the violated invariant, normalized exception frames, operation, failing dependency, and deployment revision.
AI can then suggest broader relationships, for example, that several apparently different failures may share an authentication setup problem. Verify those proposed groups against the underlying evidence before treating them as one defect.
Avoid grouping by status code alone. Two 500 responses may have different causes, while a single dependency failure may produce timeouts, validation failures, and unexpected empty responses across the suite.
The same discipline applies to flaky tests. A passing retry does not prove the original failure was harmless. Preserve the first result and investigate whether controlled reruns implicate timing, shared state, infrastructure, or a genuine race condition.
Reduce failures into reproducible regressions
After identifying a meaningful failure, reduce the request sequence and payload while preserving the same violated invariant.
AI can suggest which fields or steps appear unnecessary. The runner must confirm that removing them still reproduces the original failure, not merely some other error.
Save the resulting test artifact, fixture recipe, request sequence, environment revision, and relevant random seeds. Preserve generated identifiers as diagnostic evidence, while recreating valid resources during replay.
The desired output is not just a readable explanation. It is a small, reviewable regression test and enough evidence for an engineer to act.
3. Smarter Automation: Prioritization, Maintenance, and Controlled Execution
The third opportunity is to improve how the suite operates without allowing AI to redefine its obligations.
Prioritize tests using change and risk
Build a mapping between tests, operations, shared schemas, authorization components, and downstream dependencies. Use that mapping to identify which tests a change may affect.
An AI-assisted scheduler can propose priorities using change relevance, business impact, previous defect history, and estimated runtime. Treat those priorities as recommendations within explicit coverage rules.
For example, make critical smoke, authorization, and core lifecycle tests mandatory. Run affected dependency and contract tests next. Reserve a fixed exploration budget for scenarios that the prioritizer did not select, and retain broader scheduled runs.
When dependency metadata is missing, expand execution rather than silently assuming an operation is unaffected.
Do not optimize exclusively around previously failing tests or frequently observed traffic. That would make rare workflows and previously unseen defects easy to neglect.
Make maintenance reviewable, not self-concealing
AI-assisted maintenance should produce a proposed patch with a reason, a supporting requirement, and a visible assertion diff.
Updating a fixture to match an approved request-field change is different from weakening an assertion because the implementation changed unexpectedly.
For example, changing:
assert response.status_code == 403
to:
assert response.status_code in (200, 403)
may make a test pass while removing its ability to detect unauthorized access.
Require review for changes to authorization expectations, accepted status codes, required fields, side-effect checks, and business invariants. Preserve the original failing result so the proposed repair can be evaluated against it.
A green pipeline is not evidence of correctness when the system is allowed to relax its own expectations.
Keep generation separate from routine execution
A practical architecture is:
Versioned API specifications, rules, and fixture definitions
↓
AI-generated test plan
↓
Structural, semantic, and policy validation
↓
Reviewed test artifact
↓
Isolated test runner
↓
Sanitized evidence bundle
↓
AI triage and maintenance suggestions
↓
Reviewed regression update
This separation keeps model availability out of the critical path for already-approved regression tests.
Generate or revise tests when requirements change. Run the saved artifacts normally. Invoke AI analysis for new or meaningfully changed failure groups rather than repeatedly submitting identical failures.
Use deterministic logic where it is sufficient. A model does not need to calculate minimum minus 1 or enumerate a small declared enum. Spend model calls on ambiguous prose, cross-operation relationships, and domain-specific scenarios.
For performance testing, keep workload definitions and acceptance thresholds explicit as well. AI may summarize a latency change or suggest an investigation, but it should not independently redefine a service-level target or excuse a failing result.
Protect the Testing System Itself
An AI-assisted testing pipeline has its own trust boundaries.
API descriptions, response bodies, issue comments, and logs may contain untrusted text. OWASP identifies indirect prompt injection through external content and recommends controls including tool-call validation, least privilege, and human approval for sensitive actions.
Apply those controls outside the model. Restrict execution to approved origins and operations. Keep credentials in the runner rather than in prompts. Cap request volume, concurrency, and resource creation. Do not give generated plans unrestricted shell access or production-wide permissions.
Sanitize data before it enters prompts, retrieval indexes, or stored analysis artifacts. OpenTelemetry’s HTTP conventions recommend explicit configuration of captured headers, and its URL conventions require scrubbing known sensitive query parameters. Those are useful foundations for a deliberately limited diagnostic bundle.
Maintain an audit trail connecting each generated test to its source revisions, generation configuration, approved assertions, and reviewer. The same traceability should apply to AI-proposed maintenance patches.
Measure Defect Detection, Not Generated Test Volume
Evaluate the addition of AI against a meaningful baseline: the existing suite plus conventional schema-based or property-based testing.
Use historical defective builds, controlled fault injection, and held-out incidents. Keep incident resolutions out of the triage model’s input when evaluating whether it can diagnose those incidents.
Useful measures include:
| S. No |
Measure |
What it reveals |
| 1 |
Executable, applicable proposals divided by all proposals |
Whether generation produces usable scenarios rather than merely valid-looking output |
| 2 |
Confirmed new defects per fixed execution and review budget |
Whether the AI layer adds value beyond existing coverage |
| 3 |
Detection of eligible seeded faults or mutants |
Whether generated assertions respond to deliberately introduced defects |
| 4 |
Correct triage recommendations, alongside abstention rate |
Whether explanations are actionable and appropriately cautious |
| 5 |
Reproduction and flaky-failure rates |
Whether results remain dependable across controlled runs |
| 6 |
End-to-end cost and time to an actionable diagnosis |
Whether operational gains outweigh model and review overhead |
Deduplicate defects rather than counting every failing request as a discovery. Include rejected and unexecutable proposals in generation-quality measurements.
Evaluate generation and diagnosis separately. A system may propose useful tests while producing weak explanations, or diagnose failures well while adding little new coverage.
Start with reviewed test proposals and non-blocking triage suggestions. Expand automation only after measuring their performance on the actual service, and repeat the evaluation when models, prompts, or retrieval logic change.
Conclusion
AI API testing is most useful when it helps engineers ask better questions and work through evidence more effectively. For test case generation, ground proposals in versioned contracts, business rules, and realistic workflows. For failure analysis, require observations, evidence references, competing hypotheses, and reproducible checks. For smarter automation, use AI to recommend priorities and maintenance changes while keeping coverage obligations, permissions, and assertions under explicit control.
The strongest outcome is not the largest generated test suite. It is a collection of meaningful tests whose failures are reproducible, whose expectations are defensible, and whose results engineers can trust. Talk to our API testing team if you want help building this into your own pipeline.
Frequently Asked Questions
-
What is the safest way to use AI for API test case generation?
Ground generation in a versioned OpenAPI description plus approved business rules, authorization policies, and fixtures, rather than letting the model invent its own interface. Ask for a declarative test plan referencing approved operations and assertion IDs first, and let a controlled compiler or reviewed implementation turn that plan into executable tests.
-
Why shouldn't AI generate the expected result from the application's current response?
If a model is shown the application's current output and asked to produce the "expected" value for that same test, it can turn an existing defect into an approved expectation. Expected results should come from approved examples, independently reviewed calculations, or a trusted reference implementation instead.
-
How should AI be used to analyze API test failures?
Build an evidence-first workflow: collect a structured failure bundle (request details, fixture identity, deployment version, distributed traces) before invoking AI, then require the analysis to separate established facts from hypotheses and alternative explanations, each with a verification path. Allow the model to say "insufficient evidence" rather than forcing a confident-sounding guess.
-
Can AI safely rewrite or relax a failing test's assertions?
Only under review. Changing an assertion like status_code == 403 to status_code in (200, 403) can make a test pass while removing its ability to detect unauthorized access. AI-assisted maintenance should produce a proposed patch with a reason and a visible assertion diff, not silently weaken the check to get a green pipeline.
-
What security risks does AI introduce into an API testing pipeline?
API descriptions, response bodies, and logs can contain untrusted text that attempts indirect prompt injection. Controls like tool-call validation, least-privilege execution, keeping credentials in the runner rather than in prompts, and requiring human approval for sensitive actions should be enforced outside the model, not requested from it.
-
How do you measure whether AI is actually improving an API test suite?
Track confirmed new defects found per execution and review budget, the rate of executable versus rejected proposals, detection of seeded faults or mutants, and reproduction and flaky-failure rates, evaluated against a baseline of the existing suite plus conventional schema-based testing. Generated test volume alone is not a useful measure.
by Rajesh K | Sep 28, 2026 | Artificial Intelligence, Blog, Latest Post |
AI test cases can compile, pass in continuous integration, and still verify the wrong behavior. That gap exists because research on generated test oracles, the logic that decides whether a result is correct, has found that models can reproduce what a program currently does rather than what it is supposed to do. A passing test may therefore preserve a defect instead of detecting it. Execution success and testing value are also different outcomes. In a 2024 evaluation of Meta’s TestGen-LLM on Instagram’s Reels and Stories products, 75% of generated test cases built correctly, 57% passed reliably, and 25% increased coverage. Those are results from a particular system and evaluation, not expected success rates for every generator, but they illustrate why AI test cases need several independent checks.
Treat AI test cases as proposed changes to your verification system, not as trusted evidence merely because they look plausible.
How do you evaluate AI test cases before using them?
A practical acceptance framework should answer four questions: does the test check the intended behavior with a justified expectation (accuracy), which important behaviors does it actually exercise and verify (coverage), does it add useful verification beyond existing tests (redundancy), and can it run safely and reproducibly (executability). Our LLM testing services team applies this same four-dimension framework when qualifying AI test cases for clients.
| S. No |
Dimension |
Question to answer |
Evidence to inspect |
| 1 |
Accuracy |
Does the test check the intended behavior using justified expectations? |
Requirements, oracle provenance, input validity, assertion review |
| 2 |
Coverage |
Which important behaviors and failure modes does it actually exercise and verify? |
Scenario traceability, branch coverage, mutation results, known-defect checks |
| 3 |
Redundancy |
Does it add useful verification beyond existing tests? |
Semantic comparison, per-test coverage, fault-detection overlap, removal experiments |
| 4 |
Executability |
Can it run safely and reproducibly in the intended environment? |
Discovery results, setup and teardown outcomes, dependency checks, repeated runs |
These dimensions should remain separate. High coverage cannot compensate for an incorrect expected result. Reliable execution cannot justify a test that asserts nothing meaningful.
Key takeaways
- A passing AI-generated test is not proof of correctness; the oracle behind the assertion needs independent review.
- Build your scenario inventory from the approved contract first, not from what the generator happened to produce.
- Redundancy is a semantic question, not a text-similarity question; two differently worded tests can check the same thing, and two similar-looking tests can protect different boundaries.
- Executability includes discovery, setup, teardown, and stability under realistic conditions, not just “the test passed once.”
- Score accuracy, coverage, redundancy, and executability separately. Do not collapse them into one AI-test-quality score.
Start With an Approved Contract
Before evaluating generated output, define what the tests are allowed to treat as authoritative.
That usually means a versioned combination of acceptance criteria, API contracts, business rules, approved examples, and architectural constraints. Use implementation code to understand interfaces and execution paths, but do not automatically treat its current output as the correct answer.
Consider a shipping service with the following illustrative contract:
| S. No |
Requirement |
Approved behavior |
| 1 |
SHIP-1 |
Standard orders with a subtotal of at least 5,000 cents have free shipping. |
| 2 |
SHIP-2 |
Standard orders below 5,000 cents incur a 499-cent shipping fee. |
| 3 |
SHIP-3 |
Premium orders with nonnegative subtotals have free shipping. |
| 4 |
SHIP-4 |
Negative subtotals raise ValueError, regardless of membership. |
Assume the application accepts integer subtotals and exposes:
shipping_fee(subtotal_cents: int, *, premium: bool) -> int
This contract gives reviewers something concrete to evaluate. It also identifies what is not specified. For example, behavior for strings, floating-point inputs, or None needs clarification rather than an invented expectation.
Keep the generation context alongside the candidates: the requirement revision, source commit, existing-suite revision, model and prompt versions, and any supplied examples. Record unresolved assumptions explicitly.
For manual test cases, require concrete preconditions, test data, actions, expected results, and cleanup instructions. “Verify that shipping works correctly” is not an executable procedure.
For automated cases, require the same information, with a clear mapping to fixtures, application calls, and assertions.
1. Accuracy: Does the Test Verify the Right Behavior?
Accuracy begins with the test oracle, not the test name.
A scenario titled test_free_shipping_threshold might look relevant while asserting the wrong threshold behavior. Review the relationship between its preconditions, inputs, actions, and expected results.
Validate Expectations Independently
Under the shipping contract, this generated assertion is incorrect:
# Incorrect: exactly 5,000 cents qualifies for free shipping.
assert shipping_fee(5000, premium=False) == 499
The assertion is syntactically valid. It might even pass against a faulty implementation using subtotal > 5000. Neither fact makes the test correct.
A different candidate might contain a true but insufficient assertion:
# Too weak to verify either the threshold or the correct fee.
assert shipping_fee(5000, premium=False) >= 0
This test accepts both 0 and 499. It cannot distinguish correct threshold behavior from the defect above.
That distinction matters: an assertion can be logically true without adequately verifying the requirement it claims to cover.
For each candidate, ask: what plausible incorrect implementation would this test reject? A reviewer should be able to identify a specific answer: an off-by-one threshold, the wrong fee, an unauthorized state change, an omitted database write, or another relevant failure.
Watch for Circular Verification
A generated test can also calculate its expected result from the same system it is supposed to verify:
expected = shipping_fee(5000, premium=False)
actual = shipping_fee(5000, premium=False)
assert actual == expected
This checks repeatability for that input, not compliance with the shipping rules.
The same problem appears when generated tests copy production calculations into their expected-value logic or mock the function under test and then assert the mocked return value.
Prefer expectations justified by approved examples, independently reviewed calculations, or a trusted reference implementation. Differential testing against another implementation is useful evidence, but agreement between implementations is not proof that both satisfy the contract.
Likewise, ask a second model to identify suspicious assertions, but do not treat model agreement as independent ground truth.
Review the Whole Scenario
Oracle review alone is insufficient. A correct expected result attached to the wrong setup still makes a misleading test.
Suppose a scenario claims to verify standard-account shipping, but its fixture creates a premium account. An expected zero fee might pass for the wrong reason.
Inspect account roles, feature flags, initial state, request payloads, and mocked dependencies. For state-changing operations, check the relevant side effects as well as the immediate response. A successful API response and a correctly persisted order are different observations.
When evaluating existing behavior during a legacy-system migration, distinguish characterization tests, which record current behavior, from requirements tests, which assert intended behavior. Do not silently promote the former into proof of the latter.
Use a Review-Based Accuracy Metric
A practical metric is:
Validated-case rate = (Cases confirmed semantically valid ÷ Cases reviewed) × 100
Classify reviewed cases as valid, incorrect, or unresolved. Keep unresolved cases in the denominator rather than making uncertainty disappear.
For example, if 80 of 100 reviewed cases are valid, 12 have incorrect expectations, and eight depend on unresolved requirements, the validated-case rate is 80%. The unresolved 8% should be reported separately.
This is a measure of review outcomes, not an estimate of the application’s correctness. Report whether the review covered every candidate or a sample, and examine high-risk cases individually.
2. Coverage: What Does the Suite Actually Verify?
Coverage needs more than one view.
Code coverage describes execution. Requirements coverage describes which obligations have tests. Fault-detection evidence describes whether those tests reject relevant incorrect behavior.
Google’s testing guidance explicitly warns that covered lines and branches have been executed, but have not necessarily been tested correctly. It recommends using coverage alongside other evidence rather than treating it as a complete measure of test quality.
Build the Scenario Inventory Independently
Do not ask the generator to create tests and then judge completeness only against the scenarios it generated.
Create a reviewed inventory from the contract first. For the shipping service, useful obligations include:
| S. No |
Scenario |
Expected outcome |
Why it matters |
| 1 |
Standard account, subtotal 4999 |
Fee 499 |
Immediately below the threshold |
| 2 |
Standard account, subtotal 5000 |
Fee 0 |
Exact inclusive boundary |
| 3 |
Standard account, subtotal 5001 |
Fee 0 |
Immediately above the threshold |
| 4 |
Standard account, subtotal 0 |
Fee 499 |
Lowest nonnegative subtotal |
| 5 |
Premium account, subtotal 0 |
Fee 0 |
Membership overrides the standard fee |
| 6 |
Negative subtotal, standard account |
ValueError |
Input validation |
| 7 |
Negative subtotal, premium account |
ValueError |
Validation still applies to premium accounts |
The last scenario protects a different failure mode from the preceding one. An implementation could return free shipping for premium customers before validating the subtotal.
For a larger application, extend the inventory to state transitions, permissions, retries, partial failures, configuration combinations, and integration boundaries. Define nonfunctional obligations separately. A unit-test suite cannot establish a latency requirement without a suitable workload, measurement method, and environment.
Measure Coverage Against Explicit Obligations
A useful scenario-coverage measure is:
Scenario coverage = (Applicable obligations with valid, executed checks ÷ Total applicable obligations) × 100
A requirement ID in a comment is not enough. The test must actually exercise the scenario and evaluate a relevant outcome.
Also distinguish planned coverage from demonstrated coverage. A reviewed test that cannot run represents planned verification, not completed evidence.
For risk-sensitive systems, use a weighted version:
Risk-weighted coverage = (Σ wi × ci ÷ Σ wi) × 100

where wi is a pre-agreed risk weight for obligation i,
and ci is 1 when the obligation has a valid, executed check, and 0 otherwise.
Set weights before evaluating the generated suite. Otherwise, changing weights can become another way to improve the dashboard without improving testing.
Keep critical gaps visible individually. An aggregate score should not conceal an untested authorization rule.
Finally, coverage is not a pass rate: a valid test that exposes a product defect can cover an obligation while showing that the implementation violates it.
Measure Incremental Code Coverage
Evaluate candidates against the existing suite:
Incremental coverage = coverage(existing suite + candidates) − coverage(existing suite)
Keep the source revision, measurement scope, exclusions, and environment constant.
Prefer branch information where decisions matter. Coverage.py’s documentation illustrates how statement coverage can report all lines executed even when one outcome of an if condition was never taken; branch measurement exposes that missing transition.
Inspect which branches were added, not only the percentage-point increase. Newly executed error-handling logic may be more valuable than additional incidental initialization coverage.
Conversely, zero additional branch coverage does not automatically make a candidate useless. A stronger assertion may detect a defect on a path the existing suite already executes.
Test the Tests With Mutations
Mutation testing introduces controlled changes to application code and checks whether the tests detect them. A mutant is typically considered killed when the altered program causes a test to fail. PIT and Stryker document this approach as a way to assess test effectiveness beyond execution coverage.
For the shipping service, useful mutations include changing >= 5000 to > 5000, returning the wrong fee, removing negative-input validation, or allowing the premium check to bypass validation.
Measure which baseline-surviving mutants the candidates newly detect. Keep mutation operators and the evaluated code scope fixed when comparing suites.
Inspect result categories, not just the headline score. Tools can distinguish killed, surviving, uncovered, invalid, and timed-out mutants, and their scoring conventions matter. Equivalent mutants, changes that do not alter observable behavior, also limit the interpretation of a perfect-score target.
A mutant failing because the test environment crashed is not the same evidence as a targeted assertion detecting the intended behavioral change.
Add Properties Where They Strengthen the Contract
Property-based testing can complement concrete examples by generating inputs from a defined domain and searching for violations of an asserted property. Hypothesis supports this style of testing in Python.
For the illustrative contract, a reviewed property could state that the fee for a standard account never increases when a nonnegative subtotal increases.
That property is useful, but insufficient alone: an implementation returning zero for every subtotal would satisfy it. Retain concrete examples for exact fees and boundaries.
Generated properties and metamorphic relationships need oracle review just as much as generated example-based assertions.
3. Redundancy: Does Each Test Add Useful Evidence?
Redundancy is not the same as textual similarity.
Two differently named tests may perform the same setup, use inputs from the same partition, and assert the same outcome. Conversely, two almost identical tests at 4999 and 5000 protect different sides of a boundary.
Evaluate duplication both within the generated batch and against the existing suite.
Compare Semantics Before Deleting Tests
A useful comparison record includes the requirement, initial state, input partition, action, expected outcome, assertion target, and test layer.
Text similarity, embeddings, or normalized syntax trees can help identify candidates for review. Treat their output as a shortlist, not a deletion decision. Normalization that removes literal values can erase the difference between an ordinary input and a critical boundary.
Where available, add execution evidence. Coverage.py can record measurement contexts, allowing execution information to be associated with individual tests or other contexts.
However, identical execution coverage is still not proof of redundancy. One test might check a response code while another checks that no unauthorized state change occurred.
Use Controlled Removal Experiments
A defensible removal process is to temporarily remove a suspected duplicate, rerun the relevant evidence checks, and compare what was lost.
Evaluate scenario coverage, important mutant kills, known-defect detection, and diagnostic usefulness. Preserve deliberate verification at different layers when it protects distinct risks, for example, a unit test for a calculation and an integration test for the API’s mapping of that result.
Remove candidates incrementally. If two tests are interchangeable, either may be removable individually, but deleting both can create a gap.
A practical reporting metric is:
Redundancy reduction rate = (Candidates removed as unnecessary duplicates ÷ Valid, executable candidates before deduplication) × 100
Record the evidence supporting each removal. This measures redundancy under the chosen evaluation criteria, not universal equivalence under every future code change.
Parameterization is often a better outcome than deletion. It reduces repeated test code while preserving separate input scenarios and failure identities.
The objective is useful verification at reasonable maintenance and execution cost, not the smallest possible test count.
4. Executability: Can the Test Run Safely and Reproducibly?
Executability has several stages: discovery, dependency resolution, setup, application interaction, outcome evaluation, and cleanup.
A test that parses successfully has completed only an early check.
Review Before Running
Inspect generated imports, fixtures, API calls, selectors, dependency changes, filesystem operations, and external requests.
Reject or repair candidates that invent helper methods, reference unavailable fixtures, require undocumented accounts, or depend on local state that CI does not have. Do not automatically install every package a generated test requests.
Treat generated code as untrusted during evaluation. OpenAI’s HumanEval repository, for example, explicitly warns against executing model-generated code outside a robust security sandbox.
Use a security-reviewed disposable environment with synthetic data, restricted credentials, controlled network access, and resource limits. Do not expose production secrets, privileged host interfaces, or unrestricted write access.
Place test collection inside that boundary too: pytest imports test modules as part of its integration and discovery behavior, so collection should not be treated as passive text inspection.
Confirm That the Intended Tests Actually Ran
Compare expected scenario IDs with collected and executed IDs. A successful job is insufficient when the intended tests were skipped, deselected, or never discovered.
Pytest supports collection-only inspection and reports a distinct exit code when no tests are collected. Its skip and expected-failure mechanisms also require explicit review: an expected failure is not an ordinary passing assertion.
Track setup errors, assertion outcomes, teardown errors, skipped cases, expected failures, and unexpected passes separately.
A useful metric is:
Executable-case rate = (Scheduled cases that reach a verdict and complete cleanup ÷ Cases scheduled for execution) × 100
An assertion failure can still be a valid execution outcome. A missing fixture is a different category.
Investigate Failures Before Repairing Tests
When a candidate fails, determine whether the cause is an incorrect test, a product defect, an environment problem, or an unresolved contract.
Do not replace an expected value with the observed value merely to obtain a green run.
A valid test exposing a confirmed defect should enter the defect-management workflow. Preserve it as a reproducer and, after the fix, as regression protection. Any temporary expected-failure treatment should have an owner, a linked issue, and a removal condition.
This distinction prevents a generator’s “repair” loop from turning defect detection into defect acceptance.
Evaluate Stability Under Meaningful Variations
Run candidates in isolation, with the existing suite, in different orders, and under the intended parallelism. Control or record clocks, time zones, random seeds, database state, and external-service behavior.
Pytest’s documentation identifies insufficiently controlled state, ordering dependencies, cleanup problems, and overly strict assertions as potential causes of flaky tests.
For UI tests, prefer observable readiness conditions over arbitrary sleeps. Playwright supports actionability checks and retrying assertions; its guidance recommends resilient locators based on user-facing attributes and explicit contracts.
Report the number and conditions of repeated runs. “No failures observed in 20 runs” is evidence, not proof of determinism. Under independent runs with a true 1% failure probability, the probability of seeing 20 consecutive passes is:
Retries should not erase the first failure from evaluation records. Distinguish a consistently passing test from one that passes only after reruns.
For manual cases, perform an independent walkthrough using the documented environment and data. When an evaluator must invent missing steps, the procedure is not yet executable as written.
A Worked Example: From Contract to Reviewable Tests
For the illustrative application interface, the shipping scenarios can be expressed as follows:
# tests/generated/test_shipping.py
import pytest
from checkout.shipping import shipping_fee

@pytest.mark.parametrize(
    ("subtotal_cents", "premium", "expected_fee"),
    [
        pytest.param(0, False, 499, id="SHIP-2-zero"),
        pytest.param(4999, False, 499, id="SHIP-2-below-threshold"),
        pytest.param(5000, False, 0, id="SHIP-1-at-threshold"),
        pytest.param(5001, False, 0, id="SHIP-1-above-threshold"),
        pytest.param(0, True, 0, id="SHIP-3-premium-zero"),
    ],
)
def test_shipping_fee(
    subtotal_cents: int,
    premium: bool,
    expected_fee: int,
) -> None:
    actual_fee = shipping_fee(subtotal_cents, premium=premium)
    assert actual_fee == expected_fee

@pytest.mark.parametrize(
    "premium",
    [
        pytest.param(False, id="standard"),
        pytest.param(True, id="premium"),
    ],
)
def test_negative_subtotal_is_rejected(premium: bool) -> None:
    with pytest.raises(ValueError):
        shipping_fee(-1, premium=premium)
Pytest parameterization supports executing a test function with multiple argument sets and distinct case identifiers.
This module represents seven scenarios, not two merely because it contains two test functions.
Its expected values come directly from the stated contract. The threshold cases protect different boundaries, while the negative-input cases check that membership does not bypass validation.
It remains a candidate suite until it runs against the actual application and its contribution is compared with existing tests. It makes no claim to cover API serialization, checkout persistence, or other behavior outside this function’s contract.
Collect Execution Evidence Without Hiding Failures
For a repository containing the illustrative checkout package, the following shell script captures execution and coverage artifacts. Run it from the repository root inside the approved sandbox, with the application and approved versions of pytest and Coverage.py already installed.
#!/usr/bin/env bash
mkdir -p artifacts || exit "$?"

# Discovery must succeed before execution.
python -m pytest tests/generated --collect-only -q || exit "$?"

run_status=0
python -m coverage run --branch --source=checkout \
  -m pytest tests/generated \
  -q -ra --strict-markers \
  --junitxml=artifacts/generated.xml || run_status=$?

# Attempt to retain coverage evidence even when tests fail.
report_status=0
python -m coverage json \
  -o artifacts/generated-coverage.json || report_status=$?

# A successful report command must not hide a failed test run.
if [ "$run_status" -ne 0 ]; then
  exit "$run_status"
fi

exit "$report_status"
Coverage.py supports running Python modules under measurement, limiting source scope, and exporting JSON reports.
This script collects evidence; it is not a complete acceptance gate. CI must still audit expected versus executed cases, review skips and expected failures, evaluate security constraints, and enforce the agreed coverage policy.
Run baseline-only and combined-suite measurements separately, using clean coverage data and identical settings, to calculate incremental value.
Turn the Evaluation Into an Acceptance Gate
Use a staged workflow: quarantine candidates, validate their contracts and code, execute them safely, measure their contribution, review the evidence, and then promote selected tests.
The following is an example policy to adapt to the application’s risk, not an industry-standard threshold:
| S. No |
Dimension |
Example promotion condition |
| 1 |
Accuracy |
Every retained case has an approved oracle, correct setup, and no unresolved material assumptions. |
| 2 |
Coverage |
Pre-agreed critical obligations have demonstrated checks; remaining gaps and incremental contributions are documented. |
| 3 |
Redundancy |
Each retained case adds a distinct check or has a documented reason for deliberate overlap. |
| 4 |
Executability |
Every retained case is discoverable, safe, reproducible under the evaluation conditions, and has a triaged outcome. |
Do not collapse these conditions into one weighted “AI test quality” score. A serious failure in one dimension should remain visible.
Separate candidate yield from the quality of the accepted suite. Keep counts of initial candidates, rejected cases, repaired cases, duplicates removed, confirmed defects discovered, and tests promoted. Otherwise, repeated regeneration can make the final output look strong while concealing substantial review effort.
Attach evidence to retained tests: their requirement and oracle sources, relevant code and environment revisions, execution results, incremental verification value, reviewer, and maintenance owner.
Acceptance also needs lifecycle management. Re-evaluate generated tests when contracts, interfaces, fixtures, or dependencies change, just as you would other verification code.
Conclusion
AI test cases should earn a place in QA through evidence. Accuracy establishes that the test checks the intended behavior. Coverage shows which obligations it verifies. Redundancy analysis explains why it belongs alongside existing tests. Executability demonstrates that the check can run safely and produce interpretable results.
The most useful acceptance question is not, “How many tests did the model generate?” It is: “Which important failures can this suite now detect, and what evidence shows that those checks are correct, necessary, and reliable?” Talk to our LLM testing team if you want help building this evaluation gate into your own pipeline.
Frequently Asked Questions
-
Why can't a passing AI-generated test be trusted on its own?
A test can compile, pass in CI, and still verify the wrong behavior if its expected result (the oracle) was derived from the current implementation rather than the actual requirement. Research on LLM-generated test oracles has found models are more likely to capture what a program currently does than what it is supposed to do, so a passing test can preserve a defect instead of catching it.
-
What are the four dimensions of AI test case evaluation?
Accuracy (does the test check the intended behavior with a justified expectation), coverage (which important behaviors and failure modes it actually exercises), redundancy (does it add useful verification beyond existing tests), and executability (can it run safely and reproducibly). These should be scored separately rather than combined into one overall quality score.
-
How do you know if an AI-generated test is redundant?
Redundancy is a semantic question, not a text-similarity question. Two differently worded tests can perform the same setup and assert the same outcome, while two nearly identical tests can protect different boundaries. Use controlled removal experiments, temporarily removing a suspected duplicate and comparing scenario coverage, mutant kills, and defect detection, rather than deleting based on similarity alone.
-
Can mutation testing help evaluate AI-generated tests?
Yes. Mutation testing introduces controlled changes to the application code and checks whether the candidate tests detect them. A mutant is considered killed when the change causes a test to fail, which measures whether a test can actually catch relevant incorrect behavior, something code coverage alone cannot show.
-
How should AI-generated tests be run before trusting them?
Treat generated code as untrusted during evaluation. Run it in a security-reviewed disposable environment with synthetic data and restricted credentials, confirm the intended tests were actually discovered and executed rather than skipped, and check stability across repeated runs, different orders, and realistic parallelism before promoting a test into the suite.
by Rajesh K | Sep 25, 2026 | Mobile App Testing, Blog, Latest Post |
Mobile applications operate in one of the most fragmented environments in software. iOS and Android devices vary by manufacturer, operating system version, screen size, memory tier, and hardware capability. A feature that works perfectly on a flagship phone can fail silently on a low-RAM device, a foldable, or an older but still widely used operating system version. For QA leaders, this creates a difficult resourcing question. Building an in-house lab large enough to cover this fragmentation is expensive, and maintaining it requires constant investment. That is why outsourced mobile app testing has become a practical option for many product teams. An external provider can supply device coverage, specialized testers, and structured reporting without the overhead of owning every configuration.
However, outsourcing introduces its own risks. A loosely written engagement can leave critical questions unanswered. Which devices are covered? How long does a cycle take? What evidence is delivered? How quickly must a critical defect be reported? This guide addresses those questions directly. It covers scope definition, device matrix construction, deliverables, timelines, service level agreements, and exit criteria so that an outsourcing engagement becomes a measurable quality process rather than a vague promise. Codoid’s mobile app testing services follow the same structured approach described in this guide, combining analytics-driven device selection with clear reporting and defined release criteria.
What Should an Outsourced Mobile App Testing Engagement Include?
Outsourced mobile app testing should define what will be tested, which devices and operating systems will be covered, what evidence the testing vendor must deliver, how long each test cycle should take, and the service level agreements (SLAs) governing communication, defect handling, and retesting.
Device coverage should not be based on an arbitrary list of popular phones. A defensible mobile test matrix uses first-party audience analytics to prioritize actual device models, manufacturers, operating system versions, screen configurations, and hardware characteristics used by the application’s customers.
Key Takeaways
- Define the test scope before agreeing to price, team size, or schedule.
- Build the device matrix from product analytics rather than testing an equal number of devices from every manufacturer.
- Cover current, dominant, previous, and minimum-supported OS versions according to actual audience distribution and release risk.
- Include screen and window-size variation, not only different physical phone models.
- Deliberately include constrained hardware when memory, storage, camera, Bluetooth, NFC, biometrics, or other device capabilities affect the app.
- Make test reports, defect evidence, coverage reports, retest results, and release-risk summaries explicit contractual deliverables.
- Separate SLAs, which govern service responsiveness, from exit criteria, which determine whether testing is complete enough to support a release decision.
What Is Outsourced Mobile App Testing?
Outsourced mobile app testing is an engagement in which an external QA provider assumes responsibility for agreed mobile testing activities, environments, device coverage, execution, defect reporting, and test evidence.
The engagement can range from a one-time compatibility assessment to continuous QA integrated with the development team’s release pipeline.
A typical scope may include:
- Functional testing
- Compatibility testing
- Regression testing
- Installation, upgrade, and uninstall testing
- Exploratory testing
- Mobile UI testing
- Network-condition testing
- Interruption and background-state testing
- Localization testing
- Accessibility checks
- Mobile performance and resource-use testing
- Camera, GPS, Bluetooth, NFC, biometric, sensor, and other hardware-dependent flows
- Automated regression execution when automation is included in the contract
Outsourcing mobile testing does not automatically mean the supplier is responsible for penetration testing, back-end load testing, compliance certification, source-code review, user-acceptance testing, or production monitoring. Those responsibilities should be added explicitly when required.
For example, Firebase Test Lab explicitly notes that its mobile device infrastructure is not intended for load-testing an application’s back-end servers. Mobile client testing and back-end performance testing therefore need separate scope definitions.
Why Does Mobile App Testing Scope Matter When Outsourcing?
A loosely written statement such as “test the Android and iOS apps before release” leaves several commercially important questions unanswered.
- Does the supplier test two devices or twenty?
- Are tablets included?
- Are foldables included?
- Is testing limited to the latest OS?
- Who decides which bugs block release?
- How quickly must a critical defect be reported?
- Does the supplier rerun the entire regression suite after every build or only failed tests?
These ambiguities influence cost, release risk, and turnaround time.
Mobile fragmentation makes the problem particularly important on Android. Google describes Android applications as operating across a broad range of configurations and notes that hardware features can vary between devices. Compatibility can depend on platform version, screen configuration, and the availability of device features.
The objective of an outsourcing contract should therefore be representative risk coverage, not an unrealistic promise to test every possible device configuration. For teams that need structured guidance on test data and environment setup, test data management principles apply directly to mobile engagements.
ISO/IEC/IEEE 29119 also describes risk-based testing as the underlying approach for test prioritization and focus, reinforcing the principle that testing should be allocated according to risk rather than distributed uniformly.
The Seven-Step Process
1. Define the Product and Release Risk
The client identifies:
- Supported platforms
- Minimum OS versions
- Core business workflows
- Geographic markets
- Revenue-critical flows
- Hardware-dependent functionality
- Release frequency
- Known production risks
- Regulatory or accessibility requirements
A banking application’s device strategy, for example, will differ from that of a content-streaming application because biometric authentication, camera capture, security, and transaction integrity create different risks.
2. Analyze the Real User Population
The QA provider examines available product analytics and store data.
Google Analytics can report attributes including device model, device brand, operating system, OS version, platform, and screen resolution.
For Apple applications, App Store Connect Analytics supports analysis by device and platform version, among other dimensions.
For Android, the Google Play device catalog adds hardware-oriented information including manufacturer, model, RAM, form factor, system-on-chip, GPU, screen size, screen density, ABIs, and Android SDK versions.
3. Build a Risk-Weighted Device Matrix
Devices are selected to represent the most important combinations of audience share, OS risk, manufacturer behavior, display configuration, hardware constraints, and business importance.
The objective is not simply to select the ten most popular phones. A low-volume device may still belong in the matrix if it represents:
- The application’s minimum supported RAM
- A foldable layout
- A unique manufacturer customization
- A small-screen layout boundary
- A hardware feature used by a critical workflow
- A device family associated with disproportionate crash volume
4. Design the Test Suite
The supplier maps product requirements and risks to test scenarios, test cases, exploratory charters, device combinations, and expected results.
5. Execute Across the Agreed Matrix
Testing can combine:
- Physical in-house devices
- Cloud-hosted real devices
- Android virtual devices
- Automated tests
- Manual exploratory testing
Firebase Test Lab, for example, supports test matrices in which device model, OS version, orientation, and locale can be selected, and it supports real devices for both Android and iOS.
6. Report, Triage, and Retest Defects
Defects should be reported with enough evidence for developers to reproduce them without another discovery cycle.
7. Issue a Test Completion and Risk Report
The final report should state what was tested, what was not tested, results by platform and device, unresolved defects, deviations from plan, residual risks, and whether agreed exit criteria were achieved.
ISO/IEC/IEEE 29119-3 specifies test documentation templates applicable across software testing projects, while ISTQB describes test summary reporting as covering testing performed, deviations, status against completion criteria, metrics, blockers, and residual risks.
How Should Devices Be Selected for Outsourced Mobile App Testing?
Start With Audience Analytics, Not a Generic Top Devices List
The strongest starting point for Outsourced mobile app testing is the application’s own active-user population.
Extract at least:
| S. No |
Dimension |
What it tells the QA team |
| 1 |
Platform |
Android versus iOS distribution |
| 2 |
Device model |
Models actually used by customers |
| 3 |
Manufacturer |
Android OEM concentration |
| 4 |
OS version |
Versions generating real usage |
| 5 |
Screen resolution |
Display patterns requiring layout coverage |
| 6 |
Country or region |
Regional device differences |
| 7 |
App version |
Whether issues correlate with particular releases |
| 8 |
Crashes or failures |
Configurations producing disproportionate instability |
GA4 exposes several of these device dimensions directly, while App Store Connect provides device and platform-version filters for Apple applications.
A public global market-share chart can supplement this analysis for a new application with little production data, but it should not override first-party analytics once meaningful usage data exists.
How Should OS Versions Be Selected?
A useful matrix for Outsourced mobile app testing normally represents four OS categories:
- Latest supported OS
- Dominant production OS
- Previous OS generation
- Oldest materially used supported OS
Do not assume those four categories always require four separate versions. Analytics may show that some overlap.
As of June 7, 2026, Apple reported that 79% of all iPhones transacting on the App Store were using iOS 26, increasing to 86% for devices introduced during the previous four years.
That concentration may justify heavy iOS 26 coverage for many products, but older supported versions should remain in the matrix when meaningful portions of the application’s own audience still use them.
Apple’s iOS 26 compatibility range also extends across several generations, including iPhone 11-series devices and iPhone SE models from the second generation onward.
On Android, the current stable platform is Android 16 at API level 36. Google recommends compatibility testing when new Android releases introduce behavior changes and notes that Google Play requires apps to target API level 36 from August 2026.
An outsourced QA provider should therefore distinguish between:
- Minimum supported OS testing
- Latest OS compatibility testing
- Target-SDK behavior testing
- OS versions dominant among existing customers
These are related but not interchangeable coverage requirements.
Why Do Android Manufacturers Matter?
Two Android phones running the same OS version should not automatically be treated as equivalent test targets.
Manufacturer selection can expose differences involving:
- Camera implementations
- Biometric behavior
- Background-process management
- Permission UX
- Power management
- GPU behavior
- System UI
- Display shape
- Foldable implementation
- Hardware sensors
- Memory and storage constraints
Use audience analytics to identify the manufacturers actually represented in the installed base.
For example, a product with 65% Samsung usage should normally give Samsung more coverage weight than an OEM representing 2% of its customers.
Conversely, a smaller manufacturer segment may still deserve a device if support data indicates a model-specific failure.
Google’s own 2026 Android reference-device list spans manufacturers such as Google, Samsung, Motorola, Lenovo, OnePlus, Oppo, Vivo, and Xiaomi, illustrating the continuing breadth of modern Android hardware configurations.
How Should Screen Sizes Be Covered?
Testing every nominal screen resolution is inefficient.
Instead, cover layout boundaries and materially different app-window configurations.
For Android, Google’s adaptive-app guidance recommends designing and testing according to available window space rather than assuming a physical device always provides one fixed app size. Android window-size classes include compact, medium, expanded, large, and extra-large widths.
Useful coverage therefore includes:
- Small or narrow phone
- Standard phone
- Large phone
- Tablet portrait
- Tablet landscape
- Foldable folded state
- Foldable unfolded state
- Split-screen or resizable-window states where supported
This becomes increasingly important because Android 16 changes large-screen behavior for applications targeting API level 36, including orientation, aspect-ratio, and resizability behavior on displays with a smallest width of at least 600dp.
Testing only one portrait phone and one tablet can therefore miss transitions that occur when the same application window changes size.
Which Hardware Constraints Should Be Represented?
Select hardware based on what the application actually exercises.
Relevant constraints can include:
- Low versus high RAM
- Older versus recent CPU or SoC
- Available storage
- GPU capability
- Camera configuration
- Front and rear camera availability
- Bluetooth and Bluetooth Low Energy
- NFC
- GPS
- Accelerometer or other sensors
- Face or fingerprint biometrics
- Cellular capabilities
- Physical keyboard or external input
- Foldable hinge and display state
Google Play’s device catalog exposes RAM, SoC, GPU, ABI, display, SDK, and related configuration information, making it useful for identifying representative Android hardware classes.
RAM is especially relevant for memory-intensive applications. Android’s current performance guidance distinguishes device memory tiers, including configurations in the 0 to 4 GB range, because available memory can materially affect application behavior.
Applications using camera or Bluetooth functionality also need deliberate capability coverage. Android’s manifest feature system explicitly distinguishes hardware capabilities such as cameras and Bluetooth because those features are not uniformly available across every device.
Sample Mobile App Testing Device Matrix
The following matrix is illustrative rather than a universal device list. Actual models should be replaced or reprioritized using the application’s audience data.
| S. No |
Priority |
Example device or profile |
OS target |
Display profile |
Hardware or risk represented |
Primary purpose |
| 1 |
P0 |
iPhone 17 |
Current iOS 26.x |
Standard modern phone |
Current Apple hardware |
Primary iOS regression |
| 2 |
P0 |
iPhone 13 |
iOS 26.x or audience-dominant supported version |
Standard phone |
Older but widely supported generation |
Backward hardware coverage |
| 3 |
P1 |
iPhone 13 mini |
Supported iOS |
Small phone |
Narrow display |
Small-screen UI |
| 4 |
P1 |
iPhone SE, 3rd generation |
Supported iOS |
Compact and Home-button profile |
Older form factor |
Layout and interaction edge cases |
| 5 |
P0 |
Samsung Galaxy S26 or S26-class device |
Android 16 |
Standard or large phone |
Samsung flagship implementation |
Primary Android regression |
| 6 |
P0 |
Google Pixel 10-class |
Android 16 |
Standard or large phone |
Reference Android implementation |
Latest Android behavior |
The matrix should also identify whether each row is tested on:
- Real hardware
- Virtual device
- Automated suite
- Manual regression
- Smoke suite only
- Hardware-specific exploratory testing
Google recommends using physical devices before significant Android releases when functionality depends on device features that virtual devices cannot fully simulate.
Rules for Expanding the Device Matrix
A matrix should evolve with production evidence. The following framework for Outsourced mobile app testing uses example governance rules, not external standards.
Add a Device When Its Audience Share Crosses the Agreed Threshold
Example policy:
- Add any device model reaching 2% of monthly active mobile users, unless another matrix device provides materially equivalent risk coverage.
- Teams with very large user populations may use a lower threshold.
Expand Until the Matrix Reaches a Target Cumulative Audience
- Core matrix: representative devices covering approximately 70% of active users
- Extended matrix: expand toward approximately 90%
- Long tail: virtual, automated, or periodic compatibility testing
These percentages should be set according to product risk rather than treated as universal benchmarks.
Add Configurations With Disproportionate Failures
Add a model, manufacturer, or OS version when it contributes materially more crashes, payment failures, authentication problems, support tickets, or other defects than its user share would predict.
A configuration representing 1% of users but 8% of crash reports may deserve higher priority than a device representing 4% of users with no abnormal behavior.
Add the Newest OS Before Adoption Becomes Dominant
Do not wait until an OS release becomes the majority version.
- Run compatibility testing during preview and beta periods when business risk justifies it.
- Add the stable release to the primary matrix as adoption increases.
Google explicitly recommends proactive testing against Android platform behavior changes during developer preview and beta periods.
Add a Device When a New Layout Category Appears
Expand coverage when the product begins supporting:
- Tablets
- Foldables
- Desktop-window modes
- Split screen
- Landscape-only workflows
- External displays
Add Hardware When a Release Begins Depending on It
A release introducing NFC payments, document scanning, Bluetooth accessories, biometric login, GPS tracking, or intensive media processing should trigger corresponding hardware coverage.
Add Regional Manufacturers When the Market Changes
A device matrix built for North America may be inappropriate after expansion into another geography.
Recompute manufacturer and model distributions by region rather than assuming one global matrix represents all customers.
Review the Matrix on a Defined Cadence
- Monthly analytics review for fast-moving consumer products
- Quarterly matrix refresh for more stable enterprise applications
- Immediate review after a major OS release, hardware-dependent feature launch, or significant device-specific incident
The cadence should be written into the testing agreement.
What Should Be Included in the Outsourced Mobile Testing Scope?
A detailed statement of work should define at least the following areas.
Functional Coverage
Identify the critical workflows that must work on every P0 device, such as:
- Registration
- Login
- Search
- Checkout
- Payment
- Messaging
- Data synchronization
- Notifications
- Account management
Less critical features may receive reduced device coverage.
Compatibility Coverage
Specify:
- Supported OS versions
- Device models
- Manufacturers
- Phone, tablet, and foldable scope
- Orientations
- Window states
- Hardware capabilities
Network Coverage
Define applicable conditions such as:
- Wi-Fi
- Cellular
- High latency
- Intermittent connectivity
- Offline and reconnect transitions
- Network switching
Lifecycle and Interruption Coverage
- Fresh install
- Upgrade
- Logout and login
- Background and foreground
- Application termination
- Device rotation
- Incoming calls or OS interruptions where applicable
- Permission changes
- App restoration
Regression Coverage
State whether every release receives:
- Smoke testing
- Full regression
- Risk-based regression
- Automated regression
- Exploratory testing
Non-Functional Coverage
Clarify whether the vendor is responsible for:
- Startup performance
- Runtime responsiveness
- Memory behavior
- Battery behavior
- Accessibility
- Security testing
- Localization
- Data privacy validation
Avoid writing “performance testing included” without defining which performance characteristics are measured.
What Deliverables Should an Outsourced Mobile Testing Vendor Provide?
A strong contract defines tangible test work products.
| S. No |
Deliverable |
Expected content |
| 1 |
Test strategy |
Scope, risks, methods, levels, responsibilities |
| 2 |
Device matrix |
Models, OS versions, displays, hardware rationale, priority |
| 3 |
Test plan |
Schedule, environments, builds, entry and exit criteria |
| 4 |
Test scenarios and cases |
Preconditions, actions, expected results |
| 5 |
Requirements traceability |
Mapping of requirements or risks to coverage |
| 6 |
Execution report |
Passed, failed, blocked, and not-run tests |
| 7 |
Defect reports |
Reproduction steps, build, device, OS, evidence, severity |
| 8 |
Screenshots, video, and logs |
Evidence sufficient for diagnosis |
| 9 |
Daily or status report |
Progress, blockers, defects, upcoming work |
| 10 |
Retest results |
Verification of fixes and affected regression areas |
| 11 |
Final test summary |
Coverage, open defects, deviations, residual risk |
| 12 |
Automation assets |
Source code and scripts when ownership is included |
| 13 |
Device-coverage history |
Which configurations were tested for each release |
ISO/IEC/IEEE 29119-3 specifically addresses test documentation outputs, making documented deliverables useful not only operationally but also for governance and auditability.
How Long Does Outsourced Mobile App Testing Take?
There is no universal testing timeline because duration depends on application complexity, matrix size, build stability, automation level, integration dependencies, and defect volume.
A representative release cycle for an established application could look like this:
| S. No |
Phase |
Illustrative duration |
| 1 |
Scope confirmation and build validation |
0.5 to 1 business day |
| 2 |
Device-matrix confirmation |
0.5 to 1 day |
| 3 |
Test-data and environment preparation |
1 to 2 days |
| 4 |
Smoke testing |
0.5 to 1 day |
| 5 |
Functional and regression execution |
2 to 5 days |
| 6 |
Compatibility and exploratory testing |
1 to 3 days |
| 7 |
Defect verification and retesting |
1 to 2 days |
| 8 |
Final reporting |
0.5 day |
A stable application with a mature automated regression suite may complete considerably faster. A new application with incomplete requirements, unstable environments, payment integrations, Bluetooth hardware, localization, or more than 30 device configurations may require substantially longer.
The timeline should therefore be calculated from test executions and dependencies, not from an arbitrary promise such as “complete mobile testing in three days.”
Practical Example: Outsourcing Testing for an E-commerce Mobile App
Consider an e-commerce company preparing a major Android and iOS checkout release.
Preconditions
The application has:
- 500,000 monthly active users
- iOS and Android clients
- Card and wallet payments
- Push notifications
- Product-image uploads
- Approximately 60 automated regression tests
Analytics Findings
The QA team discovers:
- iOS traffic is concentrated on several recent iPhone generations.
- Android traffic is dominated by Samsung, followed by two other manufacturers.
- One mid-range Android family produces an above-average share of checkout crashes.
- Approximately 6% of Android users run devices in the lowest memory tier supported by the application.
- Tablet usage is low but commercially important because average order value is higher.
Device Strategy
The outsourced partner assigns:
- Six devices to the P0 core matrix
- Four additional devices to P1 compatibility
- One tablet
- One low-RAM Android profile
- One foldable for layout validation
Execution
Every release candidate receives automated smoke testing across the core device matrix.
Manual testers then validate:
- Login
- Search
- Product detail
- Cart
- Coupon application
- Checkout
- Wallet or card payment
- Order confirmation
- Push notification
- Image upload
The checkout flow receives broader coverage because it directly influences revenue.
Expected Output
The supplier delivers:
- Device-by-device execution results
- Payment-flow results
- Defects with video and logs
- Retest evidence
- Open-risk summary
- Release recommendation against agreed exit criteria
Example Error Condition
Testing finds that checkout succeeds on current flagship Android devices but the payment screen is terminated under memory pressure on a low-RAM model.
Without hardware-tier coverage, the defect could have escaped despite passing on the highest-volume flagship devices.
Teams that need to validate these flows with automation should review mobile app automation testing approaches that support structured regression execution.
SLA vs Timeline vs Exit Criteria: What Is the Difference?
| S. No |
Factor |
Timeline |
SLA |
Exit criteria |
| 1 |
Main question |
When will testing be performed? |
How quickly must the service respond? |
When is testing sufficiently complete? |
| 2 |
Example |
Regression finishes within five business days |
P0 defect acknowledged within 30 minutes |
No unresolved release-blocking defects |
| 3 |
Focus |
Schedule |
Service performance |
Quality gate |
| 4 |
Used for |
Planning |
Vendor accountability |
Release decision |
| 5 |
Should depend on |
Scope and capacity |
Severity and support window |
Product risk |
Confusing these terms creates weak contracts.
A vendor can meet an SLA by responding to a critical defect within 30 minutes while the application still fails its release exit criteria.
Sample Mobile Testing SLA
The following SLA is an illustrative contracting model. Required response times should be adjusted for team locations, support hours, release criticality, and commercial risk.
| S. No |
Severity |
Example |
Acknowledge |
Detailed defect report |
Retest after fixed build |
| 1 |
P0 or Blocker |
App cannot launch, data loss, checkout unavailable |
30 minutes |
2 hours |
4 business hours |
| 2 |
P1 or Critical |
Critical workflow fails with no acceptable workaround |
1 hour |
4 hours |
Same business day |
| 3 |
P2 or Major |
Important function fails but workaround exists |
4 business hours |
1 business day |
1 business day |
The contract should additionally specify:
- Coverage hours and time zone
- Holiday and weekend handling
- Escalation contacts
- Build acceptance time
- Test-environment incident handling
- Status-report cadence
- Test-completion reporting
- SLA exclusions when required environments or credentials are unavailable
Do not make the vendor financially accountable for turnaround times that depend on a client-owned environment without defining how blocked time is measured.
Best Practices for Outsourcing Mobile App Testing
Make the Device Matrix Evidence-Based
Require the supplier to show why each device is present.
“Popular Android phone” is weaker than “Samsung model family representing 18% of Android MAU and the dominant 4 to 8 GB memory tier.”
Separate Core and Extended Coverage
Running every test on every device quickly becomes expensive. Instead:
- Execute business-critical tests on the P0 matrix.
- Run broader compatibility checks on P1 configurations.
- Use automation or periodic sampling for the long tail.
Combine Real and Virtual Devices
Virtual devices provide scalable, fast feedback, especially in CI.
Use real devices for scenarios involving hardware behavior, performance characteristics, manufacturer differences, cameras, Bluetooth, biometrics, sensors, and release-critical workflows.
Firebase similarly recommends physical-device testing before significant releases when functionality depends on device features that virtual environments cannot fully reproduce.
Recalculate the Matrix Instead of Letting It Become Permanent
A device selected eighteen months ago may no longer represent meaningful traffic.
Review actual usage and defect data regularly.
Require Reproducible Defect Evidence
Every defect should normally capture:
- Application build
- Device
- OS version
- Preconditions
- Steps
- Expected result
- Actual result
- Severity
- Screenshot or video
- Relevant logs
Define Ownership of Automation
If an outsourced team creates test automation, specify ownership of:
- Test code
- Framework code
- CI configuration
- Test data
- Credentials
- Documentation
- Maintenance responsibility
Make Residual Risk Visible
A “100% passed” dashboard can be misleading when several devices were unavailable or tests were removed from scope.
Final reports should explicitly list untested configurations and outstanding risks.
Common Outsourcing Mistakes
| S. No |
Mistake |
Why it happens |
Impact |
Recommended fix |
| 1 |
Buying a fixed number of devices without analytics |
Easy to quote |
Poor real-user coverage |
Prioritize by usage and risk |
| 2 |
Testing only latest OS versions |
Simplifies the matrix |
Older-user regressions escape |
Include materially used supported versions |
| 3 |
Treating all devices from a manufacturer as equivalent |
Convenient grouping |
Hardware-specific defects missed |
Include hardware capability tiers |
| 4 |
Confusing SLA with exit criteria |
Similar-sounding terms |
Release decisions lack rigor |
Define both separately in the contract |
| 5 |
Omitting constrained hardware |
Flagships are easier to source |
Low-RAM defects reach production |
Add memory-tier coverage |
| 6 |
Letting the matrix stay static |
Setup effort is already spent |
Coverage drifts from reality |
Review on a defined cadence |
Troubleshooting Outsourced Testing
Why can the supplier not reproduce a defect?
Insufficient environmental information is the most common cause.
Require defect reports to include:
- Device model
- OS version
- App build
- Account and test data
- Network condition
- Permission state
- Locale
- Orientation and window state
If reproduction still fails, request video, application logs, device logs, and network evidence where appropriate.
Why is the device matrix becoming too large?
The team may be treating every model as an independent risk.
Group devices by meaningful equivalence classes such as:
- Manufacturer
- OS
- Window class
- RAM tier
- SoC generation
- Hardware capability
Then retain exact-model coverage only where analytics or defect history justifies it.
Why does the app work on emulators but fail on physical phones?
The failing behavior may depend on real hardware, manufacturer software, sensors, memory pressure, camera behavior, Bluetooth, or another device-specific implementation.
Reproduce the scenario on a physical device in the affected configuration.
Why do new Android versions repeatedly cause regression issues?
The application may not be testing Android behavior changes early enough.
Google recommends proactive compatibility testing around new Android releases, including behavior changes that can affect applications independently of or because of their target SDK.
Add preview and beta compatibility testing to the release process when the application’s risk profile warrants it.
Why is the outsourced QA cycle missing deadlines?
Check whether the delay originates from testing capacity or blocked dependencies.
Common external dependencies include:
- Late builds
- Unavailable test environments
- Missing credentials
- Unstable APIs
- Payment sandbox failures
- Test-data resets
- Delayed defect fixes
Measure blocked time separately from active vendor execution time.
What Tools Can Support Outsourced Mobile App Testing?
A mature outsourced setup can combine several categories of tooling.
First-Party Analytics
GA4, Firebase, and App Store Connect provide actual device, OS, and audience information that should drive device selection.
Android Device Intelligence
The Google Play device catalog provides model, manufacturer, RAM, SoC, GPU, density, ABI, and Android version characteristics.
Physical and Virtual Device Infrastructure
Local labs and cloud device farms complement each other. Firebase Test Lab is one current example supporting Android and iOS real-device testing as well as Android virtual-device workflows.
CI/CD Automation
Automated smoke and regression tests should execute on release candidates or pull-request pipelines. Teams building this layer often benefit from QA automation services that integrate directly with delivery pipelines.
The correct implementation is usually hybrid rather than dependent on one tool.
Limitations and Risks of Outsourced Mobile App Testing
Outsourcing does not eliminate product risk. Important limitations include the following.
The Device Matrix Remains a Sample
No practical matrix can reproduce every combination of model, OS, hardware state, network condition, locale, accessibility setting, and user behavior.
Analytics May Be Incomplete
App Store Connect notes privacy and data-availability constraints, and GA4 allows granular device data collection to be disabled by region.
Device decisions should therefore incorporate analytics, support incidents, store data, and engineering knowledge rather than relying on one dataset.
Test Labs Cannot Reproduce Every Real-World Condition
Cloud environments are valuable but do not exactly replicate every carrier, battery state, environmental condition, connected accessory, or field scenario.
Poor Builds Waste Outsourced Capacity
External QA cannot compensate for repeatedly untestable release candidates.
A build-acceptance smoke test should therefore precede full execution.
Outsourcing Does Not Transfer the Release Decision
The testing partner can provide evidence and risk assessments. Product and engineering stakeholders still need to decide whether the remaining risk is acceptable.
Need Help Building Your Mobile Testing Outsourcing Model?
If your team is evaluating Outsourced mobile app testing and needs help defining scope, building a data-driven device matrix, or setting realistic SLAs and exit criteria, Codoid can help. Our QA specialists build analytics-driven mobile test coverage across iOS and Android, including low-RAM devices, foldables, tablets, and hardware-dependent workflows.Talk to a Mobile Testing Expert
Conclusion
Successful Outsourced mobile app testing depends less on the number of testers or devices purchased and more on the precision of the operating model. Define the scope, deliverables, device-selection logic, timeline, SLA, and exit criteria before execution begins. Build the device matrix from actual audience analytics, then deliberately add OS boundaries, manufacturer diversity, screen and window-size classes, constrained hardware, and high-risk capabilities that raw popularity data may miss.
Finally, treat the matrix as a living risk model. Update it when customer behavior, OS adoption, manufacturers, hardware, application functionality, or production defect patterns change. That approach turns Outsourced mobile app testing from a generic execution service into a measurable quality-control process tied to the devices and risks that matter to real users.
by Rajesh K | Sep 24, 2026 | Software Testing, Blog, Latest Post |
A QA automation company can name every automation tool on your shortlist and still leave the most important questions unanswered. Whether you’re evaluating an outside vendor or scaling automation through our own automation testing services, the real test isn’t which tools a provider knows, it’s whether they can deliver automation your own team can trust, adapt, and maintain. What happens when your application changes? Who investigates an inconsistent test failure? Does a failed check actually stop a release? Can your engineers maintain the suite without calling the vendor?
What should you look for in a QA automation company?
Tool expertise matters, but it should be an entry requirement, not the deciding factor. The more useful standard is whether a provider can deliver fast, dependable feedback throughout your development process. DORA’s guidance on test automation emphasizes reliable suites, continuous improvement, and integration into delivery pipelines rather than the mere presence of automated tests.
Evaluate the automation capability you will own, not just the tools the provider can operate. That means looking closely at six areas: framework design, maintainability, flaky-test management, pipeline integration, reporting, and handover. Our automation testing services team is evaluated against this exact framework by our own clients.
Key takeaways
- Tool proficiency should be a shortlist filter, not the deciding factor.
- Ask for a product-specific architecture rationale, not generic words like “modular” or “scalable.”
- Test maintainability should be demonstrated with a real, recent code change, not asserted.
- A credible flaky-test process investigates root cause; it does not just rerun failures automatically.
- Pipeline integration should be proven by deliberately breaking a release gate, not just showing a green dashboard.
- Handover should be tested as a rehearsal where your own engineer operates the suite independently.
1. Framework design: Ask how the architecture fits your product
“Modular,” “scalable,” and “reusable” are not sufficient answers to an architecture question. Ask the provider to explain what those words mean in its proposed implementation.
Start with your product’s risks. Which customer journeys must remain available? Which business rules change frequently? Where do services exchange data? What coverage already exists, and which failures have historically escaped testing?
The proposed design should connect those risks to appropriate test levels. Unit tests can check isolated logic; integration and contract tests can examine interactions and service expectations; end-to-end tests can validate complete journeys. The practical test-pyramid approach favors focused checks where they provide adequate confidence, reserving broader tests for risks that narrower checks cannot adequately cover.
For an online ordering system, for example, ask why every discount combination needs to run through a browser. A reasonable proposal might place most pricing-rule checks below the interface while retaining end-to-end coverage for completing an order. The provider should explain the trade-off, not simply apply a predetermined percentage of each test type.
Then inspect the framework itself. Request an annotated repository showing how it separates business scenarios, interface interactions, service clients, test-data setup, environment configuration, and reporting.
For browser automation, page objects or reusable components can centralize interface-specific details. Selenium’s documentation describes this separation as a way to reduce duplication and localize changes when the interface changes. However, naming the pattern does not demonstrate that the provider has implemented it well.
Ask the engineers to walk through a representative test. Can a reviewer understand the behavior being checked without navigating through several layers of generic wrappers? Is an abstraction solving a recurring problem, or merely making a small suite look sophisticated?
Also ask what the provider recommends not automating yet. Require explicit boundaries around exploratory work, usability evaluation, and any specialist testing outside the engagement.
Evidence to request: A product-specific architecture rationale, a sample repository, and a live walkthrough by the engineers who would deliver the work.
Warning sign: The same proprietary framework is proposed before the provider understands your application, risks, existing coverage, or internal skills.
2. Test maintainability: Evaluate the cost of the next change
A successful first run tells you little about the effort required to keep a suite useful.
Make maintainability observable. Ask for a recent, anonymized example of an application change and the corresponding test-code changes. Examine how many files changed, why they changed, and whether the business intent of the tests remained clear.
For interface tests, inspect how elements are located. Playwright’s guidance recommends user-facing attributes and explicit contracts rather than unnecessary dependence on page structure. It also emphasizes test isolation so that one test does not rely on the state left behind by another. These are useful evaluation principles regardless of the specific tool selected.
Synchronization deserves its own discussion. Ask how the framework waits for an asynchronous operation to complete. Selenium documents the weakness of fixed sleeps: a delay can be too short to prevent failure or unnecessarily long for normal execution. Look for waits tied to meaningful conditions, with clear time limits and useful failure messages.
Test data is equally important. Ask the provider to demonstrate how tests create their prerequisites, avoid collisions during parallel execution, and clean up after failures. DORA recommends controlled inputs and data associated with individual tests, noting that isolation is a prerequisite for parallel testing. Its guidance also warns against the risks of copying sensitive production data into testing environments.
Beyond implementation details, request the maintenance process: code-review rules, named owners, dependency-upgrade responsibilities, and a budget for improving existing tests. Require routine changes to arrive through the same reviewable development workflow as other code.
A particularly useful exercise is to make two changes in a test environment. First, alter an interface layout without changing its behavior. Then change a genuine business rule. Ask the provider to explain the different responses.
The goal is not a suite that never needs updating. Tests should tolerate irrelevant implementation changes without becoming blind to meaningful behavior changes.
Evidence to request: A live change exercise, the resulting code diff, and an explanation of the review and maintenance effort.
Warning sign: Small interface changes require widespread edits, or the provider “repairs” tests by weakening assertions until they pass.
3. Flaky-test management: Look for diagnosis, not unlimited retries
A flaky result is an inconsistent pass or failure against the same code. The underlying cause may involve test code, concurrency, external dependencies, infrastructure, or the application itself. Google’s account of flaky-test management explicitly warns that an apparent testing problem can conceal a real product defect.
That makes “we automatically rerun failures” an incomplete answer.
Ask the provider to describe what happens from the first inconsistent result through investigation and repair. Require it to preserve the original failure evidence and record the tested application version, test version, configuration, and relevant environment details.
The investigation should distinguish a test implementation defect from an application defect, a data problem, or an infrastructure failure. An unresolved failure should remain unresolved, not quietly become an “environment issue” because it disappeared on the next run.
Retries can provide useful evidence, but their outcomes must remain visible. Playwright, for example, distinguishes tests that pass initially from those that fail initially but pass on retry. That runner-level classification records observed behavior; it does not identify the underlying cause.
Ask how the provider manages quarantine: temporarily removing an unstable check from release-blocking execution. Google describes quarantine as a mitigation while warning that it can mask genuine bugs. Treat it as a controlled exception, not a permanent destination for difficult tests.
For your engagement, require each quarantined test to have an owner, an investigation ticket, a review deadline, and an explicit statement of the risk no longer covered by a blocking check. Ask whether it continues to run separately and what evidence is required before it returns to the main suite.
Evaluate fixes under relevant conditions. A test that now passes alone should also be checked in the execution conditions that exposed the problem, including realistic parallelism where applicable.
Evidence to request: An anonymized incident showing the original failure, investigation, root cause, corrective change, and subsequent verification.
Warning sign: Reliability is reported only after retries, quarantine has no expiry or ownership, or every intermittent failure is assumed to be harmless.
4. Pipeline integration: Verify the failure path, not just the launch command
“Works with your CI/CD platform” should be the beginning of the discussion.
Ask the provider to show how automation fits into your continuous integration and delivery process. Which checks run before a change is merged? Which run against a deployed release candidate? Which run on a schedule? What does each stage permit or prevent?
Require a rationale tied to feedback speed and business risk. A proposed arrangement might run focused checks and a small set of critical journeys on pull requests, with broader environment or compatibility coverage at later stages. Do not accept a rule that all expensive tests belong overnight without examining when their results are needed.
Measure the complete feedback time, not merely the test runner’s duration. Include queueing, environment preparation, test-data creation, retries, and report publication. Ask the provider to demonstrate performance on infrastructure comparable to yours.
Parallel execution also needs evidence. Playwright’s CI documentation cautions that worker settings should reflect available resources and suggests distributing work across jobs where appropriate. More simultaneous workers are not automatically a better configuration.
Most importantly, deliberately test the release gate. Introduce a known regression in a non-production branch and verify that the correct failure blocks the intended action. Then examine what happens when a prerequisite fails, no tests are discovered, or part of the distributed run never finishes.
This is not a theoretical concern. GitHub documents that conditionally skipped jobs can report success and that jobs skipped because of failed dependencies may not block merging. A reassuring status indicator therefore needs to be checked against the workflow’s actual behavior.
Require configuration in version control, an explicit policy for missing or incomplete results, and a named owner for pipeline failures. Also ask how credentials are supplied and how the provider will work within your access controls.
Evidence to request: A working pipeline in your environment, including demonstrations of genuine test failure, failed prerequisites, and incomplete execution.
Warning sign: Tests run successfully, but failures do not reliably reach developers, affect merge decisions, or produce accessible diagnostic evidence.
5. Reporting: Demand answers about risk, not just pass percentages
A dashboard should help someone decide what to investigate, what to fix, and whether a release has sufficient evidence behind it.
Ask the provider to separate reporting into three views.
Failure diagnosis
For a failed check, require the expected and observed behavior, the affected scenario, the application build and test-code version, the execution configuration, and supporting evidence.
Depending on the test, that evidence might include a trace, screenshot, console output, service logs, or request and response details. Playwright’s trace viewer illustrates the diagnostic depth available: it exposes action history, page snapshots, errors, console messages, and network activity.
Ask an engineer unfamiliar with the failure to use the report. Can they identify a plausible next investigation step without contacting the test author?
Also ask how evidence is protected. Because traces can contain request headers and bodies, require the provider to demonstrate appropriate handling of sensitive values, access permissions, and retention.
Release confidence
Require results to map back to agreed critical journeys and risks. The report should make untested, skipped, blocked, and quarantined scenarios visible, not merge them into a general statement that “automation passed.”
Ask for first-attempt outcomes and retry outcomes separately. Agree on the counting rules: one scenario executed on three browser configurations represents one scenario but three configured executions. Mixing those units makes comparisons misleading.
A release summary should state what was checked, against which build, where failures remain, and what important uncertainty is still unresolved.
Long-term effectiveness
Request trends in feedback time, investigation effort, maintenance effort, and recurring instability. Review whether failures are identifying product defects or consuming time because of problems in the tests. DORA includes time spent fixing acceptance-test failures and the meaningfulness of automated failures among its suggested measures.
Treat these as diagnostic measures rather than isolated targets. For example, a falling failure count is not automatically an improvement if important tests were disabled.
Finally, require access to usable underlying results. Machine-readable formats such as JSON and JUnit-style XML are available in established runners; ask the provider to demonstrate how its reporting approach supports your systems and preserves the distinctions you need.
Evidence to request: A real report covering a failed run, retry outcomes, incomplete coverage, and the resulting engineering or release decision.
Warning sign: Reporting emphasizes test counts and eventual pass rates while obscuring missing coverage, original failures, or time spent investigating noise.
6. Handover: Make independent operation an acceptance criterion
Do not leave handover until the final week.
Set the expectation that your engineers will participate in reviews and maintenance throughout the engagement. DORA warns about problems when test automation is owned by a separate group without sufficient developer involvement, and recommends collaboration between testers and developers to create and evolve the suites.
Translate that principle into a concrete acceptance exercise. Ask an internal engineer to start from a clean environment, obtain the repository, install the documented dependencies, prepare test data, run a selected suite, diagnose a failure, add a scenario, and submit the change through your pipeline.
The provider may observe, but the exercise should reveal every undocumented dependency on its engineers, accounts, or infrastructure.
Specify the handover package early. Require the test source, shared libraries, dependency manifests, setup instructions, data-generation assets, pipeline configuration, and reporting configuration. Include architecture decisions and operating instructions, not just commands, but explanations of why important choices were made.
Also require a current record of known limitations: coverage gaps, unresolved failures, quarantined tests, and planned maintenance. Ask for named primary and backup owners and an agreed support period for the transition.
Commercial dependencies need equal attention. Clarify which components are custom deliverables and which are pre-existing vendor assets. For proprietary components, establish what your team can continue to execute, inspect, modify, or replace after the engagement ends.
Ask where repositories, execution accounts, and historical reports will reside. Identify ongoing licenses, hosted services, export limitations, and offboarding charges before making the selection.
A document handover is not the same as a capability transfer. Acceptance should depend on your team demonstrating independent operation, not merely attending a presentation.
Evidence to request: A handover rehearsal, reviewed documentation, an asset-and-access inventory, and a clear statement of continuing dependencies.
Warning sign: Only the vendor can run the full suite, interpret its framework, administer its accounts, or make routine changes.
Compare providers through a representative pilot
Bring the six criteria together in a bounded pilot rather than relying on separate sales demonstrations.
Give shortlisted providers the same representative scope, constraints, and access. Ask the proposed delivery engineers, not only a specialist presales team, to perform the work.
Choose a scope that exposes the important engineering decisions: a critical user journey, a meaningful negative case, an interface with another service, and a component used by more than one test.
After the initial implementation, introduce a controlled application change and a known regression in the test environment. Examine the repair, verify that the regression is detected, inspect the pipeline response, and have an internal engineer use the documentation to extend the suite.
Repeat execution across representative conditions and record the observation period. A pilot with no observed flaky results is useful evidence, but a finite sample cannot establish that the suite will never behave inconsistently.
Use the following as a suggested evaluation scorecard, not an industry certification:
| S. No |
Evaluation area |
Evidence that should influence the decision |
| 1 |
Framework design |
The architecture fits the identified risks, and the delivery team can explain its boundaries and trade-offs. |
| 2 |
Maintainability |
A realistic change produces understandable, appropriately scoped edits without weakening the checks. |
| 3 |
Flaky-test management |
Original failures remain visible, investigations identify causes, and quarantine is controlled. |
| 4 |
Pipeline integration |
Genuine regressions block the right actions, while missing or incomplete execution is handled explicitly. |
| 5 |
Reporting |
Engineers can investigate failures, and release owners can see coverage gaps and unresolved risk. |
| 6 |
Handover |
Your team can operate and extend the implementation using the supplied assets and instructions. |
Score evidence more highly than promises. A practical scale is: asserted, explained, demonstrated, and independently reproduced. Adjust the importance of each area to your product rather than treating every criterion as equally consequential.
Compare commercial proposals on the same basis. Ask each provider to separate implementation, recurring infrastructure and licenses, maintenance, failure investigation, onboarding, and exit costs. A lower initial price should not settle the decision when the ongoing work and dependencies remain undefined.
If your evaluation is specifically for mobile releases, see our related guide on how to choose a mobile app testing company for platform-specific questions to add to this framework.
Hire for the lifecycle of the automation
The decisive question is not, “How many tools does this QA automation company support?” It is, “What evidence shows that this team can build automation we can trust, adapt, and own?” Keep tool proficiency on the shortlist criteria. Make the final decision on architecture, maintenance behavior, failure handling, delivery integration, useful reporting, and demonstrated handover.
Before signing, ask the provider to prove three things: that its tests detect an important regression, that its engineers can maintain them through a realistic change, and that your team can take over afterward. Those demonstrations will tell you far more than a page of tool logos. Talk to our automation testing team to see how we hold up against this framework.
Frequently Asked Questions
-
What should you look for besides tool expertise when hiring a QA automation company?
Tool proficiency should only be an entry requirement. Evaluate the provider on six areas you will actually own after the engagement: framework design, test maintainability, flaky-test management, CI/CD pipeline integration, reporting quality, and handover to your internal team.
-
How do you evaluate a QA automation company's framework design?
Ask the provider to connect its proposed architecture to your product's actual risks rather than accepting generic terms like "modular" or "scalable." Request an annotated sample repository and a live walkthrough from the engineers who would deliver the work, and ask what they recommend not automating yet.
-
What is test flakiness and how should a QA automation company handle it?
A flaky test produces inconsistent pass or fail results against the same code. A credible vendor investigates the root cause of each flaky result, distinguishing a test defect from a real application defect, rather than relying only on automatic reruns. Quarantining an unstable test should have a named owner, an investigation ticket, and a review deadline, not be a permanent way to hide the problem.
-
What evidence should a QA automation company provide about CI/CD pipeline integration?
Ask them to deliberately introduce a known regression in a non-production branch and demonstrate that the correct failure actually blocks the intended release action. Also examine what happens when a prerequisite fails or a test run is incomplete, since some CI systems can report a skipped check as passing.
-
Why does handover matter when hiring a QA automation company?
A document handover is not the same as a capability transfer. Require an acceptance exercise where your own engineer, not the vendor, sets up the environment, runs the suite, diagnoses a failure, and submits a change through your pipeline, to confirm your team can operate independently after the engagement ends.
-
How should you compare proposals from different QA automation companies?
Run a bounded pilot with the same scope, constraints, and delivery engineers for each shortlisted provider, then score the six evaluation areas using real evidence (asserted, explained, demonstrated, independently reproduced) rather than sales promises. Also separate commercial quotes into implementation, infrastructure, maintenance, and exit costs before comparing price.
by Rajesh K | Sep 23, 2026 | API Testing, Blog, Latest Post |
Microservices make applications easier to divide, deploy, and scale independently, but they also make microservices API testing more distributed. A user request may travel through an API gateway, several services, databases, queues, and third-party APIs before it completes. As a result, testing only individual HTTP endpoints is not enough. Teams need a layered API testing strategy that verifies each service independently while also checking the contracts, dependencies, failure modes, and end-to-end workflows connecting those services.
How should microservices APIs be tested?
Microservices APIs should be tested at multiple layers: service-level functional tests, contract tests, integration tests, end-to-end tests, security tests, performance tests, and resilience tests. The most effective strategy runs fast, isolated tests early in CI and reserves slower tests involving multiple real services for scenarios that genuinely require them. If you’d rather have a team build this out, our API and backend testing services team applies this exact layered approach to production microservices.
Key takeaways
- Test each microservice independently before testing complete workflows.
- Use contract testing to detect incompatible API changes between consumers and providers.
- Test critical integrations against realistic databases, brokers, and infrastructure rather than mocking every dependency.
- Cover authentication, authorization, malformed input, rate limits, and other security conditions explicitly.
- Define measurable performance thresholds instead of treating load tests as informational reports.
- Keep a small number of end-to-end tests for high-value business workflows and diagnose failures with distributed tracing.
What is microservices API testing?
Microservices API testing is the process of verifying the behavior, compatibility, security, performance, and reliability of APIs used by independently deployable services.
The testing scope includes more than checking whether GET, POST, PUT, or DELETE requests return expected status codes. It may also cover:
- Request and response schemas
- Business rules
- Authentication and authorization
- Service-to-service contracts
- Database interactions
- Message queues and event streams
- Timeouts and retries
- Idempotency
- Rate limiting
- Error handling
- Performance under load
- Partial dependency failures
For HTTP APIs, an OpenAPI description can provide a machine-readable definition of endpoints, parameters, payloads, and responses. As of September 2026, OpenAPI Specification 3.2.0, released on September 19, 2025, is the latest published OAS version.
Microservices API testing vs. traditional API testing
Traditional API testing often focuses on whether a single API behaves correctly. Microservices API testing must additionally account for distributed ownership and independent change.
For example, an order service might depend on an inventory service whose team releases independently. Both services can pass their own functional tests while still failing together because one team changed a field name, response type, validation rule, or error structure.
That is why contract and integration testing become particularly important in microservice architectures.
Why does microservices API testing matter?
A microservice normally exposes only one part of a larger business operation. Failures can therefore originate far from the API that the client initially called.
Consider an e-commerce checkout:
Client
↓
API Gateway
↓
Order Service
|--------------------> Inventory Service
|
|--------------------> Payment Service
|
+--------------------> Event Broker ---> Shipping Service
A successful response from the order endpoint does not automatically prove that the system is correct. The order may have been stored while payment failed, inventory may have been reserved twice after a retry, or the shipping event may never have been published.
Distributed systems also make failures harder to diagnose because a single transaction crosses service and process boundaries. OpenTelemetry, for example, uses context propagation to correlate spans belonging to the same operation across services, making distributed traces particularly useful when debugging integration and end-to-end tests.
A comprehensive API testing strategy reduces the chance that independently correct services become collectively unreliable.
How does microservices API testing work?
An effective strategy divides testing into layers based on what needs to be proven and how many dependencies must be involved.
End-to-End Tests (fewest, highest cost)
↓
Integration / Workflow Tests
↓
Consumer Contract Tests
↓
Component / Service API Tests
↓
Unit Tests (most, lowest cost)
Tests nearer the bottom should generally be easier to isolate and run frequently. Tests nearer the top exercise more of the deployed system but introduce more moving parts, test data, infrastructure, and potential sources of failure.
The objective is not simply to maximize the number of tests. It is to place each risk at the lowest test layer capable of detecting it reliably.
1. Unit and component tests
Unit tests verify individual functions, classes, validators, or domain rules without network dependencies.
Component-level API tests run the microservice as a testable application while replacing selected external services. They can validate:
- Routing
- Serialization
- Input validation
- Error handling
- Business rules
- Authentication middleware
- HTTP status codes
These tests are useful for getting rapid feedback before infrastructure-heavy tests run.
2. Contract tests
Contract testing verifies that a service provider remains compatible with its consumers.
Pact describes a consumer-driven contract as an agreement in which the consumer records the interactions it requires and the provider verifies that it can satisfy them. Pact specifically distinguishes contract testing from provider functional testing: contract tests check shared assumptions rather than trying to test all provider behavior.
Contract tests are particularly useful when different teams independently deploy services.
For example, suppose the checkout service expects:
{
“productId”: “SKU-104”,
“available”: true,
“quantity”: 24
}
If the inventory service later renames available to inStock, its own tests might still pass. A consumer contract test can catch the incompatible change before deployment.
3. Integration tests
Integration tests verify that a service communicates correctly with real infrastructure or selected neighboring systems.
Typical dependencies include:
- PostgreSQL or MySQL
- Redis
- Kafka or RabbitMQ
- Object storage
- Identity services
- HTTP services
Testcontainers is designed for this category of testing. Its Java implementation creates lightweight, disposable instances of databases, message queues, web servers, and other containerized dependencies, allowing tests to begin from a known environment.
The point is not to start the entire production architecture for every integration test. Run only the dependencies required to verify the behavior under test.
4. End-to-end tests
End-to-end tests verify complete workflows across multiple deployed services.
Examples include:
- Register customer → authenticate → create order
- Add item → reserve inventory → collect payment
- Submit claim → validate policy → approve claim
- Create booking → charge card → send confirmation
These tests provide valuable confidence, but every participating service, dependency, network route, credential, and data store increases the number of possible failure causes.
Keep the suite focused on critical business journeys rather than duplicating every lower-level API scenario.
5. Performance tests
Performance tests establish how an API behaves under expected and exceptional traffic.
Useful measurements include:
- Request latency percentiles
- Throughput
- Error rate
- Saturation
- Dependency latency
- Timeout frequency
Performance tests become much more actionable when they have explicit acceptance criteria. Grafana k6 supports thresholds that turn metrics such as error rate and request duration into pass/fail conditions suitable for automated pipelines.
For example:
export const options = {
  thresholds: {
    http_req_failed: ['rate<0.01'],
    http_req_duration: ['p(95)<500']
  }
};
The exact thresholds should come from your own service objectives rather than arbitrary values copied from another system. Our performance testing services team typically defines these thresholds against your actual SLOs before load testing begins.
6. Security tests
Security testing must verify both technical vulnerabilities and API-specific access-control behavior.
The OWASP API Security Top 10 2023 identifies issues including broken object-level authorization, broken authentication, broken object-property authorization, unrestricted resource consumption, broken function-level authorization, server-side request forgery, and unsafe consumption of APIs.
Functional API suites should therefore include cases such as:
- Can User A retrieve User B’s object by changing its ID?
- Can a standard user call an administrator endpoint?
- Does an expired token still work?
- Can clients submit protected fields that should be server-controlled?
- What happens after repeated resource-intensive requests?
A 200 OK response does not prove an API is secure. Our security testing services team maps these API-specific checks directly to the OWASP API Security Top 10.
7. Resilience testing
Microservices must also behave predictably when dependencies are slow or unavailable.
Test conditions such as:
- Connection timeout
- Read timeout
- HTTP 500/503 responses
- Slow downstream responses
- Lost connections
- Duplicate events
- Broker unavailability
- Retry exhaustion
- Partial service degradation
A mock such as WireMock can return predefined responses and can also be used to reproduce controlled dependency behavior during testing. WireMock supports request matching and programmable HTTP stubs, along with features for simulating faults and stateful behavior.
Step-by-step: How to build a microservices API testing strategy
1. Map every service interaction
Start by identifying the boundaries around each microservice.
Document:
- Incoming API calls
- Outgoing API calls
- Databases
- Caches
- Message brokers
- Third-party services
- Authentication providers
- Events produced
- Events consumed
Why: You cannot select the correct testing layer until you know what the service depends on.
Expected result: A dependency map showing which interfaces can fail independently.
Common mistake: Documenting only public REST endpoints while ignoring service-to-service APIs and asynchronous events.
2. Establish machine-readable API contracts
Use OpenAPI for HTTP APIs where practical and Protocol Buffers for gRPC interfaces.
Define:
- Required fields
- Types
- Allowed values
- Response structures
- Error responses
- Authentication requirements
- Versioning rules
Why: A contract gives both humans and automated tooling a precise interface to validate.
Expected result: API implementation and test suites refer to a controlled source of interface truth.
Common mistake: Updating application code while leaving the published API specification unchanged.
3. Build service-level functional tests
Test the API’s own behavior before involving neighboring microservices.
Include:
- Valid requests
- Required-field validation
- Boundary values
- Malformed requests
- Unknown resource IDs
- Duplicate submissions
- Authentication failures
- Authorization failures
- Business-rule violations
- Expected error objects
Java teams can use REST Assured for code-based API assertions. Its current documentation shows REST Assured 6.0.1 as released on July 10, 2026.
An example test could look like this:
given()
    .contentType("application/json")
    .body("""
        {
          "customerId": "C-1024",
          "productId": "SKU-104",
          "quantity": 2
        }
        """)
.when()
    .post("/orders")
.then()
    .statusCode(201)
    .body("status", equalTo("PENDING"));
Add negative and boundary scenarios rather than stopping after the happy path.
4. Add consumer-provider contract verification
Identify APIs consumed by independently maintained applications or services.
For each important interaction:
- Record what the consumer actually requires.
- Produce the contract from consumer tests.
- Publish or share the contract.
- Verify it against the provider.
- Block incompatible provider releases.
Pact’s HTTP workflow follows this pattern: consumer tests generate a contract, the contract is shared, and provider verification replays the interactions against the provider.
Expected result: Breaking API changes fail before production deployment.
5. Test real infrastructure selectively
Replace mocks with real disposable infrastructure where implementation differences matter.
Use a real database when verifying:
- SQL behavior
- Transactions
- Migrations
- Constraints
- Index-dependent behavior
Use a real broker when verifying:
- Serialization
- Topics or queues
- Consumer configuration
- Delivery semantics
- Message metadata
Containerized environments are useful here because they provide controlled, repeatable dependencies without requiring a permanently shared integration environment.
6. Test asynchronous behavior explicitly
Event-driven microservices require a different assertion model from synchronous HTTP APIs.
Suppose:
POST /orders
       |
       +--> 202 Accepted
                 ↓
          OrderCreated event
                 ↓
           Inventory Service
Do not assume the downstream update exists immediately after receiving 202 Accepted.
Use bounded polling:
Create order
     ↓
Poll order state
     |
     +--> PENDING → retry
     |
     +--> CONFIRMED → pass
     |
     +--> REJECTED → evaluate scenario
     |
     +--> timeout → fail
Always impose a maximum waiting period. An unbounded sleep or polling loop hides failures and makes CI unpredictable.
7. Add security tests to normal CI
Security should not exist only as a late penetration-testing activity.
Automate checks for:
- Missing credentials
- Invalid credentials
- Expired tokens
- Role escalation
- Object-level access control
- Input manipulation
- Protected fields
- Unexpected HTTP methods
- Oversized requests
- Invalid content types
OWASP ZAP’s API scan can import OpenAPI, SOAP, or GraphQL definitions and perform API-oriented active scanning against discovered URLs. Because active scanning sends potentially hostile requests, run it only against systems where such testing is explicitly authorized.
8. Establish performance acceptance criteria
Identify the workload that represents the service’s expected operating conditions.
Then specify measurable criteria, for example:
Scenario: Create order
Traffic: expected peak profile
Error-rate requirement: < defined service target
p95 latency: < defined service target
Dependency timeout rate: < defined service target
Use thresholds so a regression can automatically fail the test stage rather than relying on someone to manually inspect charts.
9. Test dependency failures
For every significant synchronous dependency, test at least:
Successful response, business error, server error, timeout, invalid response, slow response, connection failure.
Also verify what your service does next:
- Does it retry?
- Is the retry bounded?
- Could it duplicate an operation?
- Does it return an appropriate error?
- Does it open a circuit breaker?
- Can it degrade gracefully?
Failure handling is part of the API contract users experience.
10. Gate releases at the appropriate CI stages
A practical pipeline might look like:
Commit
↓
Unit / Component Tests

Commit
↓
API Functional Tests

Commit
↓
Contract Verification

Commit
↓
Integration Tests
↓
Deploy Test Environment

Deploy Test Environment
↓
Critical Workflow Tests

Deploy Test Environment
↓
Security Scan

Deploy Test Environment
↓
Performance Smoke Test
↓
Release
Avoid running every expensive test on every code edit. Match execution frequency to the risk and cost of each test.
Practical example: Testing an Order Service API
Consider an e-commerce Order Service.
Business scenario
A customer submits an order. The service must:
- Validate the order.
- Check inventory.
- Create the order.
- Publish an OrderCreated event.
- Return the new order ID.
Preconditions
Customer C-1024 exists. Product SKU-104 exists. Inventory = 10 units. Requested quantity = 2.
Request
POST /orders
Content-Type: application/json
Authorization: Bearer <token>

{
  "customerId": "C-1024",
  "items": [
    {
      "productId": "SKU-104",
      "quantity": 2
    }
  ]
}
Expected response
{
“orderId”: “ORD-9001”,
“status”: “PENDING”
}
Expected HTTP status: 201 Created
Recommended tests
| S. No |
Test |
What it proves |
| 1 |
Valid order |
Basic API behavior works |
| 2 |
Quantity = 0 |
Request validation rejects invalid input |
| 3 |
Unknown product |
Business error is handled |
| 4 |
Missing token |
Authentication is enforced |
| 5 |
Another customer’s order ID |
Object-level authorization is enforced |
| 6 |
Inventory contract verification |
Order Service and Inventory Service agree on the interface |
| 7 |
Real database integration |
Order persistence works with the actual database engine |
| 8 |
Broker integration |
OrderCreated is serialized and published correctly |
| 9 |
Inventory timeout |
Failure policy behaves correctly |
| 10 |
Duplicate request with same idempotency key |
Retry does not create duplicate orders |
| 11 |
Peak workload |
Latency and error-rate objectives hold under expected load |
Example failure condition
Assume the inventory service normally returns:
{
“productId”: “SKU-104”,
“availableQuantity”: 10
}
A provider deployment changes it to:
{
“productId”: “SKU-104”,
“stock”: 10
}
The inventory service might still pass its internal functional tests.
An Order Service consumer contract that requires availableQuantity, however, should fail provider verification and prevent the incompatible change from progressing.
That is exactly the type of failure contract testing is designed to detect.
Microservices API testing strategies compared
No single testing strategy covers every risk.
| S. No |
Test type |
Primary purpose |
Real dependencies |
Relative execution cost |
Best use |
| 1 |
Unit |
Validate code logic |
No |
Low |
Functions and domain rules |
| 2 |
Component/API |
Validate one service |
Few or mocked |
Low |
Endpoint behavior and validation |
| 3 |
Contract |
Verify consumer/provider compatibility |
Usually isolated |
Low-medium |
Independently deployed services |
| 4 |
Integration |
Validate actual integrations |
Selected dependencies |
Medium |
Databases, brokers, infrastructure |
| 5 |
End-to-end |
Validate complete workflows |
Many |
High |
Critical business journeys |
| 6 |
Security |
Find access-control and security weaknesses |
Depends on scope |
Medium-high |
Security assurance |
| 7 |
Performance |
Validate capacity and latency objectives |
Usually realistic environment |
High |
Release and capacity validation |
| 8 |
Resilience |
Validate failure behavior |
Real or simulated failures |
Medium-high |
Timeouts, retries and degradation |
The right approach is therefore a portfolio of tests, not a choice between contract testing, integration testing, and end-to-end testing.
Best practices for testing microservices APIs
Keep service tests independently executable
A team should be able to test its service without starting the company’s entire platform. Isolation shortens feedback cycles and reduces failures caused by unrelated components.
Put compatibility checks before broad end-to-end tests
Use contract testing to detect service-interface incompatibilities close to the team introducing the change. This provides a more specific failure signal than discovering the same problem during a large multi-service test.
Test behavior, not just HTTP status codes
A response with 200, 201, or 204 may still contain incorrect data. Validate:
- Response schema
- Important field values
- Persistence
- Side effects
- Authorization
- Published events
- Downstream interactions
Use mocks deliberately
Mocks are valuable when the objective is to isolate a service or simulate rare failures. They are weak substitutes when the risk comes from a real implementation detail such as SQL behavior, broker configuration, serialization, TLS, or network communication.
Keep test data deterministic
A test should create or control the data it requires whenever feasible. Dependencies on long-lived shared test accounts and manually maintained database records frequently produce non-repeatable failures.
Test retries with idempotency in mind
A timeout does not always mean a downstream operation failed. For operations such as payments and order creation, verify that retries cannot unintentionally create duplicate business effects.
Make observability part of testability
Propagate trace context through synchronous and asynchronous service calls. Distributed traces help determine whether a failed workflow originated in the gateway, application logic, downstream service, database, or another dependency. OpenTelemetry defines context propagation specifically to correlate distributed operations across service boundaries.
Run tests at multiple lifecycle stages
Use fast functional and contract suites during pull requests, broader integration suites before deployment, and carefully controlled performance or security tests in suitable environments. Not every test needs the same trigger.
Common microservices API testing mistakes
| S. No |
Mistake |
Why it happens |
Impact |
Recommended fix |
| 1 |
Testing only happy paths |
Teams optimize for feature delivery |
Error handling remains unverified |
Add negative, boundary, and malformed-input tests |
| 2 |
Relying entirely on end-to-end tests |
They appear to test the “real system” |
Slow, fragile feedback |
Move checks to component, contract, and integration layers |
| 3 |
Mocking every dependency |
Isolation seems convenient |
Integration incompatibilities remain hidden |
Use real disposable infrastructure selectively |
| 4 |
Ignoring API contracts |
Teams coordinate changes informally |
Independent releases break consumers |
Add automated contract verification |
| 5 |
Hard-coded sleeps |
Async behavior is difficult to test |
Slow and flaky suites |
Use bounded polling based on observable state |
| 6 |
Checking only status codes |
Assertions are quick to write |
Incorrect payloads or side effects pass |
Validate schemas and business outcomes |
| 7 |
Sharing mutable test data |
Environment setup is centralized |
Tests interfere with one another |
Create isolated or uniquely identified data |
| 8 |
Ignoring authorization scenarios |
Authentication receives most attention |
Cross-user or cross-role access can remain exposed |
Add object- and function-level authorization tests |
| 9 |
Running load tests without thresholds |
Tests are treated as reports |
Regressions do not block releases |
Encode measurable acceptance criteria |
Why does an API test pass individually but fail in the full suite?
The most likely cause is shared mutable state or hidden test ordering. Check whether tests reuse the same customer, account, database row, queue, cache entry, token, or idempotency key. Generate unique test identifiers, reset state where appropriate, and make tests independent of execution order.
Why does a contract test fail even though the provider API works manually?
The consumer and provider may disagree about a detail that manual testing did not exercise. Compare required fields, data types, headers, status codes, nullability, error responses, and provider state. Avoid making contracts unnecessarily strict. Pact recommends contracts focus on interactions the consumer actually relies on rather than duplicating all provider functional behavior.
Why do microservices API tests fail intermittently?
Intermittent failures commonly originate from timing, asynchronous processing, shared data, dependency instability, or environmental contention. Correlate failures with traces and dependency logs before simply adding retries. Retrying the test can hide a genuine race condition.
Why does an asynchronous API test fail immediately after receiving a successful response?
A response such as 202 Accepted usually indicates that processing can continue after the HTTP request finishes. Verify completion through a business-visible state, event, or read endpoint and use bounded polling rather than expecting an immediate downstream update.
Why does the test environment behave differently from production?
The test environment may use different infrastructure, topology, configuration, authentication, resource limits, data volumes, or dependency versions. Compare the characteristics relevant to the failing scenario rather than assuming an environment is production-like merely because it uses the same application build.
Why does an API return 401 instead of 403?
A 401 Unauthorized response normally indicates that valid authentication is missing or unacceptable, while 403 Forbidden normally means the request was understood but access is not permitted. When testing authorization, first ensure the caller has valid credentials. Otherwise the test may exercise authentication rather than the permission rule it intended to verify.
Tools for microservices API testing
Tool selection should depend on the layer being tested rather than trying to standardize every API test on one platform.
| S. No |
Tool |
Good fit |
Notes |
| 1 |
Postman |
Exploratory, functional, workflow and regression API testing |
Collections can contain scripts and assertions and can run manually or through CI tooling. |
| 2 |
REST Assured |
Java API automation |
Provides a fluent Java API for HTTP request and response assertions. |
| 3 |
Pact |
Consumer-driven contract testing |
Generates consumer expectations and verifies provider compatibility. |
| 4 |
WireMock |
API mocking and fault simulation |
Supports programmable stubs and request matching for controlled dependency behavior. |
| 5 |
Testcontainers |
Integration testing with realistic infrastructure |
Creates disposable containerized databases, brokers, servers, and other dependencies. |
| 6 |
k6 |
Load and performance testing |
Supports executable performance thresholds suitable for CI gates. |
| 7 |
Schemathesis |
Schema-driven and property-based API testing |
Generates test cases from OpenAPI or GraphQL schemas and validates responses against the schema. |
| 8 |
OWASP ZAP |
Automated API security scanning |
Its API scan supports definitions including OpenAPI and GraphQL. |
| 9 |
OpenTelemetry |
Diagnosing distributed test failures |
Provides trace context propagation and distributed observability across services. |
A version-compatibility note for schema-based tools
Do not assume that every testing tool immediately supports the newest API specification, and re-check compatibility periodically since tool support changes. As of this writing, Schemathesis supports OpenAPI (Swagger) 2.0, 3.0, 3.1, and 3.2, alongside GraphQL schemas, so it has already caught up to the current OpenAPI 3.2.0 specification. Teams adopting a new OpenAPI version should still verify compatibility with their exact toolchain before upgrading specifications used by automated tests, since not every tool in a pipeline updates on the same schedule.
Limitations and risks of microservices API testing
A strong automated suite reduces risk but cannot prove that a distributed system will never fail. Several limitations remain.
Mocks can create false confidence. A mock reproduces the behavior you configured, not necessarily the behavior of the real dependency.
Shared environments create nondeterminism. Concurrent deployments, tests, and data changes can make failures difficult to reproduce.
End-to-end coverage becomes expensive. The number of possible service combinations, data states, and failure modes grows rapidly as architecture becomes more distributed.
Performance results are environment-dependent. A latency number measured in a small test cluster cannot automatically be treated as a production capacity guarantee.
Active security tests can be disruptive. Scanners may send malicious or resource-intensive requests and should be executed only in explicitly authorized environments.
Eventually consistent workflows need time-aware assertions. Treating every distributed update as immediate produces flaky tests and incorrect expectations.
The goal is therefore risk-based confidence, not an impossible promise that every combination has been tested.
Conclusion
Testing microservices APIs successfully requires more than sending requests to individual endpoints. The strongest approach is layered: validate service behavior locally, protect service boundaries with contracts, exercise important infrastructure through integration tests, verify critical workflows end to end, test authorization and failure handling explicitly, and use measurable performance criteria. Most importantly, put each test at the lowest layer that can detect the intended failure reliably. Doing so gives teams faster feedback without sacrificing the integration, security, performance, and resilience coverage that distributed architectures require.
A practical next step is to map one production-critical workflow, identify every service and dependency it crosses, and classify its current tests as functional, contract, integration, end-to-end, security, performance, or resilience. Missing categories reveal where the next testing investment is likely to provide the greatest value. Talk to our API testing team if you want help closing those gaps.
Frequently Asked Questions
-
What types of tests are most important for microservices APIs?
Functional, contract, integration, security, performance, resilience, and selected end-to-end tests address different risks. Contract tests are particularly valuable between independently deployed services, while integration tests are necessary where real databases, brokers, or protocols may behave differently from mocks. End-to-end tests should concentrate on critical business workflows rather than duplicating every service-level test.
-
What is the difference between contract testing and integration testing?
Contract testing verifies interface compatibility; integration testing verifies that components work together in a real or realistic integration. A contract test can prove that an Inventory Service still returns data required by an Order Service without starting the complete application. An integration test may start the service with its actual database, broker, or neighboring system to verify runtime communication.
-
Should microservices API tests use mocks or real services?
Use both according to the risk being tested. Mocks are appropriate for service isolation, deterministic errors, timeouts, and uncommon dependency conditions. Use real implementations when behavior depends on database semantics, message brokers, serialization, network protocols, authentication infrastructure, or other details a mock may not reproduce.
-
Should every microservice be included in end-to-end testing?
No. A complete all-services suite is not necessary for every API requirement. Use broad end-to-end tests for high-value business journeys, and verify most logic and compatibility at lower testing layers. This keeps failures easier to diagnose while still providing system-level confidence where it matters.
-
How should asynchronous microservices APIs be tested?
Assert against observable completion rather than assuming immediate consistency. After triggering an asynchronous operation, poll a status endpoint, observe an event, or query the resulting business state until the expected outcome appears or a defined timeout expires. Avoid fixed sleeps because processing time can vary across environments.
-
How do you test microservices API security?
Combine automated security scanning with explicit business-level authorization tests. Validate missing and invalid credentials, cross-user resource access, role restrictions, protected fields, resource consumption, unsafe input, and other relevant API risks. The OWASP API Security Top 10 is a useful threat-oriented starting point, but the test cases should be mapped to the application's actual authorization and business model.
-
What is the best tool for testing microservices APIs?
There is no single best tool because different tools solve different testing problems. Postman and REST Assured suit functional automation, Pact targets consumer-driven contracts, Testcontainers supports realistic integration environments, WireMock supports dependency simulation, k6 targets performance testing, and ZAP supports security scanning. Select tools according to the test layer and the technology stack your team maintains.