by Rajesh K | Oct 5, 2026 | API Testing, Blog, Latest Post |
API negative testing deliberately sends invalid, unauthorized, malformed, out-of-range, or excessive requests to verify that an API rejects them safely and predictably. A successful negative test confirms not only the expected error status, but also that no forbidden state change occurred, no sensitive data leaked, and the documented error contract remained intact. A test that merely checks response.status == 400 is therefore incomplete. Good negative testing asks a stricter question: when a client violates one specific API rule, does the API fail in the exact way its security policy and contract require?
That distinction matters for authentication, authorization, input validation, rate limiting, and error handling because an API can return an error while still leaking data, modifying state, executing expensive backend work, or breaking client integrations. Codoid’s API and backend testing services apply these exact checks to production APIs.
Key Takeaways
- Treat authentication and authorization as different test dimensions. Authentication establishes identity. Authorization decides whether that identity may perform a specific action.
- Test boundaries immediately below, at, and immediately above every documented limit instead of relying only on obviously invalid values.
- Validate rate limits around the actual threshold, reset boundary, concurrency model, and identity dimension used by the limiter.
- Assert the complete failure contract: HTTP status, headers, media type, machine-readable error fields, and absence of prohibited information.
- For every rejected write operation, verify no state mutation or unintended downstream side effect occurred.
- Generate negative tests from OpenAPI or JSON Schema where practical, but supplement them with security and business-rule cases the schema cannot express.
Table of Content
What Is API Negative Testing?
API negative testing covers requests that the service is expected to reject rather than successfully process. Instead of validating that a valid request produces a valid result, it validates that an invalid request produces the correct failure without causing harm.
A typical API negative testing workflow models the operation as a sequence of controls:
    Client request
        ↓
    Authentication
        ↓
    Authorization
        ↓
    Request and schema validation
        ↓
    Resource and rate controls
        ↓
    Business operation
        ↓
    Response and error mapping
Real systems may enforce these controls in a different order. A gateway might rate-limit before authentication, for example, while application-level quotas could be evaluated after identity has been established. The test should therefore focus on externally observable guarantees rather than assume an internal implementation.
For each negative case, verify five things:
- The request is rejected.
- The status and protocol headers are correct.
- The response body matches the documented error contract.
- No unauthorized data is returned.
- No prohibited state change or downstream side effect occurs.
The fifth assertion is particularly important for write operations. An API returning 403 after a database write has already occurred is still broken. This is the core idea behind API negative testing.
What Does API Negative Testing Include?
Common categories in a structured API negative testing plan include authentication, authorization, input validation, resource limits, rate limiting, and the error contract itself.
| S. No |
Area |
Question being tested |
Example negative stimulus |
| 1 |
Authentication |
Can the API establish a valid caller identity? |
Missing, expired, revoked, malformed, or incorrectly scoped token |
| 2 |
Authorization |
May this caller perform this action on this resource? |
User A requests User B’s invoice |
| 3 |
Input validation |
Does the request satisfy syntactic and semantic constraints? |
quantity=101 when the maximum is 100 |
| 4 |
Resource limits |
Can a request exceed safe resource constraints? |
Oversized body or excessive array length |
| 5 |
Rate limiting |
Has this caller exceeded an allowed request rate or quota? |
61st request in a 60-request window |
| 6 |
Error contract |
Does failure remain predictable for API consumers? |
Validation error must conform to the documented problem schema |
Negative testing is related to security testing and fuzz testing, but the terms are not interchangeable. Security testing investigates exploitable weaknesses and broader attack paths. Fuzzing generates large or unusual input spaces to discover unexpected behavior. API negative testing starts from an explicit rule, such as “quantity must be from 1 to 100,” and verifies behavior when that rule is violated.
Why Is API Negative Testing Important?
APIs concentrate security-sensitive behavior at trust boundaries. The OWASP API Security Top 10 identifies broken object-level authorization, broken authentication, broken object-property authorization, unrestricted resource consumption, and broken function-level authorization among its leading API risks.
Negative tests expose failures that positive happy-path tests often cannot see. For example:
- A valid customer retrieving their own order proves that GET /orders/{id} works. It does not prove that the customer cannot retrieve another tenant’s order.
- A valid JWT proves that authentication can succeed. It does not prove that an expired or wrong-audience token is rejected.
- A request with quantity=50 proves that a normal value works. It does not prove that 0, 101, 1.5, “50”, or an extremely large integer is handled correctly.
- Ten successful requests prove that an endpoint responds. They do not prove what happens at the rate-limit threshold.
- Receiving a 400 proves that something failed. It does not prove that the response matches the API’s documented error schema.
The practical goal of API negative testing is therefore controlled failure. Invalid requests should fail without bypassing security, corrupting state, creating unexpected costs, or forcing API consumers to reverse-engineer inconsistent errors.
Step 1: Turn the API Contract into Explicit Rejection Rules
Start with the OpenAPI description, JSON Schema definitions, authentication configuration, authorization policy, quota rules, and business requirements.
The OpenAPI Specification describes operation responses as mappings between HTTP response codes and expected responses and explicitly says known errors should be documented. JSON Schema provides explicit validation keywords such as minimum, maximum, minLength, maxLength, minItems, and maxItems, which make natural sources for boundary tests.
Convert every constraint into a testable rule. For example:
    quantity:
      type: integer
      minimum: 1
      maximum: 100

    sku:
      type: string
      minLength: 1
      maxLength: 32

    lineItems:
      type: array
      minItems: 1
      maxItems: 50
Expected result: every documented constraint maps to at least one passing case and one or more failing cases.
Step 2: Create Controlled Identities for Authentication and Authorization Tests
Prepare test credentials representing the meaningful security states in the system. For a multi-tenant API, that might include:
- anonymous
- valid_user_tenant_A
- valid_user_tenant_B
- tenant_A_admin
- read_only_user
- expired_token_user
- revoked_token_user
- token_without_required_scope
Authentication and authorization must be tested separately. OWASP defines authentication as verifying an entity’s identity, while authorization determines whether that entity is approved to perform a requested operation. OWASP recommends deny-by-default authorization and permission checks on every request. For a deeper look at these controls, see Codoid’s guide on API test automation using REST Assured.
Expected result: a test can deliberately vary identity, role, scope, tenant, ownership, and credential validity without relying on production accounts.
Common mistake: using a single administrator token for the entire automated API negative testing suite. That can make authorization defects invisible.
Step 3: Test Authentication Failures Before Business Behavior
For every protected endpoint, test at least the authentication states applicable to the API:
- No Authorization header
- Empty credentials
- Unsupported authentication scheme
- Malformed bearer token
- Invalid signature
- Expired token
- Token not yet valid
- Wrong issuer or audience
- Revoked credential where revocation is supported
- Multiple competing credential mechanisms when prohibited
For HTTP protected resources, RFC 9110 defines 401 Unauthorized as the response when the request lacks valid authentication credentials, and requires a server generating 401 to send at least one WWW-Authenticate challenge.
RFC 6750 adds bearer-token semantics: an invalid or expired bearer token normally maps to 401 with invalid_token, while insufficient scope normally maps to 403 with insufficient_scope.
Example assertion:
    pm.test("expired token is rejected", () => {
      pm.response.to.have.status(401);
      pm.expect(
        pm.response.headers.has("WWW-Authenticate")
      ).to.be.true;
    });
Do not stop at the status assertion. Also verify that the protected resource did not appear in the body.
For authentication endpoints such as login or password recovery, negative testing should additionally look for account-enumeration differences. OWASP recommends generic authentication responses so different messages, HTTP responses, or timing behavior do not reveal unnecessarily whether a particular account exists.
How Should Authorization Be Negative-Tested?
Authorization tests answer a specific question: the API knows who I am, but am I allowed to do this exact thing to this exact resource?
Horizontal Authorization
A caller uses another user’s or tenant’s resource identifier.
    GET /v1/orders/order-belongs-to-tenant-b
    Authorization: Bearer <tenant-A-token>
The operation must not expose Tenant B’s resource. OWASP identifies manipulation of user-controlled object identifiers as a common route to broken object-level authorization and recommends validating permission for each requested object.
Vertical Authorization
A lower-privileged account invokes an administrative operation:
    DELETE /v1/admin/users/123
    Authorization: Bearer <standard-user-token>
The API should deny the operation without performing it.
Function-Level Authorization
Test every relevant HTTP method, not merely the URL. A user permitted to GET /v1/projects/123 must not automatically be permitted to DELETE /v1/projects/123. OWASP’s broken function-level authorization category specifically covers situations where callers gain access to functions they should not be able to execute.
Property-Level Authorization
Try adding sensitive properties the normal client never sends:
    {
      "displayName": "Alice",
      "role": "super_admin",
      "accountBlocked": false
    }
OWASP warns that improperly protected object properties can result in unauthorized disclosure or manipulation and recommends explicitly controlling which properties may be read or changed.
Tenant Isolation
Cross-tenant testing should cover direct identifiers, searches, exports, nested resources, bulk operations, and indirect references. A useful authorization matrix is Actor x Resource x Action x Context.
| S. No |
Actor |
Resource |
Action |
Expected |
| 1 |
Tenant A user |
Tenant A invoice |
READ |
Allow |
| 2 |
Tenant A user |
Tenant B invoice |
READ |
Deny |
| 3 |
Tenant A user |
Tenant A invoice |
DELETE |
Deny |
| 4 |
Tenant A admin |
Tenant A invoice |
DELETE |
Allow |
Run this matrix automatically as authorization policies evolve.
Should an Unauthorized API Return 401, 403, or 404?
The correct answer depends on what failed.
| S. No |
Situation |
Typical response |
| 1 |
Authentication credential is missing or invalid |
401 Unauthorized |
| 2 |
Caller is authenticated but not allowed to perform the operation |
403 Forbidden |
| 3 |
Server deliberately conceals whether the forbidden resource exists |
404 Not Found |
RFC 9110 defines 403 as a request understood by the server but refused. It also explicitly permits an origin server to return 404 instead when it wants to hide the existence of a forbidden resource.
This means a wrong-tenant object test is not automatically defective because it returns 404. The important assertion is that the behavior matches the documented security policy and does not reveal whether another tenant owns the identifier through body contents, response metadata, or inconsistent behavior.
How Should API Input Boundaries Be Tested?
Boundary testing checks values immediately surrounding every allowed limit. If a field permits integers from 1 through 100, test:
- 0, reject
- 1, accept
- 2, accept
- 99, accept
- 100, accept
- 101, reject
Numeric Boundaries
Test minimum minus one, exact minimum, exact maximum, maximum plus one, negative values, zero, fractions where integers are required, extremely large positive and negative values, and numeric strings such as “100” if strict typing is expected. JSON Schema differentiates inclusive minimum/maximum from exclusiveMinimum/exclusiveMaximum, making the contract’s exact boundary semantics important.
String Boundaries
For maxLength: 32, test 31, 32, and 33 characters. Also test empty strings, whitespace-only strings, Unicode characters, normalization-sensitive values, invalid patterns, unexpected control characters, and extremely long values.
Collection Boundaries
For arrays, test 0 items, minimum minus one, minimum, maximum, maximum plus one, very large arrays, and duplicate elements when uniqueness is required.
Type Boundaries
Do not assume coercion is harmless. If the schema says quantity: 10, also test:
    {"quantity": "10"}
    {"quantity": true}
    {"quantity": null}
    {"quantity": []}
    {"quantity": {}}
Whether “10” is accepted or rejected should be a deliberate contract decision rather than an accidental framework conversion.
Missing and Unexpected Fields
Test when required properties are missing, and also inject undocumented properties such as an isAdmin flag. Unknown-field behavior should be explicit. Rejecting additional properties is often useful for security-sensitive write models. APIs that intentionally tolerate unknown fields should test that those values cannot alter internal state.
Request-Size Boundaries
OWASP recommends imposing request-size limits and rejecting payloads that exceed them. RFC 9110 defines 413 Content Too Large for requests the server refuses because the request content exceeds what it is willing or able to process. Similarly, an unsupported request media type is appropriately represented by 415 Unsupported Media Type.
Should Validation Errors Return 400 or 422?
Both can be valid depending on the API’s contract and the nature of the failure.
- 400 Bad Request is commonly used for a request that cannot be processed as a valid request.
- 422 Unprocessable Content has a more specific semantic meaning: the server understands the media type and the request syntax is correct, but it cannot process the contained instructions.
| S. No |
Failure |
Typical status |
| 1 |
Malformed JSON |
400 |
| 2 |
Unsupported Content-Type |
415 |
| 3 |
Valid JSON, quantity violates range |
422 |
| 4 |
Payload exceeds configured size |
413 |
This mapping is not a universal mandate for every API. What matters for automated API negative testing is that the chosen behavior is deliberately documented and consistently implemented.
How Should API Rate Limits Be Negative-Tested?
Rate-limit testing requires more than sending requests until one fails. First identify the policy, for example 60 requests per minute per API client. Then test the threshold:
- Request 59, allowed
- Request 60, allowed
- Request 61, rejected
This assumes that is the documented inclusive policy. RFC 6585 defines 429 Too Many Requests for clients that have sent too many requests in a given amount of time. A 429 response may include Retry-After to indicate how long the client should wait.
Identity Dimension
Determine whether quotas apply by user, OAuth client, API key, tenant, source IP, endpoint, account plan, or a combination of dimensions. Then prove isolation between them. If Client A exhausts its quota, Client B should not be throttled unless they intentionally share the same quota.
Window Boundaries
Test immediately before and after the reset. For fixed windows, pay particular attention to the transition between windows. For sliding-window or token-bucket algorithms, test the documented replenishment behavior instead of assuming a fixed reset.
Burst Behavior
An API might permit 1,000 requests per hour but only 20 requests per second. Test both sustained and burst limits when both exist.
Concurrency
A limiter that behaves correctly for sequential traffic may fail when 50 requests arrive concurrently.
Side Effects
This is one of the highest-value checks in API negative testing:
    Request 61 -> 429
    Database writes caused by request 61 -> 0
    Emails caused by request 61 -> 0
    Payment-provider calls caused by request 61 -> 0
Rate limiting that executes the expensive business operation and only later converts the response to 429 does not provide the intended resource protection. OWASP’s API resource-consumption guidance recommends limiting interaction frequency and setting limits on input sizes and other resource-consuming operations. Codoid’s API monitoring guide covers related verification patterns for production systems.
How Should API Error Contracts Be Tested?
An error response is an API contract just as much as a successful response. Clients often depend on HTTP status, Content-Type, authentication or retry headers, a stable machine-readable error code, validation-field locations, human-readable detail, and a correlation or trace identifier.
RFC 9457 defines Problem Details for HTTP APIs and the application/problem+json media type. Its standard members include type, status, title, detail, and instance. APIs can define additional members for domain-specific information.
Example:
    HTTP/1.1 422 Unprocessable Content
    Content-Type: application/problem+json

    {
      "type": "https://api.example.com/problems/validation-error",
      "title": "Request validation failed",
      "status": 422,
      "code": "VALIDATION_ERROR",
      "detail": "One or more request fields are invalid.",
      "traceId": "01K5EXAMPLE",
      "errors": [
        {
          "field": "quantity",
          "code": "OUT_OF_RANGE"
        }
      ]
    }
In this example, code, traceId, and errors are application-specific extensions rather than mandatory RFC 9457 fields.
Negative tests should assert that:
- HTTP status equals body.status
- Content-Type equals the expected problem media type
- code is a documented machine-readable value
- Required members exist
- Member types match the schema
- Field errors identify the correct field
- Trace identifier has the expected format
- No unknown sensitive fields appear
RFC 9457 specifically warns that problem details should not expose implementation internals or sensitive information. OWASP similarly recommends avoiding stack traces and unnecessary technical information in client-facing errors.
Test for accidental exposure of:
- Stack traces
- SQL fragments
- Filesystem paths
- Internal hostnames
- Library versions
- Access tokens
- API keys
- Passwords
- Connection strings
- Personal information unrelated to the error
Practical Example: Negative-Testing a Multi-Tenant Orders API
Consider POST /v1/orders with these rules:
- Authentication: OAuth bearer token
- Required scope: orders:write
- Tenant: derived from authenticated identity
- quantity: integer from 1 to 100
- sku: 1 to 32 characters
- lineItems: 1 to 50 entries
- Content-Type: application/json
- Rate limit: 60 requests per minute per client
- Error format: application/problem+json
A useful negative suite for this endpoint in API negative testing could contain:
| S. No |
Test |
Input |
Expected result |
| 1 |
Missing token |
No Authorization header |
401 with authentication challenge, no order created |
| 2 |
Expired token |
Expired bearer token |
401, no order created |
| 3 |
Missing scope |
Valid token without orders:write |
403, no order created |
| 4 |
Cross-tenant object |
Tenant A accesses Tenant B order |
Contract-defined 403 or concealed 404, zero data leakage |
| 5 |
Quantity below minimum |
quantity: 0 |
Contract-defined validation error |
| 6 |
Quantity above maximum |
quantity: 101 |
Contract-defined validation error |
| 7 |
Wrong type |
quantity: “10” |
Reject if strict schema contract |
| 8 |
Missing required field |
No sku |
Validation error naming sku |
| 9 |
Unknown sensitive field |
“approved”: true |
Reject or safely ignore according to contract, approval state unchanged |
| 10 |
Unsupported media type |
Content-Type: text/plain |
415 |
| 11 |
Oversized request |
Body larger than configured maximum |
413 |
| 12 |
Rate limit exceeded |
Request above allowed quota |
429 with documented retry metadata |
| 13 |
Error contract |
Any rejected request |
Problem document validates against error schema |
| 14 |
Side-effect check |
Any rejected POST |
No database row or downstream order event |
The final assertion is what turns this from simple response testing into robust API negative testing. For example:
    response = client.post(
        "/v1/orders",
        headers={"Authorization": token_without_scope},
        json={"sku": "SKU-123", "quantity": 10},
    )

    assert response.status_code == 403

    body = response.json()
    assert body["status"] == 403
    assert body["code"] == "INSUFFICIENT_SCOPE"

    # Critical side-effect assertion
    assert orders.count_for_test_id(test_id) == 0
Authentication vs Authorization vs Validation vs Rate Limiting
| S. No |
Control |
Primary question |
Typical negative test |
Main failure being prevented |
| 1 |
Authentication |
Who is the caller? |
Invalid or expired token |
Identity spoofing |
| 2 |
Authorization |
May this caller do this? |
Access another user’s object |
Privilege escalation and data leakage |
| 3 |
Input validation |
Is this request structurally and semantically acceptable? |
Out-of-range value |
Invalid state, parser or application defects |
| 4 |
Rate limiting |
Is the caller consuming more than policy allows? |
Request above quota |
Abuse and resource exhaustion |
| 5 |
Error contract |
Does failure remain machine-readable and safe? |
Validate every 4xx and 5xx response |
Client breakage and information leakage |
These controls reinforce one another, but passing one never proves another. A request can be authenticated yet unauthorized. It can be authorized yet contain invalid data. It can be valid and authorized but over quota. And every one of those failures can still return a malformed or insecure error response.
API Negative Testing Best Practices
Assert Exact Outcomes Instead of Any 4xx
A negative case should encode the rule being tested. Prefer specific assertions such as status code 403 with code INSUFFICIENT_SCOPE over a broad range check. Broad assertions allow regressions such as an expected 403 becoming 404, 422, or 429 without anyone noticing.
Verify State After Every Rejected Write
For POST, PUT, PATCH, and DELETE, validate persistence and downstream effects. A rejection is successful only when prohibited work did not occur. This is the core discipline of mature API negative testing.
Generate Boundary Cases Systematically
For every minimum and maximum, generate values around the transition: min minus one, min, min plus one, max minus one, max, max plus one. The same principle applies to dates, page sizes, file sizes, list cardinality, quotas, timeouts, and monetary limits.
Keep Authorization Rules in a Machine-Readable Matrix
An actor-resource-action matrix reduces gaps when endpoints or roles change. OWASP recommends automated authorization evaluation because authorization defects frequently appear as applications evolve.
Validate Responses Against the API Specification
OpenAPI can define successful and error responses, response headers, and body schemas. Treat contract mismatch as a test failure rather than accepting undocumented behavior. For a broader set of validation checks, refer to the REST API testing checklist.
Separate Protocol Assertions from Business Assertions
For a forbidden order cancellation, structure assertions into four groups:
- Protocol: status equals 403, media type equals application/problem+json
- Contract: error.code equals CANCELLATION_FORBIDDEN
- Security: response contains no forbidden order details
- State: order remains unchanged, no refund was initiated
This structure makes failures easier to diagnose.
Keep Negative Tests Deterministic
Use isolated identities, known resource ownership, controlled clocks where appropriate, and resettable rate-limit state. A test that depends on whatever quota happens to remain in a shared environment will eventually become flaky.
Common API Negative Testing Mistakes
| S. No |
Mistake |
Why it happens |
Impact |
Recommended fix |
| 1 |
Checking only the HTTP status |
Tests are written quickly |
Data leaks and side effects can be missed |
Assert body, headers, state, and side effects |
| 2 |
Treating authentication and authorization as one test |
Both involve access control |
Horizontal and vertical privilege defects survive |
Maintain separate AuthN and AuthZ matrices |
| 3 |
Testing only obviously bad values |
“abc” is easy to invent |
Off-by-one defects remain |
Test values immediately around boundaries |
| 4 |
Using only admin credentials |
Convenient test setup |
Authorization defects become invisible |
Create identities for each policy boundary |
| 5 |
Accepting any 4xx |
Makes suites less brittle |
Contract regressions go unnoticed |
Assert exact documented response |
| 6 |
Ignoring gateway-generated errors |
Application team owns only app code |
401, 413, and 429 schemas differ from application errors |
Contract-test gateway and application failures |
| 7 |
Rate-testing sequentially only |
Simple test loops |
Concurrency defects remain |
Add burst and parallel tests |
| 8 |
Assuming 403 is always required |
Simplified status-code rules |
Concealed-resource policies are violated |
Allow documented 404 concealment |
Troubleshooting Common Failures
Why does an invalid request return 500 instead of 4xx?
The invalid condition may be reaching business code or a parser that throws an unhandled exception. Reproduce the smallest failing payload, inspect correlated server logs, and identify the layer that should have rejected it. A malformed client request should not normally force consumers to interpret an internal server failure.
Why do rate-limit tests pass locally but fail in staging?
The environments may use different limiters, distributed state stores, gateway policies, clock behavior, or shared quotas. Verify the limit value, identity key, window algorithm, burst configuration, shared versus isolated quota, number of gateway instances, and whether previous tests consume the same quota. Use dedicated test identities where possible.
Why do application validation errors match the schema but gateway errors do not?
Your API may have multiple error producers. Authentication, request-size enforcement, rate limiting, proxies, gateways, application middleware, and business code can each generate responses. Inventory every error-producing layer and apply the same external contract where feasible, or explicitly document different contracts when standardization is impossible.
Why does a rejected request still mutate state?
This is the most serious failure mode in API negative testing. Check whether the rejection happens before or after the business transaction commits. Check whether the operation runs in a queued worker that receives the request before validation. Check whether a downstream call fires before the response is constructed. Add explicit side-effect assertions to catch this class of defect.
Tools for API Negative Testing
No single tool covers every dimension of API negative testing.
OpenAPI and Schema-Driven Testing
Schemathesis can generate property-based test cases from OpenAPI and GraphQL schemas, including boundary values, type violations, and response-schema checks. It supports current OpenAPI versions as well as earlier ones. This is useful for broad schema-derived coverage, but business authorization and domain-specific invariants still require explicit assertions.
Request Collections and Workflow Tests
Postman supports post-response JavaScript assertions for status codes, response data, headers, and workflow behavior, and its documentation specifically includes invalid or incomplete input as an API-testing use case. It works well when teams already maintain request collections and want readable regression scenarios.
Code-Based API Suites
REST Assured remains an option for Java-based HTTP API testing, while Python teams can implement equivalent suites with their existing HTTP test clients and test frameworks. Code-based suites are especially useful when negative tests must inspect databases, queues, emitted events, or other state after the HTTP request. Codoid’s guide on API test automation using REST Assured covers this approach in detail.
Load-Capable Tooling
For rate-limit and concurrency tests, use tooling capable of controlled parallel request generation rather than a simple sequential loop. Codoid’s API monitoring guide covers related verification patterns.
Whatever tool is selected, record enough evidence to reproduce: test identity, request, response, timestamp, correlation ID, rate-limit state where observable, and post-request state.
Limitations and Risks of API Negative Testing
Negative automation is powerful, but it does not replace a dedicated security assessment.
Schema-generated cases cannot automatically understand every business rule. A tool can infer that quantity has maximum: 100. It cannot necessarily infer that a support agent may read an invoice but may not approve a refund above a specific amount.
Rate-limit and authentication tests can also have real side effects. Poorly isolated tests may lock test accounts, trigger fraud defenses, consume SMS or email quotas, call paid providers, or throttle other teams sharing an environment.
Other limitations of API negative testing include:
- Eventual consistency can make post-condition assertions timing-sensitive.
- Long-lived JWT claims can complicate permission-revocation tests.
- Gateway and application configurations may differ between environments.
- A documented schema can itself be wrong.
- Automated negative tests cannot prove the absence of all exploitable authorization paths.
- A correct 4xx response alone does not prove the server avoided prohibited work.
Use negative automation as continuous regression protection, then complement it with architecture review, threat modeling, observability, and security testing. For a broader foundation, see the REST API testing checklist.
Conclusion
Effective API negative testing is not about proving that an API can return errors. It is about proving that the API fails correctly. For each protected operation, test invalid authentication, forbidden actions, cross-user and cross-tenant access, exact input boundaries, resource limits, rate-limit transitions, and the complete machine-readable error contract. Then add the assertion most teams overlook: verify that rejected operations did not change state or trigger prohibited downstream work.
A practical next step is to take one high-risk API endpoint and build a negative-test matrix containing authentication state, authorization state, input boundary, rate-limit state, expected error contract, and expected side effects. Automate that matrix in CI, expand it endpoint by endpoint, and treat every documented failure response as part of the API’s public contract. Codoid’s QA automation services help teams build this negative-test discipline into their delivery pipelines.
Frequently Asked Questions
-
What is the difference between positive and negative API testing?
Positive testing verifies that valid requests produce the intended successful result. Negative testing verifies that invalid, unauthorized, malformed, excessive, or otherwise prohibited requests are rejected safely. Mature API suites need both because successful happy paths provide little evidence about access-control enforcement, validation boundaries, throttling, or error behavior.
-
What is the most important assertion in a negative API test?
For security-sensitive write operations, one of the most important assertions is that the rejected request produced no prohibited side effect. Test the response, but also inspect database state, emitted events, downstream calls, or other observable effects where practical.
-
Should a missing token return 401 or 403?
For an HTTP resource requiring authentication, a missing or invalid credential is normally represented by 401 Unauthorized, and RFC 9110 requires a WWW-Authenticate challenge with a 401 response. An authenticated caller that lacks permission normally receives 403 Forbidden.
-
Should invalid API input return 400 or 422?
It depends on the contract and the type of invalidity. 422 Unprocessable Content specifically describes content whose media type and syntax are understood but whose instructions cannot be processed. Malformed requests may instead use 400. Pick a documented convention and test it consistently.
-
How do you test API authorization effectively?
Build tests around actors, resources, actions, and contextual rules. Include same-role cross-user access, cross-tenant identifiers, lower-role access to privileged functions, hidden object properties, bulk operations, and changed permissions. Do not infer authorization from successful authentication.
-
How do you test an API rate limit?
Use a controlled identity and send requests around the documented threshold, for example limit minus one, limit, and limit plus one. Then test window reset, concurrency, burst limits, identity isolation, retry metadata, and whether rejected requests execute downstream work. 429 Too Many Requests is the standard status for rate limiting.
-
Should an API expose stack traces in error responses?
No for normal production-facing error contracts. RFC 9457 warns against exposing implementation details through problem responses, and OWASP recommends avoiding client-visible stack traces and other internal technical information. Use a correlation identifier to connect the client-visible error with protected server-side diagnostics.
-
Can OpenAPI be used to automate negative tests?
Yes. OpenAPI describes parameters, schemas, security requirements, and expected responses, giving schema-aware tools enough information to generate many invalid and boundary cases automatically. However, generated tests must be supplemented with business authorization, tenant isolation, workflow, side-effect, and abuse scenarios that are not fully described by the API description.
by Rajesh K | Oct 3, 2026 | Mobile App Testing, Blog, Latest Post |
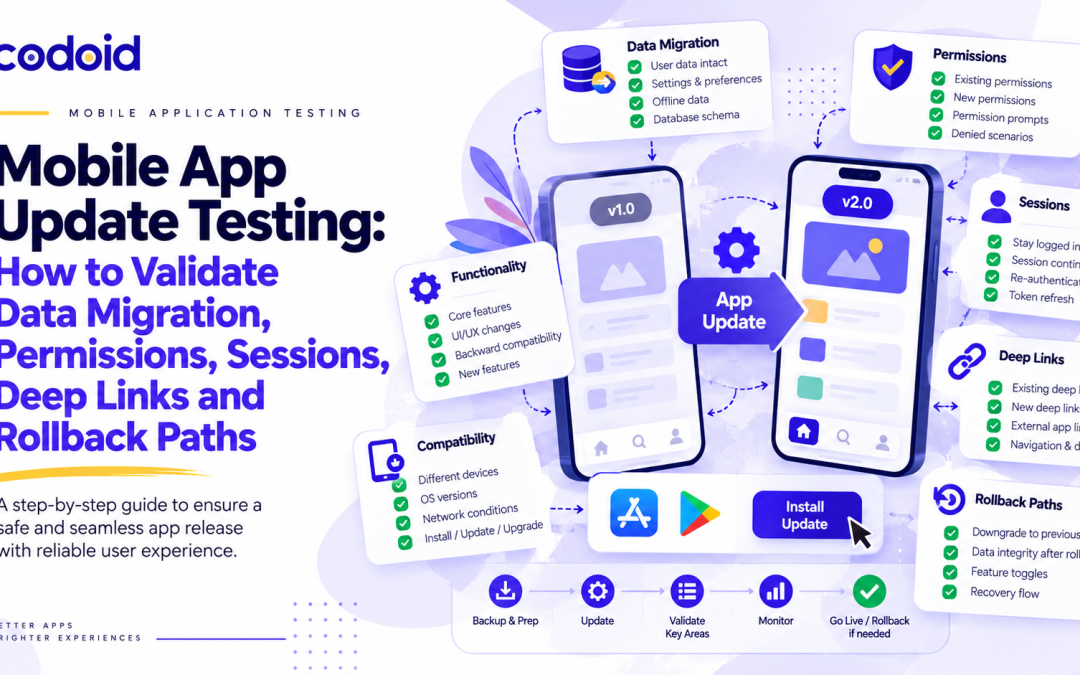
Mobile app update testing verifies that a newer app version works correctly with the data, permissions, credentials, and navigation history left by an older version. A complete test checks the installation, first launch, subsequent use, and failure recovery. It is not simply whether the updated app opens. Fresh-install testing is not a substitute. Apple’s release-testing guidance explicitly identifies data migration, Keychain access, and stored preferences as update conditions that may be absent from a new installation.
The central question is straightforward: can an existing user continue safely after the update, including when something goes wrong? Codoid’s mobile app testing services cover this exact kind of release validation end to end.
Table of Contents
What Should Mobile App Update Testing Cover?
Use these five areas to organize the test plan and define observable pass criteria. Treat these as acceptance criteria rather than separate smoke tests. For example, opening an old notification after an update may require migration, session restoration, authorization checks, and navigation to succeed together.
| S. No |
Test area |
What to validate |
Evidence of success |
| 1 |
Data migration |
Existing records, files, preferences, and pending operations remain usable. |
Field-level comparisons, integrity checks, and successful post-update operations. |
| 2 |
Permissions |
Features respect the current operating-system authorization state. |
Correct behavior when access is granted, denied, restricted, or changed. |
| 3 |
Sessions |
Valid sessions continue where policy allows; invalid sessions fail safely. |
Correct account identity, token handling, reauthentication, and logout behavior. |
| 4 |
Deep links |
Existing links reach the intended authorized destination. |
Correct system routing, destination content, parameters, and navigation history. |
| 5 |
Rollback and recovery |
Failures can be contained and affected installations can recover. |
A rehearsed recovery path that preserves required data and security controls. |
How Do You Prepare a Realistic App Update Test?
Start with a genuine older installation, create representative user state, and install the candidate version over it without clearing that state. A structured mobile testing strategy provides the coverage framework this preparation depends on.
Choose Update Paths Based on Installation History
Build the matrix around the versions and data formats your release must support. Include the immediate predecessor, the oldest eligible source version, and releases that introduced significant persistence, authentication, or permission changes.
Test both direct jumps and sequential histories. An illustrative matrix might include 4.8 to 5.2 alongside 4.8 to 5.0 to 5.2. These version numbers are examples. Select actual paths from your installed-base data and support policy.
Record app version, database schema version, operating-system version, and Android target SDK separately. Do not combine an app update and an OS update in every test. First isolate each transition, then test important combinations. The existing mobile app upgrade testing guide covers additional scoping details that complement this approach.
Create Meaningful Pre-Update State
Use the older app to create drafts, saved settings, downloaded files, logged-in accounts, denied permissions, and queued offline operations. Supplement these scenarios with controlled historical database fixtures for edge cases. Behavior around offline and queued operations follows the patterns described in behavior testing for mobile apps.
Capture a baseline of expected record values, attachment identifiers, account identity, permission states, and pending operation IDs. Include empty datasets, large datasets, and unusual but valid text or date values.
Synthetic records created only through the newest model are useful for some tests, but they do not establish that a real older installation updates successfully.
Preserve the Installation During the Update
For a controlled Android APK test:
    adb install app-old.apk

    # Open the old app, create test data, sign in,
    # and set the required permission states.

    adb install -r app-new.apk
The -r option reinstalls the app while retaining its data. Do not insert an uninstall, pm clear, or blanket permission-grant step between the baseline and the update. Those actions change the conditions you are trying to validate.
Use compatible app identity and signing. In particular, distinguish Google Play’s app signing key from the upload key. They can be different. Include store-delivered testing rather than relying exclusively on locally signed builds.
For iOS, exercise the release candidate as an update through TestFlight or the intended distribution method. Test release builds on physical devices, including runs without an attached debugger. Apple notes that debugger behavior can mask watchdog terminations and alter background execution.
How Do You Validate Data Migration After an App Update?
Validate what the data means, not just whether the database opens. Define the expected transformation, compare the resulting records, and prove that interruption or retry does not silently lose or duplicate user work.
Check Records, Relationships, and Usable Files
For each migration, specify which information must remain unchanged and which changes are intentional.
Check identifiers, ownership, relationships, timestamps, text, numeric precision, and default values. A migration that splits one table into two may legitimately change row counts, so “the counts match” is not a sufficient universal rule.
Extend validation beyond the database. Open migrated attachments and downloads. Confirm that preferences still represent the user’s choices. Separate disposable caches from user-created or unsynchronized content before deciding what may safely be rebuilt.
For example, a draft migration should prove that each expected draft retains its content, author, attachment references, and editing capability. Not merely that a “Drafts” screen displays something.
Validate Pending Operations Before and After Synchronization
Seed offline edits and queued uploads in the old version. After updating, inspect them before reconnecting.
Then restore connectivity and verify that pending operations reach the correct account and resource, retain their intended ordering where required, and do not produce duplicate business actions.
Use stable operation identifiers to compare the local queue with server outcomes. Do not treat a successful network response as sufficient evidence that the correct operation was applied.
Use Migration Helpers Without Mistaking Them for Complete Validation
For Android Room, retain exported historical schemas and use MigrationTestHelper to exercise migration paths. Room’s documentation explicitly distinguishes schema validation from data validation. The helper verifies schema changes, but tests must separately check that data migrated correctly.
For SQLite-backed stores, PRAGMA integrity_check can detect structural and consistency problems. Foreign-key violations require PRAGMA foreign_key_check. Neither check proves that a transformed value is correct for your business rules.
Interrupt the Migration Deliberately
Run controlled failures before transformation, during processing, and around durable checkpoints. Exercise low storage, unavailable files, process termination, and repeated launches.
Require a defined outcome: safe completion, safe retry, or a recoverable error that preserves the original information. Make retry behavior idempotent. Repeating a completed step must not duplicate its effects.
For changes spanning databases, files, and preferences, test recovery across all stores. Do not accept a database transaction as evidence that separate file operations are also recoverable.
Finally, test entry points that might compete with initialization, such as notification handling or background work. For patterns on handling these lifecycle interruptions, refer to interruption testing in mobile applications.
Do not hide migration defects with destructive fallback. Room documents that destructive migration fallback can permanently delete table data when a migration path is missing. That may be acceptable for an explicitly disposable cache, but it is not a safe default for user-created content.
How Should Permissions Behave After a Mobile App Update?
The updated app should follow the operating system’s current authorization state, not a saved assumption that permission was granted previously. Android’s guidance requires checking permission whenever performing an operation that needs it and handling denial or revocation gracefully.
Test More Than Allow and Deny
Create separate pre-update cases for previously granted access, previously denied access, and permissions changed in system settings.
After updating, invoke the actual protected feature. A permission screen that looks correct is not enough. Attempt the camera capture, microphone use, or other relevant operation and verify both successful access and safe refusal.
Where the platform supports them, include temporary and partial authorization. Android supports one-time grants for certain permissions and mechanisms that reset unused permissions. Do not treat these as permanent grants.
On iOS, limited Photos access is a distinct state. Test access to the selected assets and verify the experience when an asset is outside the authorized selection, rather than assuming all-or-nothing library access. Runtime permission handling for automation is covered in the Patrol framework for enterprise Flutter testing.
Separate App Updates from OS Permission Transitions
Android notification permission illustrates why this distinction matters. When a device upgrades to Android 13 or higher, eligible existing apps can receive an automatic notification permission pre-grant. Eligibility includes an existing notification channel and the absence of a prior user-disabled notification state. This is not a blanket rule that every app update grants notification access.
Test relevant target-SDK transitions separately from ordinary app-version changes.
For newly introduced permission-dependent features, verify the timing and explanation of the request, the cancellation path, and continued access to unrelated functionality. Android recommends requesting permissions in context and degrading gracefully when access is denied.
Keep OS authorization separate from application preferences and consent settings. Your test should check each independently rather than using one as a substitute for the other.
How Do You Test Sessions and Secure Storage After an Update?
Preserve sessions that remain valid under the application’s security policy, and require reauthentication when continued access is no longer valid. Avoid defining success as “every user stays logged in.”
Exercise Valid, Expired, and Revoked Credentials
Create cases for a valid session, an expired access token with a usable refresh token, an expired or revoked refresh token, and a user who explicitly logged out before updating. Security testing for these token scenarios is detailed in the OWASP Mobile Security Testing Checklist.
OAuth’s security guidance recognizes refresh-token expiration, revocation, and rotation. Therefore, credential presence alone is not evidence that a session remains authorized.
For each case, verify the result at both the interface and server:
- A valid continuation should use the correct account and permissions.
- A failed continuation should show a controlled sign-in path rather than a retry loop.
- A logged-out user should not regain a session because an old local flag or cached screen survived.
Add account-switching tests. Confirm that cached content, queued operations, and restored navigation remain associated with the intended account.
The backend must enforce authentication and authorization. A protected-looking mobile screen is not the security boundary. OWASP MASVS makes remote enforcement explicit.
Stress Refresh and Retry Behavior
Trigger several authenticated requests immediately after the update, including a case where the access token expires at first launch.
Where refresh-token rotation is used, test coordination between requests and durable storage of the replacement credential. RFC 9700 describes rotation as issuing a new refresh token and invalidating the previous one, making stale-token reuse a meaningful failure case.
Also interrupt the app during refresh. Define when safe recovery requires reauthentication instead of repeatedly retrying credentials that may no longer be valid.
Test offline launch separately. Specify which cached content may remain accessible and ensure that a connectivity failure does not automatically become an invalid-credentials conclusion.
Read Credentials Created by the Old Version
On iOS, compare release entitlements and Keychain access groups, then attempt to read items written by the previous app. Apple documents that Keychain access depends on access-group membership, so testing only newly created credentials misses an important update condition.
Apply the same historical-data principle whenever encrypted storage formats, key aliases, or credential-storage libraries change. Include successful legacy reads and a controlled recovery path for unavailable credentials.
How Do You Validate Deep Links After a Mobile App Update?
Test both layers: whether the operating system routes the link correctly and whether the app reaches the intended authorized content. “The app opened” is only an intermediate result.
Verify the App-to-Domain Association
For Android App Links, inspect the device’s verification state and confirm the release configuration matches the intended domains. Android App Links provides commands to inspect and re-run domain verification.
For example, on a supported Android test device:
adb shell pm get-app-links --user cur com.example.app
Use this to inspect the existing state before changing it. Keep reset-and-reverification tests separate from tests of the state naturally inherited during an update.
For iOS Universal Links, verify both the website’s apple-app-site-association configuration and the app’s associated-domains entitlement. Apple defines these as the two sides of the app-to-website trust relationship.
Test Historical Links Through Real Entry Points
Maintain a set of links from previous releases: saved content links, email links, notification destinations, invitation links, and supported custom-scheme routes.
Open them from representative sources instead of exclusively invoking an internal navigation function. A test that forces a specific app component does not establish that normal system routing works.
For each supported link, assert the destination screen, resource identifier, relevant parameters, account context, and back-navigation behavior. Include renamed routes, unavailable content, malformed parameters, and unsupported paths.
Check the documented fallback when the app is not installed, while keeping that scenario separate from update testing.
Cover First Launch, Authentication, and Repeated Delivery
Make an old link the first entry into the updated app. Verify that routing waits for any required migration and session initialization rather than reading partially prepared state.
Repeat link tests after the app has launched successfully, both while it is running and after termination.
When login is required, retain the intended destination and validate it again after authentication. Test cancellation, switching accounts, and receiving the same link more than once.
A link must not bypass resource authorization. Verify server-side access checks even when the route and resource identifier are valid.
How Do You Validate Rollback and Recovery Paths?
Test recovery on installations that have not migrated, have partially migrated, and have completed migration. Treat stopping distribution, disabling a feature, restoring data, and replacing the installed binary as different operations.
Understand What Rollout Controls Actually Do
On Google Play, halting a staged rollout prevents additional users from receiving that version, but users who already received it remain on it.
Google Play also supports halting eligible fully rolled-out releases, allowing a previous eligible release to become available to users who are not on the halted version. This should not be treated as reversing migrations on already-updated devices.
Apple’s phased release controls automatic distribution. Users can still manually download a phased update, so pausing the phase is not equivalent to making the update unavailable or repairing affected installations.
Rehearse the Recovery Mechanism You Actually Have
| S. No |
Recovery mechanism |
What the test must prove |
| 1 |
Feature disablement |
The app can reach the control, apply it safely, and behave acceptably with cached or unavailable configuration. |
| 2 |
Backend reversion |
Both older and updated clients still receive compatible responses and can submit valid operations. |
| 3 |
Local checkpoint or backup restoration |
Restoration produces consistent state and accounts for user changes made after the checkpoint. |
| 4 |
Forward-fix release |
The fix handles untouched, fully migrated, and partially migrated installations without requiring a reset. |
| 5 |
Binary downgrade, where supported |
The actual distribution method allows it, and the older code can safely handle the resulting local state. |
A lab downgrade is not sufficient evidence of a production recovery path. Test the delivery mechanism and the data compatibility, not just whether a tool can install an older package.
Protect Writes Created After the Update
Suppose an update migrates a store successfully and the user then creates several offline drafts. Restoring a pre-update snapshot without reconciling those drafts would discard them.
Include that sequence in recovery testing. Establish which changes must survive, how they will be retained or replayed, and how conflicts will be resolved.
Also test a crash that happens before remote configuration loads. A remote feature switch is useful only if the affected installation can reach the code that reads and applies it.
Document the recovery trigger, responsible owner, compatible versions, verification steps, and acceptable data-loss policy. “Ask the user to reinstall” should not count as successful recovery when required local work would be lost.
The release readiness framework in the mobile app launch checklist provides go/no-go criteria that apply directly to update releases, including rollback readiness and defect thresholds.
What Should You Automate, and What Should Block Release?
Automate state preservation and outcome checks, not merely installation commands.
Use persistence-level tests for historical fixtures and transformation rules. Add device-level tests that install an old build, create state, update in place, and inspect the result. Finally, exercise complete user journeys against the appropriate backend configuration.
Audit the test harness itself. Confirm that setup hooks are not uninstalling the app, clearing storage, resetting permissions, or signing in again before assertions run.
An illustrative end-to-end case is to create an offline draft in an older version, deny a relevant permission, save a legacy content link, and then update. Check the draft before synchronization, open the saved link, validate account identity, and complete the pending operation after reconnecting. Repeat from the same baseline in separate interruption and recovery runs.
A practical release gate should require:
| S. No |
Gate |
Requirement |
| 1 |
Correctness |
No known unexplained loss, duplication, account crossover, or permission bypass in the required update paths. |
| 2 |
Recoverability |
The selected recovery mechanisms have been exercised against realistic post-update state. |
| 3 |
Observability |
Failures can be identified by source version, target version, schema, OS, and relevant configuration. |
Track migration starts, completions, failures, and unresolved attempts. Monitor first-launch failures, unexpected reauthentication, link-to-destination failures, and recovery outcomes. Do not count missing completion events as success.
Set performance thresholds against your application’s baseline and supported devices rather than adopting an arbitrary universal number. Performance validation patterns for mobile releases are covered in Android and iOS quality assurance.
Keep diagnostic evidence free of passwords, tokens, and sensitive payloads. OWASP specifically identifies logs and backups as possible sources of unintended sensitive-data exposure.
For teams that need expert support building this layer, Codoid’s QA automation services integrate update testing into release pipelines.
The Final Standard: Continuity Without Compromising Safety
A mobile app update should preserve more than the ability to launch. It should preserve the user’s work, respect current access decisions, maintain the correct identity, and honor existing navigation paths. Approve the release only when those outcomes, and the recovery path when they fail, have been demonstrated on realistic existing installations.
Frequently Asked Questions
-
Is update testing the same as regression testing?
No. Regression testing checks whether existing behavior still works. Update testing adds a specific transition: new code must handle state created by an older installation. Fresh-install regression tests do not reproduce that history. Apple recommends testing the update scenario when a release must support prior app data.
-
How many previous app versions should be tested?
Base coverage on eligible source versions, active installation history, and distinct data formats. Prioritize the immediate predecessor, the oldest supported path, and versions crossing significant migration or authentication changes. Testing only the last two releases should be a justified decision, not an automatic rule.
-
Is backup-and-restore testing the same as an in-place update?
No. Treat it as a separate scenario. Android documents restoration during installation, including device setup and supported reinstall flows. That can introduce historical data through a different path from updating an existing installation. Test the restored state explicitly.
-
Does stopping a rollout fix users who already updated?
No. Google Play explicitly states that users who already received a halted staged release remain on that version. Affected installations need a separate mitigation or recovery path, such as compatible server behavior, feature disablement, or a tested corrective release.
-
Why can fresh-install testing not replace update testing?
A fresh installation has no prior data, no stored credentials, no historical permissions, and no navigation history. Update testing specifically validates how new code handles the state left behind by an older version. Apple's release-testing guidance identifies data migration, Keychain access, and stored preferences as conditions that only appear during an update, which is why fresh-install regression suites miss them entirely.
-
What should I test first when planning an update test cycle?
Start with data migration for the immediate predecessor version. Data loss is the most damaging and least reversible failure mode. Once migration is verified, move to permissions, sessions, deep links, and finally rollback and recovery paths. This order reflects the severity of impact if something fails in production.
-
How do I test permission changes after an app update?
Create separate pre-update test cases for previously granted access, previously denied access, and permissions modified in system settings. After updating, invoke the actual protected feature, not just the permission prompt. Verify both successful access and safe refusal. Where the platform supports it, include temporary and partial authorization states, since Android one-time grants and iOS limited Photos access are distinct from permanent approval.
-
How do I test sessions after a mobile app update?
Build separate cases for a valid session, an expired access token with a usable refresh token, an expired or revoked refresh token, and a user who explicitly logged out before updating. Credential presence alone is not evidence that a session remains authorized. Verify the result at both the interface and the server. A valid continuation should use the correct account, a failed continuation should show a controlled sign-in path, and a logged-out user should not regain a session from a stale local flag.
-
by Rajesh K | Oct 1, 2026 | Automation Testing, Blog, Latest Post |
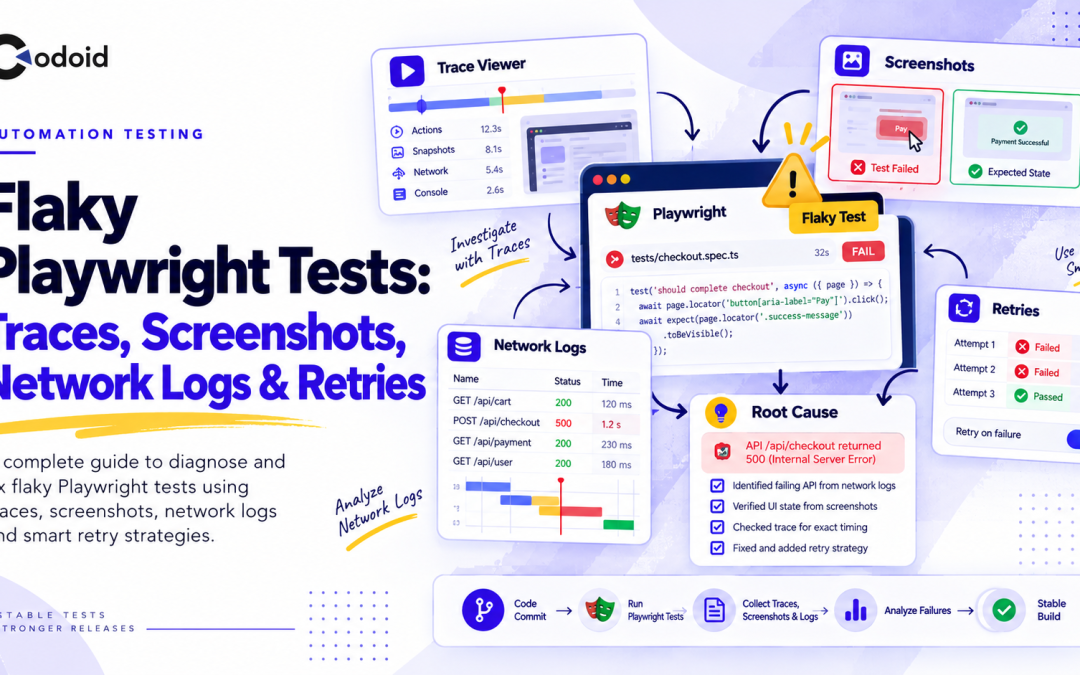
A Playwright test that fails once and passes immediately afterward is more dangerous than it looks. The retry may turn the pipeline green, but it does not explain whether the original failure came from a race condition, unstable test data, an API error, an overlay blocking a click, resource contention, or an actual application defect. The goal of debugging flaky Playwright tests is therefore not simply to make the next execution pass. It is to preserve enough evidence from the failing attempt to determine why the outcome changed.
Playwright provides several complementary debugging signals: traces, screenshots, browser and test logs, network activity, HTML reports, and retries. Used together, they can make intermittent failures reproducible and diagnosable. Used carelessly, particularly retries, they can also conceal instability. This guide uses the current Playwright 1.63-era feature set. Version 1.63 added the retain-on-failure-and-retries trace mode specifically to make comparison between failed and retried executions easier.
Codoid’s QA automation services help teams build reliable Playwright suites that surface instability early instead of hiding it behind retries.
TABLE OF CONTENTS (INTERNAL NAVIGATION)
How Should You Debug Flaky Playwright Tests?
To debug flaky Playwright tests without hiding failures, capture evidence from the original failure, compare it with the retry, and keep the initial failure visible to CI. Use Trace Viewer for execution history and DOM state, screenshots for visual checkpoints, network logs for API and transport failures, and only a small number of retries for additional diagnostic evidence.
For CI quality gates, Playwright’s failOnFlakyTests option is particularly important: a test that fails initially but succeeds on retry can still make the run fail instead of silently becoming a successful build.
Key Takeaways
- Treat retries as diagnostic observations, not as a fix for flaky Playwright tests.
- Use Trace Viewer as the primary CI debugging artifact because it combines actions, DOM snapshots, console output, errors, and network activity.
- Keep
screenshot: 'only-on-failure' for a lightweight visual record, and add named screenshots only around high-risk transitions when necessary.
- Inspect both HTTP error responses and transport failures; a
500 response does not trigger Playwright’s requestfailed event.
- Preserve both failed and retry traces when actively investigating intermittent failures.
- Use
failOnFlakyTests or --fail-on-flaky-tests when a pass-on-retry must not turn an unstable release gate green.
- Before adding waits or more retries, check locators, auto-waiting, test isolation, shared state, network dependencies, and parallel execution.
What Is a Flaky Playwright Test?
A flaky Playwright test is a test whose outcome changes between executions even though the intended application behavior and test inputs have not deliberately changed.
Playwright Test formally categorizes a test as flaky when it fails on its first execution but passes on a retry. A test that passes initially is categorized as passed; one that exhausts its retries without passing is failed.
That distinction is useful, but not every intermittent failure is necessarily a bug in the test itself.
A flaky result may expose:
- A race condition in the application
- Unstable or eventually consistent backend data
- Network or dependency failures
- Shared test-account interference
- Differences between CI and local environments
- Brittle selectors
- Missing asynchronous assertions
- Resource pressure under parallel execution
- A real product defect that occurs only under specific timing conditions
A consistently reproducible failure is different. If the same input fails every time for the same reason, it is a deterministic failure rather than a flake.
The debugging objective for flaky Playwright tests is to determine which variable changed between the failing and passing executions.
Why Flaky Playwright Tests Matter
flaky Playwright tests reduce the value of automation because developers stop being able to interpret a failing pipeline as a meaningful signal.
The common response, “rerun it,” creates a more serious problem. A defect may remain present while the second execution happens to avoid the conditions that exposed it.
Retries can make this especially misleading. When Playwright retries a failed test, it does not simply continue inside the same broken browser. Following a failure, Playwright shuts down the worker process and starts another worker with a new browser before performing the retry.
That reset is useful for isolation, but it also means:
A passing retry proves that the test passed in a fresh execution environment. It does not prove that the original failure was harmless.
For example, if the first run fails because two parallel tests modify the same customer account, the new worker may retry after the conflicting test has finished. The retry passes, but the underlying concurrency defect remains.
How Flaky Test Debugging Works
A useful debugging workflow correlates four types of evidence rather than relying on one artifact in isolation:
- Trace: What actions occurred, what Playwright waited for, and what the DOM looked like around the failure?
- Screenshot: What did the rendered page visibly look like at a specific moment?
- Network evidence: Did the expected request happen, what HTTP status was returned, and did transport fail?
- Retry comparison: Did the same action succeed after the worker and browser were reset?
The sequence is important.
A failed screenshot may show a spinner. The trace can reveal which action was waiting behind that spinner. The Network tab can reveal that /api/orders returned 503. A passing retry can then show the same endpoint returning 201.
That evidence points toward a very different root cause than simply increasing a locator timeout.
Step-by-Step: Configure Playwright to Preserve Evidence
1. Keep Retries Small and Make Flaky Tests Visible in CI
A practical starting configuration is:
    // playwright.config.ts
    import { defineConfig } from '@playwright/test';

    const flakeDebug = process.env.FLAKE_DEBUG === '1';

    export default defineConfig({
      retries: process.env.CI ? 1 : 0,

      // A fail-then-pass result still fails the CI run.
      failOnFlakyTests: !!process.env.CI,

      reporter: [
        ['html', { open: 'never' }],
        ['list'],
      ],

      use: {
        screenshot: 'only-on-failure',

        trace: flakeDebug
          ? 'retain-on-failure-and-retries'
          : 'on-first-retry',
      },
    });
Playwright recommends on-first-retry for routine CI tracing rather than recording every test because tracing every execution has a performance cost. Playwright 1.63 additionally provides retain-on-failure-and-retries, which keeps relevant executions so a failing attempt can be compared with its retry.
This gives two useful operating modes:
- Normal CI: low-overhead trace collection on the first retry.
- Flake investigation: preserve failed and retried executions for comparison.
The important setting is failOnFlakyTests. Without it, a failing attempt that later passes can leave the overall run successful. Playwright also exposes the equivalent --fail-on-flaky-tests command-line option.
2. Reproduce the Problem Before Modifying the Test
Avoid immediately adding another timeout or retry. First establish how frequently and under which execution conditions the problem appears.
For example:
FLAKE_DEBUG=1 npx playwright test tests/checkout.spec.ts --repeat-each=20
--repeat-each executes the selected test repeatedly and is useful for exposing intermittent timing problems.
Then compare the result with single-worker execution:
    FLAKE_DEBUG=1 npx playwright test tests/checkout.spec.ts \
      --repeat-each=20 \
      --workers=1
Playwright supports --workers=1 specifically to disable parallel execution.
This comparison provides an immediate clue:
- Flaky with normal parallelism but stable with one worker: investigate shared accounts, data, ports, databases, rate limits, or other shared resources.
- Flaky in both modes: focus more strongly on application timing, network dependencies, selectors, assertions, or environment differences.
Twenty executions here are a diagnostic sample, not proof that the problem is permanently fixed if all twenty pass.
3. Open the Failing Trace Before Editing the Test
Use:
npx playwright show-trace path/to/trace.zip
or open the trace from Playwright’s HTML report.
Trace Viewer provides considerably more context than a screenshot. It can show:
- Actions and their duration
- Before, action, and after DOM snapshots
- The locator used
- Playwright’s action log
- The source line
- Test errors
- Browser and test console messages
- Network requests and responses
- Attachments
- Browser and execution metadata
The timeline can also filter console and network information to the period surrounding a particular action.
Start at the failed action and work backward.
For a failed click, ask:
- Did the locator resolve to the intended element?
- Was the element stable?
- Was it enabled?
- Was another element intercepting pointer events?
- Did navigation or rendering occur immediately before the failure?
- Was the expected API response already delayed or failing?
Playwright automatically checks actionability conditions such as visibility, stability, event reception, and enabled state before actions such as locator.click(). A timeout can therefore mean more than “the element was not found.”
4. Use Screenshots as State Evidence, Not as Your Complete Debugger
Enable automatic failure screenshots:
    use: {
      screenshot: 'only-on-failure',
    }
Playwright supports off, on, and only-on-failure screenshot modes, with artifacts normally stored in the configured test output directory.
A failure screenshot is useful for immediately spotting:
- Cookie banners
- Modal overlays
- Validation messages
- Logged-out sessions
- Loading indicators
- Wrong routes
- Unexpected empty states
- Layout differences
Its limitation is causality.
A screenshot tells you what the page looked like at one instant. It usually cannot tell you why it reached that state.
For a known flaky transition, attach a named checkpoint:
    import { test, expect } from '@playwright/test';

    test('places an order', async ({ page }) => {
      await page.goto('/checkout');

      await test.step('submit order', async step => {
        const screenshot = await page.screenshot({ fullPage: true });

        await step.attach('before-submit', {
          body: screenshot,
          contentType: 'image/png',
        });

        await page.getByRole('button', {
          name: 'Place order',
        }).click();
      });

      await expect(
        page.getByRole('heading', { name: /thank you/i })
      ).toBeVisible();
    });
Playwright can attach files or buffers to tests and individual test steps, allowing the evidence to appear in supporting reports.
Do this selectively. Capturing screenshots after every action creates noise and artifact overhead while Trace Viewer already records a visual timeline when tracing is enabled.
5. Inspect Network Behavior Instead of Guessing About Backend Timing
A UI failure may actually be a network failure.
Trace Viewer’s Network tab displays requests made during the test and exposes information including method, status, duration, headers, request bodies, and response bodies. Network activity can also be filtered to the actions selected in the trace timeline.
For important transitions, make the backend dependency explicit:
    const orderResponse = page.waitForResponse(response =>
      response.url().endsWith('/api/orders') &&
      response.request().method() === 'POST'
    );

    await page
      .getByRole('button', { name: 'Place order' })
      .click();

    const response = await orderResponse;

    expect(response.status()).toBe(201);

    await expect(
      page.getByRole('heading', { name: /thank you/i })
    ).toBeVisible();
Notice that waitForResponse() is registered before clicking the button. This prevents the test from missing a fast response that occurs immediately after the click. Playwright’s network documentation uses the same promise-before-action pattern.
You can also add targeted logging during an investigation:
    page.on('requestfailed', request => {
      console.error(
        '[transport failure]',
        request.method(),
        request.url(),
        request.failure()?.errorText
      );
    });

    page.on('response', response => {
      if (response.status() >= 500) {
        console.error(
          '[server error]',
          response.status(),
          response.url()
        );
      }
    });
The second listener matters because requestfailed does not mean “the server returned an error status.”
Playwright considers responses such as 404 and 503 successfully completed HTTP requests. requestfailed is emitted when the browser fails to obtain a response because of a transport-level problem such as a network error or timeout.
Without this distinction, an engineer may search for requestfailed events and incorrectly conclude that the network was healthy even though the application received a 500.
6. Compare the Failed Attempt with the Retry
The highest-value question is often not “why did this fail?” but:
What is different between the failed trace and the passing trace?
Compare:
| S. No |
Signal |
Failed attempt |
Passing retry |
| 1 |
Locator |
Same target? |
Same target? |
| 2 |
DOM |
Overlay, stale state, missing data? |
Expected state present? |
| 3 |
Action duration |
Near timeout? |
Immediate? |
| 4 |
API status |
4xx or 5xx? |
Expected 2xx? |
| 5 |
Request timing |
Slow or absent? |
Normal? |
| 6 |
Console |
JavaScript error? |
No error? |
| 7 |
Authentication |
Session expired? |
Fresh session? |
| 8 |
Test data |
Conflicting record? |
Available record? |
| 9 |
Parallel activity |
Competing test? |
Conflict gone? |
Playwright 1.63‘s retain-on-failure-and-retries mode is particularly useful here because it was designed to retain traces that allow failed and retry executions to be compared.
7. Fix the Synchronization or Isolation Problem, Not the Symptom
Suppose the trace shows:
    const text = await page.locator('.status').textContent();
    expect(text).toBe('Complete');
If .status changes asynchronously, this assertion observes one instant in time.
Prefer:
    await expect(
      page.locator('.status')
    ).toHaveText('Complete');
Playwright’s web-first assertions automatically retry until their condition succeeds or the assertion timeout expires. Playwright explicitly warns that non-retrying assertions against asynchronously changing pages can create flaky Playwright tests.
Likewise, avoid:
await page.waitForTimeout(3000);
followed by an assumption that three seconds must be enough.
Wait for the actual application condition instead:
    await expect(
      page.getByRole('button', { name: 'Continue' })
    ).toBeEnabled();
or, when a backend response is the true synchronization boundary:
    const responsePromise = page.waitForResponse('**/api/profile');

    await page
      .getByRole('button', { name: 'Save' })
      .click();

    await responsePromise;
The test becomes resilient to reasonable timing variation without concealing a real timeout when the expected condition never occurs.
Practical Example: Debugging an Intermittent Checkout Failure
Consider this CI failure:
    TimeoutError: locator.click: Timeout 30000ms exceeded
    Locator: getByRole('button', { name: 'Place order' })
The retry passes.
A tempting change is:
    await page
      .getByRole('button', { name: 'Place order' })
      .click({ timeout: 60000 });
That increases tolerance but provides no evidence that thirty seconds was actually the problem.
A better investigation follows the evidence.
Preconditions
The checkout test:
- Creates a cart
- Loads
/checkout
- Fills payment details
- Clicks Place order
- Expects a confirmation page
Evidence From the Failed Trace
Imagine the trace shows:
- The button exists and is visible
- A loading overlay appears above it
- Playwright repeatedly reports that another element receives pointer events
/api/shipping/quote takes unusually long- The request eventually returns
503
- The application does not remove the loading overlay
The screenshot merely shows a spinner.
The network evidence explains why it remained there.
The action log explains why Playwright correctly refused to click the button.
The passing retry then shows:
/api/shipping/quote returning 200- The overlay disappearing
- The button becoming actionable
- The click completing immediately
The root cause is therefore not “Playwright cannot click the button.” The test exposed an application and dependency path in which a failed shipping request leaves checkout blocked.
Increasing the click timeout would have hidden the useful symptom while leaving the underlying behavior unchanged.
Traces vs Screenshots vs Network Logs vs Retries
| S. No |
Debugging signal |
Best question it answers |
Main advantage |
Main limitation |
Recommended use |
| 1 |
Trace |
What sequence of events caused the failure? |
Combines actions, DOM snapshots, logs, source, network data, and errors |
More artifact and storage overhead |
Primary CI debugging evidence |
| 2 |
Screenshot |
What did the user-visible page look like? |
Fast visual diagnosis |
No execution history or causality |
Automatic on failure; targeted checkpoints when needed |
| 3 |
Network logs |
Did an API request fail, stall, or return unexpected data? |
Reveals backend and transport problems |
Does not explain every DOM or actionability problem |
Inspect Trace Network tab and log critical endpoints |
| 4 |
Retry |
Does the behavior change in a fresh execution? |
Supplies a second observation |
Can hide failures if treated as success |
Keep count low and report flakes explicitly |
The tools answer different questions. A reliable debugging process correlates them rather than selecting one as a universal solution.
Best Practices for Debugging Flaky Playwright Tests
Make Pass-on-Retry Visible to the Pipeline
Use:
failOnFlakyTests: !!process.env.CI
for quality gates where intermittent failures require investigation.
A retry can still collect useful evidence without allowing the build to appear stable.
Preserve the First Meaningful Failure
on-first-retry is efficient for general CI debugging, but when actively investigating a flake, preserving the failed execution itself is valuable.
On current Playwright versions, use:
trace: 'retain-on-failure-and-retries'
when comparing failed and retried attempts is worth the additional artifact cost.
Prefer State-Based Synchronization
Use locators, auto-waiting actions, web-first assertions, and explicit network expectations instead of arbitrary sleeps.
Playwright performs actionability checks automatically and provides retrying assertions specifically for asynchronous browser behavior.
Test Parallelism as a Diagnostic Variable
If a problem disappears with:
npx playwright test --workers=1
investigate shared server-side state rather than leaving the whole suite permanently serialized.
Playwright recommends isolated tests, and parallel workers should not depend on shared in-memory state. Teams that need help structuring this layer can benefit from reusable Playwright fixtures that isolate resources per worker.
Give Parallel Tests Independent Data
Separate test users, carts, organizations, records, and temporary resources where tests modify server-side state.
Playwright’s authentication guidance specifically recommends separate accounts per parallel worker for scenarios that modify shared server-side state.
Use Test Locks Only for Genuinely Shared Resources
Playwright 1.63 introduced named test locks. Tests sharing a lock do not execute concurrently, which can be useful for a truly exclusive external resource.
For example:
    test(
      'updates global billing settings',
      { lock: 'billing-settings' },
      async ({ page }) => {
        // ...
      }
    );
Do not use locks as a blanket solution for poorly isolated tests. Separate test data remains preferable when the system allows it.
Track First-Attempt Failures, Not Only Final Failures
Your flake metrics should distinguish:
- First-attempt pass
- Fail then pass
- Fail after all attempts
Otherwise, adding retries can improve the reported pass rate while actual test stability gets worse.
Common Mistakes When Debugging Flaky Playwright Tests
| S. No |
Mistake |
Why it happens |
Impact |
Recommended fix |
| 1 |
Increasing retries until CI becomes green |
Retry appears cheaper than investigation |
Instability becomes normalized |
Keep retries limited and fail CI on flaky results where appropriate |
| 2 |
Adding waitForTimeout() |
Failure looks timing-related |
Makes tests slower without proving readiness |
Wait for observable UI or network state |
| 3 |
Looking only at screenshots |
Screenshot is easy to inspect |
Root cause remains unknown |
Correlate screenshot with trace and network activity |
| 4 |
Treating every requestfailed absence as network success |
Event name is misleading |
HTTP 4xx and 5xx failures are missed |
Inspect response statuses as well |
| 5 |
Recording traces for every test |
Maximum evidence seems safer |
Increased runtime and storage indefinitely |
Use targeted trace modes |
| 6 |
Using force: true to bypass |
Click is blocked intermittently |
Can hide a real overlay or UI bug |
Determine why the element cannot receive events |
| 7 |
Sharing one mutable test account across workers |
Setup is simpler |
Cross-test interference |
Use independent resources or deliberate locking |
| 8 |
Raising global timeouts |
Slow CI causes failures |
Real performance and synchronization problems become harder to detect |
Increase only the timeout that has a justified requirement |
| 9 |
Assuming a passing retry proves the test is healthy |
Final result is green |
Initial failure is discarded |
Treat pass-on-retry as a distinct flaky state |
Troubleshooting Common Flake Patterns
Why does my Playwright test pass locally but fail in CI?
Start by comparing environment and execution conditions rather than increasing timeouts.
CI may have different CPU availability, browser versions, worker counts, network latency, authentication state, environment variables, or test data. Run the failing test repeatedly, preserve its trace, then compare normal parallel execution with --workers=1.
If the single-worker run is stable, shared state or resource contention becomes a stronger hypothesis. If both fail, inspect the trace for synchronization, network, and actionability differences.
Why is locator.click() timing out when the button is visible?
Visibility is only one of Playwright’s actionability checks.
For a normal click, Playwright also checks that the element is stable, receives pointer events, and is enabled. An overlay can therefore leave a button visibly present while preventing the click.
Open the failing trace and inspect its action log before using force: true.
Why does the retry pass when the first attempt failed?
The retry occurs after Playwright restarts the failed worker and its browser.
A fresh worker can remove several conditions that existed during the original run:
- Stale browser state
- Worker-scoped setup state
- Timing overlap with another test
- Temporary dependency failure
- Shared-data conflict
Compare the first failure and retry rather than treating the retry as proof that the original error can be ignored.
Why do I see an HTTP 500 but no requestfailed event?
Because an HTTP 500 is still an HTTP response.
Playwright emits requestfailed when the browser cannot obtain an HTTP response, for example because of a network-level failure. Error statuses such as 404 and 503 still complete as HTTP requests.
Monitor response status codes separately:
    page.on('response', response => {
      if (response.status() >= 400) {
        console.log(response.status(), response.url());
      }
    });
Why is a flaky test stable with –workers=1?
The test may depend on a resource another worker can modify concurrently.
Common examples include:
- One shared user account
- A fixed database record
- The same shopping cart
- A global configuration setting
- Rate-limited test credentials
- Shared file paths
- External systems that permit only one active operation
Use independent test resources where possible. If the resource is inherently exclusive, limit concurrency only around that resource rather than serializing unrelated tests.
Why does increasing the timeout make the flake disappear?
Because the test is being given more time, not necessarily because the synchronization problem has been fixed.
Inspect what consumed the additional time. If the application legitimately needs longer under a documented condition, a targeted timeout may be correct. If the timeout merely gives an uncertain race more opportunities to succeed, replace it with an observable readiness condition.
Playwright Tools for Flaky Test Investigation
Trace Viewer
Best for post-failure CI diagnosis.
npx playwright show-trace trace.zip
Trace Viewer exposes actions, DOM snapshots, logs, console events, network requests, errors, attachments, source locations, and execution metadata. Playwright recommends traces over standalone videos and screenshots for CI debugging.
The hosted Trace Viewer at trace.playwright.dev processes uploaded traces in the browser rather than transmitting their contents externally.
HTML Report
Use:
npx playwright show-report
The HTML report allows tests to be filtered by states including passed, failed, skipped, and flaky, then opened for detailed errors, steps, and attached artifacts. For a deeper walkthrough, see Codoid’s test reports guide.
UI Mode
Use:
UI Mode is useful while reproducing a problem locally and automatically provides tracing for interactive debugging.
Playwright Inspector
Use:
npx playwright test tests/example.spec.ts --debug
Playwright Inspector is useful when the problem can be reproduced locally and you need to step through actions or inspect locators.
–repeat-each
Use:
npx playwright test flaky.spec.ts --repeat-each=20
Repeated execution helps turn an intermittent failure into observable evidence. Avoid interpreting a small number of successful repeats as proof of long-term stability.
retryStrategy: ‘isolated’
Current Playwright versions also support:
    export default defineConfig({
      retries: 1,
      retryStrategy: 'isolated',
    });
With the isolated strategy, retries run after other tests have finished and are executed one by one in a single worker, reducing interference between retries and the rest of the suite. Playwright documents this as an alternative to the default immediate retry strategy.
This can be a useful diagnostic tool for concurrency-related flakes, but it should not become a substitute for fixing shared-state problems.
Limitations and Risks
Traces Can Contain Sensitive Information
Trace Viewer’s Network tab can expose request headers, response headers, request payloads, and response bodies.
Treat trace archives as potentially sensitive CI artifacts. Apply suitable access controls and retention policies, particularly when test systems use real-looking credentials, tokens, customer-like data, or internal APIs.
More Artifacts Create Runtime and Storage Costs
Recording every trace, video, and screenshot from every successful test can be expensive on large suites. Capture detailed artifacts conditionally instead of assuming maximum recording is always desirable.
Retries Change Execution Conditions
Because failed workers are replaced, a retry does not reproduce the original environment perfectly. It is a new observation.
This is why the failing attempt itself is often the most valuable artifact.
A Network Trace Does Not Explain Every Backend Problem
Browser-level network evidence can show what the browser sent and received. It cannot show an internal queue, database lock, service-to-service request, or backend exception that was never returned to the browser.
Correlate browser traces with server logs or distributed tracing when necessary.
A Test Can Expose a Product Flake Rather Than a Test Flake
Do not assume intermittent behavior belongs to automation code.
If the trace proves that the application sometimes leaves an overlay visible, returns inconsistent data, or fails an API request, the automated test may be accurately detecting nondeterministic product behavior.
Conclusion
Effective debugging of flaky Playwright tests is an evidence problem, not a retry-count problem. Use Trace Viewer to reconstruct the failing sequence, screenshots to understand visual state, and network evidence to identify backend or transport failures. Then compare the first failure with the retry to determine which condition changed.
Retries remain useful when they provide another observation. They become harmful when they erase the significance of the first one. A strong CI strategy therefore does both: retain enough evidence to diagnose the failure and keep fail-then-pass tests visible as flaky. With failOnFlakyTests, targeted tracing, web-first assertions, explicit network synchronization, isolated test data, and controlled parallelism, Playwright retries can help investigate instability without converting instability into a false green build.
Codoid’s QA automation services help teams design Playwright suites that surface flakes early, preserve the right evidence, and keep release gates meaningful.
Frequently Asked Questions
-
Should I enable trace: 'on' for every Playwright test?
Usually not for routine CI. Playwright warns that tracing every execution is performance-heavy and recommends on-first-retry for CI debugging. During an active flake investigation, retain-on-failure-and-retries can provide more useful failed-versus-passing comparisons.
-
How many retries should a Playwright test have?
Use the smallest number that serves your diagnostic or resilience policy. A single retry often provides the critical second observation without repeatedly rerunning an unstable test. More retries increase runtime and increase the chance that intermittent instability becomes visually buried. Whatever count you select, report fail-then-pass executions separately from first-attempt passes.
-
Can Playwright fail CI when a test passes on retry?
Yes. Configure failOnFlakyTests: true or run npx playwright test --fail-on-flaky-tests. Playwright will then return an error when a test is classified as flaky instead of allowing recovered failures to behave like an entirely successful run.
-
Are screenshots enough for debugging Playwright CI failures?
No. Screenshots are excellent state evidence, but they do not show the chain of events leading to the state. Trace Viewer is more complete because it combines screenshots and DOM snapshots with actions, logs, errors, source code, console messages, and network activity.
-
Should I use force: true when a Playwright click is flaky?
Only when bypassing the normal actionability behavior is genuinely part of the intended test. A forced click can suppress checks that would otherwise reveal that an overlay or another element is intercepting user interaction. Inspect the trace first and determine why the target cannot receive the event.
-
How can I tell whether parallel execution causes the flake?
Repeat the test under its normal execution conditions, then repeat it with --workers=1. If failures reliably occur only with multiple workers, investigate shared external state, resource limits, or test-data collisions. Playwright provides single-worker execution specifically for disabling parallelism during this type of diagnosis.
by Rajesh K | Sep 30, 2026 | Accessibility Testing, Blog, Latest Post |
Single-page applications (SPAs) can deliver fast, app-like experiences, but they also change some of the assumptions built into traditional web accessibility testing. Navigation may occur without a full page reload. Components appear and disappear asynchronously. Focus can remain on elements that no longer exist. Visual updates may happen without being announced to assistive technologies. As a result, testing only the initial DOM, or running an automated accessibility scan once after page load, is not sufficient. Single-page application accessibility has to validate what happens between application states, not just what exists in each state.
This guide covers how to test SPAs for keyboard navigation, focus management, dynamic content, and ARIA updates. It combines WCAG 2.2 requirements with practical testing techniques, real tooling examples, and a state-transition matrix that turns vague accessibility review into a repeatable test method.
Codoid’s accessibility testing services apply these same principles to help teams validate SPAs against WCAG 2.2 and real assistive technology.
How Should Accessibility Testing Be Performed for a Single-Page Application?
Single-page application accessibility testing should validate every important UI state transition for four things: keyboard operability, predictable focus, programmatically exposed state changes, and appropriate announcements of dynamic content. Tests should combine keyboard-only and screen-reader testing with automated checks performed after routes, dialogs, filters, validation messages, and other dynamic states have changed.
WCAG 2.2 provides the core requirements: functionality must be keyboard operable, focus order must preserve meaning and operation, focus must remain visible, component names and states must be programmatically available, and status messages must be exposed to assistive technology without unnecessarily taking focus.
Key Takeaways
- Test state transitions, not only routes or static DOM snapshots.
- Complete every critical workflow using only the keyboard and verify both focus order and focus visibility.
- Move focus deliberately when an SPA transition behaves like navigation, but avoid stealing focus for ordinary in-place updates.
- Use ARIA states such as
aria-expanded, aria-selected, and aria-invalid to expose control state; use live regions only when an announcement is actually required.
- Test dynamic status messages with real assistive technology because a correct DOM does not guarantee the expected spoken experience.
- Run automated accessibility checks after important components and states become visible, then supplement them with manual testing.
What Is Single-Page Application Accessibility?
Single-page application accessibility is the process of verifying that users can perceive, understand, navigate, and operate an application as JavaScript changes its interface without traditional full-page navigation.
It includes testing:
- Client-side route changes
- Keyboard navigation and custom widgets
- Programmatic focus movement
- Modals, menus, drawers, tabs, and disclosures
- Loading indicators and progress updates
- Search and filter results
- Form validation
- Toasts and notifications
- ARIA roles, names, properties, and states
- Live-region announcements
- Browser history navigation
- Content added, removed, reordered, or replaced asynchronously
The key difference is timing. A server-rendered page can often be evaluated after it finishes loading. An SPA may expose dozens of materially different accessibility states from the same document. This is why SPA accessibility testing requires a transition-based approach rather than a static one.
WCAG explicitly addresses one SPA-specific consequence under Success Criterion 2.4.2: when distinct SPA views change dynamically, the document title should also change to describe the current view.
Why Is SPA Accessibility Testing Different from Conventional Page Testing?
An SPA frequently preserves the browser document while replacing substantial portions of its contents. That can create a mismatch between what sighted users perceive and what keyboard or assistive-technology users experience.
For example, selecting an Orders navigation link might visually replace a dashboard with an Orders screen. A sighted user immediately sees the new heading. But if keyboard focus remains on the now-removed navigation link, or falls back to the document body, a screen-reader user may receive little useful indication that navigation succeeded.
The same issue occurs at smaller scales:
- A search result count changes without being announced.
- A button visually changes from collapsed to expanded while
aria-expanded remains false.
- A modal appears, but focus stays behind it.
- A modal closes, but focus does not return to a logical control.
- A sticky notification covers the currently focused button.
- A custom menu responds to clicks but has no keyboard interaction model.
- A validation error appears next to a field but is absent from the accessibility tree.
WCAG 2.2 requires keyboard operability under SC 2.1.1, logical sequential focus under SC 2.4.3, visible focus under SC 2.4.7, and, for Level AA, requires a focused component not to be completely obscured by author-created content under SC 2.4.11.
How Does Accessibility Work During an SPA State Transition?
A useful way to test an SPA is to treat each interaction as a pipeline:
    User action
        |
        v
    Application state change
        |
        v
    DOM update
        |
        v
    Focus decision
        |
        v
    Accessibility-tree update
        |
        v
    Assistive-technology output
A defect can occur at any point in that chain.
Consider a product-search filter:
- A keyboard user activates Filters.
- The application opens a filter panel.
- The DOM renders additional controls.
aria-expanded changes from false to true.- Focus either remains on the disclosure button or moves according to the chosen interaction pattern.
- Assistive technology receives the updated expanded state.
- The user changes a filter.
- Search results update asynchronously.
- Focus remains where the user was working.
- A status region announces, for example, “18 products found.”
Testing only step 3 would miss most of the accessibility behavior. This is why SPA accessibility testing must cover the entire pipeline, not just the DOM at rest.
A State-Transition Accessibility Matrix
For every important transition, record and verify the following:
| S. No |
Test dimension |
Question to answer |
| 1 |
Trigger |
Can the action be initiated without a pointer? |
| 2 |
Keyboard model |
Do the expected keys perform the expected actions? |
| 3 |
Focus destination |
Where is focus before and after the transition? |
| 4 |
Focus order |
Is the next sequential focus target logical? |
| 5 |
Focus visibility |
Is the focused component visible and unobscured? |
| 6 |
Semantics |
Does the accessibility tree expose the correct role and name? |
| 7 |
State |
Do properties such as expanded, selected, pressed, or invalid update? |
| 8 |
Announcement |
Does the user need an announcement, and if so, is it appropriately polite or urgent? |
| 9 |
Orientation |
Did the page title, heading, or current-navigation state change when navigation occurred? |
| 10 |
Recovery |
Can the user close, undo, go back, or otherwise leave the new state with the keyboard? |
This matrix turns vague accessibility review into a repeatable test method for single-page application accessibility.
Step-by-Step Process for SPA Accessibility Testing
1. Map Critical Routes, Components, and State Transitions
Start with user workflows rather than individual components.
A useful coverage model includes:
- Entry into a route
- Navigation between SPA views
- Opening and closing overlays
- Expanding and collapsing content
- Submitting forms successfully
- Triggering validation failures
- Starting and completing asynchronous operations
- Filtering or sorting collections
- Adding or deleting data
- Using browser Back and Forward navigation
The goal is to identify every transition where the user’s context, focus target, accessible state, or available information could change.
2. Establish a Semantic Baseline Before Testing Behavior
Before testing interactions, inspect the rendered view for semantic problems such as:
- Missing accessible names
- Invalid ARIA attributes
- Incorrect roles
- Incorrect heading structure
- Duplicate IDs that affect references
- Incorrect
aria-labelledby or aria-describedby references
- Interactive controls incorrectly hidden from the accessibility tree
WCAG SC 4.1.2 requires user-interface components, including script-generated controls, to expose programmatically determinable names and roles and to keep user-settable states, properties, and values available to assistive technologies.
Prefer native HTML controls where they provide the required behavior. W3C’s ARIA Authoring Practices Guide emphasizes that adding an ARIA role does not automatically supply the keyboard behavior users expect from that role.
For example, prefer:
<button type="button">Save changes</button>
over:
<div role="button" tabindex="0">Save changes</div>
The second implementation requires the application to reproduce button keyboard behavior correctly.
How Do You Test Keyboard Navigation in an SPA?
A complete keyboard test answers more than “Can I tab to everything?”
Start from the beginning of each critical workflow and put the pointer aside. Use Tab, Shift+Tab, Enter, Space, Escape, and any arrow-key interactions required by the component pattern.
Verify that:
- Every pointer-driven action has an equivalent keyboard path unless the underlying function inherently depends on path-based movement.
- Focus enters controls in an order that preserves meaning and operability.
- Focus never disappears into non-interactive or hidden content.
- Users can leave ordinary components without becoming trapped.
- Modal interfaces deliberately contain their tab sequence while open.
- Custom composite widgets follow the keyboard conventions associated with their pattern.
- A visible focus indicator remains available.
- Sticky headers, banners, chat widgets, cookie controls, and other overlays do not completely hide the component receiving focus.
These behaviors map directly to WCAG’s Keyboard, Focus Order, Focus Visible, and Focus Not Obscured requirements.
Do Not Assume Every Component Should Use Tab for Every Internal Item
ARIA widgets can have their own keyboard interaction models. For example, some composite widgets use Tab to enter and leave the component and arrow keys for movement inside it.
Implement the interaction model for the component you actually built rather than inventing a keyboard convention. ARIA Authoring Practices Guide documents expected keyboard models for common patterns.
Focus Management and Route Changes
When a route change represents a genuine change of context, consider the following sequence:
- Update the document title.
- Render the destination view.
- Move focus to a meaningful destination such as the main heading or main content container when the navigation represents a genuine change of context.
- Ensure the focus indicator remains visible.
- Continue normal keyboard navigation from that location.
For example:
    <main id="main-content" tabindex="-1">
        <h1>Orders</h1>
    </main>

    function announceRoute(viewTitle) {
        document.title = `${viewTitle} | Example Store`;
        requestAnimationFrame(() => {
            document.querySelector('#main-content').focus();
        });
    }
tabindex="-1" allows an element to receive programmatic focus without adding it to the ordinary sequential tab order.
Do Not Move Focus for Every DOM Update
A route change and a filter update are different.
If a user is typing in a search field and the results refresh underneath it, automatically moving focus to the results can interrupt the task. In that case, focus should normally remain in the input while a status message communicates the result.
A good test question for single-page application accessibility is:
Did this interaction change the user’s context, or did it merely update information within the current task?
Treat those two cases differently.
How Should Focus Work in Dialogs and Modal Overlays?
Modal dialogs need explicit focus behavior.
When a modal dialog opens:
- Focus moves to an appropriate element inside the dialog.
- Tab and Shift+Tab remain within the dialog while it is active.
- Escape normally closes the dialog.
- Content outside the modal is unavailable for interaction.
- The dialog has an accessible name.
aria-modal="true" is used only when the interface actually behaves modally.
When the dialog closes, focus usually returns to the control that opened it, unless the completed action logically makes a different destination more appropriate.
W3C’s modal-dialog pattern documents these behaviors and also notes that initial focus does not always belong on the first button. For long or structurally complex dialog content, a static heading or introductory element with tabindex="-1" can provide a more understandable starting point.
Test both directions: open, interact, close, continue.
A dialog is not accessible merely because focus is successfully trapped inside it; focus also has to enter and exit meaningfully.
How Do You Test ARIA Live Regions Reliably?
Do not test live regions by inspecting markup alone. A live region may contain perfectly valid HTML and still fail to produce a useful announcement in the browser and screen-reader combinations your users rely on.
For reliable behavior, create the live region before the update whenever possible:
<div id="cart-status" role="status"></div>
Later:
    document.querySelector('#cart-status').textContent =
        'Wireless keyboard added to cart';
Assistive technologies generally announce changes to live regions rather than treating their initial contents as updates. MDN recommends establishing the region before changing its content, and W3C techniques similarly demonstrate pre-existing containers for dynamic error messages.
Test actual output for:
- Whether the update is announced
- Whether it is announced once rather than repeatedly
- Whether the complete message is understandable
- Whether it interrupts unrelated speech unnecessarily
- Whether rapid consecutive updates overwrite or flood announcements
- Whether loading and completion messages occur in the expected order
Do not use an assertive live region as a substitute for good focus management.
When Should an Announcement Be Used?
Consider these three cases for SPA accessibility testing:
- The user is already focused on the changed component. If a disclosure button changes from collapsed to expanded, update its state. A separate live-region announcement is generally unnecessary because the component’s state itself can communicate the change.
- Information changes elsewhere without taking focus. This is a common use case for a status message. The
status role has an implicit aria-live="polite" value and an implicit atomic behavior, making it appropriate for advisory updates.
- The information is urgent. Use assertive announcements sparingly.
role="alert" is intended for important, time-sensitive information. Excessive assertive announcements can interrupt the user’s current speech and make an application harder to use.
How Do You Validate ARIA State Updates?
ARIA testing should verify the accessibility tree after interaction, not simply the source attributes before interaction.
Common state transitions include:
| S. No |
Interaction |
State to verify |
| 1 |
Expand or collapse control |
aria-expanded |
| 2 |
Toggle button |
aria-pressed |
| 3 |
Tab or option selection |
aria-selected |
| 4 |
Current SPA navigation item |
aria-current |
| 5 |
Invalid form input |
aria-invalid and associated error information |
| 6 |
Loading region |
aria-busy where appropriate |
| 7 |
Modal dialog |
aria-modal plus correct dialog semantics |
For each state, verify three levels:
    DOM
        |
        v
    Accessibility tree
        |
        v
    Actual assistive-technology experience
A passing DOM assertion alone does not prove that the component is usable.
W3C notes that incorrect ARIA can misrepresent a visual interface to assistive technologies. Native semantics should therefore be preferred where possible.
Practical Example: Testing an SPA Product-Search Workflow
Consider an e-commerce SPA with these interactions:
- /products loads without a full browser refresh.
- A Filters disclosure opens category filters.
- Selecting filters updates results asynchronously.
- A Quick view button opens a modal.
- Selecting a product navigates to a client-side product-details route.
- Adding the item to the cart produces a non-modal confirmation.
Preconditions
The test begins on /products with:
- A descriptive document title
- An
h1 identifying the current view
- A filter disclosure button
- A results region
- An empty status region already present in the DOM
Expected Test Sequence
1. Open Filters With the Keyboard
Expected:
- Enter or Space activates the native button.
- The panel becomes visible.
aria-expanded changes to true.- Focus behavior remains consistent with the disclosure pattern.
2. Select a Filter
Expected:
- The selection is operable with the keyboard.
- Focus remains on the user’s current control unless there is a strong reason to move it.
- Results update.
- A status message such as “18 products found” is announced.
- The user is not forced to navigate through the results to discover that the filter worked.
3. Open Quick View
Expected:
- Focus moves into the modal.
- Keyboard focus cannot move behind it.
- Escape closes it.
- The modal has an accessible name.
- Focus returns to the Quick view button after closing.
4. Open a Product
Expected:
- The SPA route changes.
- The document title changes to the product name.
- The new main view is identifiable.
- Focus is deliberately placed at an appropriate point in the new context.
- The next Tab continues logically.
5. Add the Product to the Cart
Expected:
- The add-to-cart control remains usable.
- A polite status announcement confirms the action.
- Focus is not unexpectedly transferred to the cart or toast unless the interaction explicitly requires that context change.
Typical Failures This Scenario Detects
- Filter button visually opens a panel but leaves
aria-expanded="false".
- Updated result count is visible but silent.
- Modal opens while focus stays on the underlying page.
- Modal closes and focus falls to
body.
- Product route changes while the page title remains “Products.”
- Focused controls disappear after state updates.
- The add-to-cart toast is injected and removed visually without an accessible announcement.
SPA Accessibility Testing vs Traditional Multi-Page Testing
| S. No |
Factor |
Traditional multi-page application |
Single-page application |
| 1 |
Navigation |
Browser loads a new document |
JavaScript may replace a view without reloading |
| 2 |
Page title |
Commonly supplied by the new document |
Must be updated deliberately for distinct SPA views |
| 3 |
Initial focus |
Browser naturally establishes a new document context |
Application may need deliberate focus management |
| 4 |
Dynamic updates |
Often limited |
Common throughout the interaction lifecycle |
| 5 |
ARIA state changes |
Component-dependent |
Frequently tied to reactive state |
| 6 |
Live regions |
Useful for AJAX updates |
Often important for asynchronous status information |
| 7 |
Test timing |
Usually after page load |
After every meaningful UI state transition |
| 8 |
Automation |
Scan each page |
Scan routes plus dynamically revealed and mutated states |
| 9 |
Manual testing |
Still required |
Especially important because focus and announcement timing are behavioral |
The underlying accessibility requirements are not unique to SPAs. What changes is the number and complexity of states that must be exercised.
Best Practices for Testing Accessible SPAs
Test User Journeys Rather Than Isolated Pages
A defect often appears while moving between states. Include accessibility assertions in end-to-end workflows such as checkout, authentication, search, account management, and data-entry processes.
Prefer Native HTML Before Adding ARIA
Native controls provide built-in keyboard and semantic behavior. Use ARIA to communicate semantics or states that native HTML cannot adequately express rather than recreating native behavior unnecessarily. W3C’s APG summarizes this principle as “No ARIA is better than Bad ARIA.”
Separate Focus Changes from Announcements
Moving focus is a major interaction change. Live regions are non-focus announcements. Decide which mechanism matches the event instead of applying both automatically.
Keep Route-Change Logic Centralized
If every feature implements client-side navigation differently, accessibility behavior will drift. Centralize responsibilities such as:
- Document-title updates
- Main-content focus
- Current-navigation state
- Scroll behavior
- Route-loading status
Test the Rendered State, Not Only Component Source
Accessibility defects frequently depend on CSS, portals, overlays, asynchronous rendering, or component composition. Browser-level testing is essential.
Test Actual Browser and Assistive-Technology Combinations
ARIA support is ultimately an interoperability question. Test representative combinations used by the intended audience instead of assuming that correct markup guarantees identical behavior everywhere.
Add Accessibility Checks to Regression Tests
Once a defect is found, for example focus not returning after a modal closes, add an automated assertion where practical so the same behavior does not silently regress. Teams building this layer often benefit from QA automation services that integrate accessibility checks directly into existing pipelines.
Troubleshooting Common SPA Accessibility Problems
Why does focus disappear after client-side navigation?
The previous focused element was probably removed during rendering, leaving the browser without a useful destination.
Verify document.activeElement after navigation and inspect what happens when the originating component unmounts. Then establish a route-transition policy that moves focus to a stable, meaningful destination after the new view renders.
Do not automatically apply the same behavior to simple in-place updates such as filtering.
Why does the screen reader not announce updated search results?
The new content may not qualify as a programmatically exposed status message, or the live region may have been created at the same time as its already-populated message.
Keep a stable role="status" container in the DOM and update its text when the result operation completes. WCAG SC 4.1.3 specifically addresses status messages that should be available to assistive technology without receiving focus.
Why is an ARIA control clickable but unusable with the keyboard?
ARIA changes semantics; it does not automatically implement keyboard behavior.
A div with role="button" still needs the interaction behavior users expect from a button. Whenever possible, replace it with an actual button. For custom widgets that do not have a native equivalent, implement the corresponding APG keyboard pattern.
Why does a modal trap users after it closes?
The application may remove the modal without restoring focus.
Record the invoker when the modal opens and restore focus when it closes, except when the completed action creates a new workflow location that is more logical. W3C’s dialog guidance describes both returning focus to the invoking element and cases where another destination is appropriate.
Why is keyboard focus technically present but invisible?
CSS may remove the browser outline, an overlay may cover the control, or a sticky header or footer may obscure it.
WCAG 2.4.7 requires a visible focus indicator, while WCAG 2.4.11 requires the focused component not to be entirely hidden by author-created content. Test responsive layouts and persistent overlays as well as desktop defaults.
Tools and Implementation Options for SPA Accessibility Testing
Accessibility testing works best as a layered process.
Browser and Accessibility-Tree Inspection
Browser developer tools can help inspect accessible names, roles, properties, computed states, and the accessibility tree. Use them while debugging, but do not treat tree inspection as a replacement for actual interaction testing.
Automated Rule Engines
Tools based on engines such as axe-core can identify many programmatically detectable accessibility problems and can be integrated into component, integration, and browser tests.
W3C cautions that evaluation tools cannot determine accessibility by themselves; some checks require human judgment.
Playwright With axe-core
Playwright’s accessibility-testing documentation demonstrates integrating @axe-core/playwright and recommends scanning UI after interactions reveal the state being tested. It likewise notes that automated testing must be combined with manual assessment.
Example:
    import { test, expect } from '@playwright/test';
    import AxeBuilder from '@axe-core/playwright';

    test('Orders SPA route exposes accessible state', async ({ page }) => {
        await page.goto('/dashboard');

        const ordersLink = page.getByRole('link', { name: 'Orders' });
        await ordersLink.focus();
        await page.keyboard.press('Enter');

        await expect(page).toHaveTitle(/Orders/);

        const heading = page.getByRole('heading', {
            level: 1,
            name: 'Orders'
        });
        await expect(heading).toBeFocused();

        const results = await new AxeBuilder({ page }).analyze();
        expect(results.violations).toEqual([]);
    });
The important idea is that the scan occurs after the route transition, not just on the original dashboard.
ARIA Snapshots
Current Playwright versions can also assert an accessibility-tree representation using ARIA snapshots. This can help detect regressions in roles, accessible names, hierarchy, and ARIA-derived states.
For example:
    await expect(page.getByRole('main')).toMatchAriaSnapshot(`
      - heading "Products" [level=1]
      - button "Filters" [expanded=false]
    `);
ARIA snapshots are useful regression signals, but they do not tell you whether a keyboard workflow makes sense or whether a screen reader announced a live update at an appropriate time.
Manual Screen-Reader Testing
Use representative browser and assistive-technology combinations from your supported environment to verify:
- Initial orientation
- Heading and landmark navigation
- Control names and states
- Client-side route changes
- Dynamic announcements
- Error handling
- Modal behavior
- Reading order
- Focus restoration
A valid ARIA attribute is not the same as a validated user experience.
What Automation Can Validate and What It Can Miss
Automation is strongest at detecting deterministic markup and semantic problems.
It can often identify issues such as:
- Invalid ARIA attributes
- Missing accessible names
- Certain role or property mismatches
- Some structural defects
- Certain contrast failures
It is much weaker at answering experiential questions such as:
- Is this the correct place for focus after navigation?
- Is the focus sequence understandable?
- Is an announcement useful or distracting?
- Did the screen reader announce a dynamic message at the right time?
- Is this custom widget’s keyboard model intuitive and complete?
- Does returning focus here preserve the user’s workflow?
W3C explicitly states that tools cannot automatically check every accessibility aspect and that knowledgeable human evaluation remains necessary.
For that reason, an SPA accessibility pipeline should use automation to increase coverage, not to eliminate manual accessibility testing.
Limitations and Risks
Screen-Reader Behavior Can Vary
Browsers and assistive technologies communicate through platform accessibility APIs. Support can vary by combination, especially for complex ARIA patterns and live-region timing.
Test the environments that matter to your users.
Automated Snapshots Can Become Brittle
Large accessibility-tree snapshots can fail because of legitimate content changes. Prefer focused assertions around important structures and states instead of treating an entire application tree as immutable.
Excessive Focus Management Can Be as Harmful as Insufficient Focus Management
An application that never moves focus can leave users disoriented after route changes. An application that moves focus after every state update can constantly interrupt them.
Base the decision on whether the interaction actually changes context.
Live Regions Can Become Noisy
Multiple independent components producing simultaneous announcements can create a confusing experience. Treat announcements as part of interaction design rather than sprinkling aria-live across the DOM.
APG Examples Are Patterns, Not Drop-In Production Guarantees
W3C notes that APG examples are illustrative and should be tested with the target browser and assistive-technology combinations before production use.
Need Help Testing Accessibility in Your Single-Page Application?
If your SPA handles client-side routing, dynamic content, or complex ARIA patterns, and you need to validate keyboard navigation, focus management, or screen-reader behavior, Codoid can help. Our accessibility specialists test against WCAG 2.2 using real browser and assistive-technology combinations, then integrate automated checks into your regression pipeline.
Talk to an Accessibility Testing Expert
Conclusion
Effective single-page application accessibility testing is fundamentally transition testing. Do not stop at asking whether the rendered DOM contains valid accessibility markup. Verify what happens when users navigate, expand, submit, filter, wait, fail, recover, open overlays, close overlays, and move between client-rendered views.
A reliable testing strategy combines four layers:
- Keyboard-only workflow testing
- Deliberate focus and route-transition testing
- Accessibility-tree and ARIA-state validation
- Screen-reader testing of dynamic announcements
Automated scanners and browser-level assertions should then preserve as much of that behavior as practical in regression tests. The practical next step is to inventory your application’s highest-value state transitions and apply the state-transition accessibility matrix to each one. That produces a test suite based on how the SPA actually behaves rather than treating a highly dynamic application as a collection of static pages.
Codoid’s accessibility testing services can help you build this layered testing model and validate your SPA against WCAG 2.2 and real assistive technology.
Frequently Asked Questions
-
Does every SPA route change need programmatic focus?
Not every DOM update needs focus movement. For a client-side transition that effectively behaves like navigation to a distinct page or view, deliberately establishing a meaningful focus location can help users understand the new context. For an in-place operation such as sorting, filtering, expanding content, or saving a setting, preserving focus is often more appropriate. Evaluate the interaction rather than applying a global "focus after every render" rule.
-
Should an SPA announce every route change with aria-live?
Usually not as a default strategy. Distinct SPA views should have meaningful document titles, and a route may also use deliberate focus management to establish context. Adding a live announcement on top of those signals can create redundant output. Test the actual experience and add an announcement only where it provides information users otherwise miss.
-
What is the difference between focus management and a live region?
Focus management changes the user's active interaction point. A live region allows assistive technology to announce updated information without moving focus. Use focus when the user's context or workflow has genuinely moved; use a live region for relevant background or status information that should be communicated while the user remains where they are.
-
Which ARIA role should be used for a normal success notification?
For a non-urgent status such as "Changes saved" or "12 results found," role="status" is usually appropriate because it provides polite live-region behavior. role="alert" should be reserved for messages requiring immediate attention because assertive announcements can interrupt current speech.
-
How often should accessibility scans run in an SPA?
Run automated checks during development and CI against representative application states, not only once per URL. At minimum, cover critical routes plus dynamically revealed states such as open dialogs, validation errors, expanded controls, authenticated views, and populated search results. Re-run manual keyboard and assistive-technology scenarios when changes affect routing, interaction patterns, overlays, forms, or dynamic messaging.
-
Is correct ARIA enough to make a custom SPA component accessible?
No. Correct ARIA can expose semantics and state, but the component must also provide the expected keyboard interaction, focus behavior, visual presentation, and usable interaction model. W3C specifically warns that assigning an ARIA role does not cause browsers to implement that role's keyboard behavior.
by Rajesh K | Sep 29, 2026 | API Testing, Blog, Latest Post |
AI API testing starts from a hard truth: an API can return the expected status code, satisfy its response schema, and still behave incorrectly. Imagine an order service that creates two orders when a client retries the same request. Both responses contain valid JSON. Both include legitimate order IDs. A test that checks only the status code and response structure may pass, even though the business operation has been duplicated. Now imagine the opposite problem: hundreds of tests fail because a shared authentication fixture expired. The application may be healthy, but engineers must still separate the underlying setup failure from its downstream symptoms.
These examples illustrate three useful places to apply AI to API testing specifically: deciding what to test, interpreting failures, and coordinating automation. If your team is testing distributed services more broadly, see our related guide on microservices API testing strategy for the layered testing approach this AI layer sits on top of.
How should AI be used in API testing?
The engineering challenge is to gain AI’s capabilities without surrendering control over correctness. AI should propose scenarios and explanations; explicit contracts, approved business rules, and executable assertions should determine pass or fail. Our API and backend testing services team applies this same hybrid model, using AI to widen coverage while keeping every pass/fail decision anchored to a reviewed assertion.
Automated test generation is not inherently AI-driven. Schemathesis generates property-based tests from API schemas, while Microsoft’s RESTler infers dependencies between operations and explores stateful request sequences. These approaches already provide capabilities beyond manually scripted examples.
Language models introduce another mechanism: interpreting descriptive context and proposing domain-relevant combinations. Research systems such as AutoRestTest combine language models with dependency graphs and reinforcement learning rather than relying on unconstrained text generation alone.
A practical implementation should follow the same hybrid principle:
| S. No |
Activity |
Useful AI contribution |
What should remain explicit |
| 1 |
Test case generation |
Interpret requirements and propose scenarios, data variations, and workflows |
Supported operations, fixtures, expected behavior, and safety limits |
| 2 |
Failure analysis |
Organize evidence, suggest related failures, and rank hypotheses |
Observed results, evidence references, and confirmation checks |
| 3 |
Automation |
Recommend test priorities and maintenance changes |
Mandatory coverage, execution permissions, and approval rules |
The goal is not to replace the test framework with a conversational model. It is to place a controlled reasoning layer around established testing infrastructure.
1. Test Case Generation: From API Descriptions to Meaningful Coverage
Ground generation in authoritative context
An OpenAPI description provides a machine-readable starting point: operations, parameters, request bodies, responses, and security requirements. It gives a generator a defined interface to work with instead of requiring it to invent one.
For a useful generation workflow, supplement that interface with approved business rules, authorization policies, fixture definitions, and existing regression tests.
Consider a hypothetical order API. Its relevant context might establish that:
- Quantity must be an integer between 1 and 10.
- Repeating an identical creation request with the same idempotency key must not create another order.
- Customers cannot read another tenant’s orders.
- An order can be cancelled only before shipment.
These rules describe different dimensions of correctness. A request schema can express the quantity constraint, but the generator also needs the approved meaning of an idempotent retry and the permitted lifecycle transitions.
Keep this context versioned. Retrieve documentation for the API revision under test, and record which requirement supports each proposed assertion. When documentation and implementation disagree, report the conflict rather than silently selecting whichever behavior makes the test pass.
Observed behavior is evidence about the system, not automatically the definition of correct behavior.
Generate a coverage model before generating scripts
A useful first output is a scenario matrix, not a directory full of test files.
For the hypothetical order API, ask the model to propose coverage across several dimensions:
| S. No |
Coverage dimension |
Example scenario |
Required oracle |
| 1 |
Valid boundaries |
Create orders with quantities 1 and 10 |
Both values are accepted under the documented contract |
| 2 |
Invalid inputs |
Submit 0, 11, null, or a string quantity |
The documented validation error occurs without creating an order |
| 3 |
Authorization |
Read a real order using another tenant’s identity |
Access is denied according to the approved policy |
| 4 |
Stateful behavior |
Create, cancel, then retrieve an order |
The persisted state reflects the permitted transition |
| 5 |
Idempotency |
Repeat an identical request with the same key |
The same logical order is returned without duplicate creation |
| 6 |
Concurrency |
Submit overlapping requests with the same key |
The documented duplicate-handling invariant holds |
| 7 |
Metamorphic behavior |
Change page size while reading a fixed collection |
The complete result set remains equivalent under a stable snapshot |
Authorization deserves explicit treatment. OWASP describes broken object-level authorization as a failure to verify whether the authenticated user may act on the particular object identified in a request, not merely whether that user can access the endpoint.
For that reason, pair a negative authorization test with a positive control: first establish that the resource exists and its owner can read it, then attempt access using a different identity. Otherwise, a missing fixture could produce a denial response and create false confidence.
Similarly, stateful tests should obtain real resource identifiers from earlier responses instead of guessing them. Schemathesis documents this approach by chaining operations and using response values as inputs to subsequent calls.
Use AI to propose meaningful relationships. Let the runner manage identifiers, credentials, setup, and cleanup.
Keep the test oracle independent
A test oracle is the mechanism that decides whether an observed result is correct.
An AI-generated request without a defensible oracle is an experiment, not yet a reliable regression test.
Use different checks for different questions. Schema validation checks response structure. Business assertions check rules such as “a cancelled order cannot transition to shipped.” State inspection checks whether a failed request created unwanted records. Consumer-driven contracts check interactions that actual clients depend on; Pact, for example, generates contracts from consumer tests and verifies those expectations against providers.
When an exact expected response is unavailable, consider an approved invariant or metamorphic relation. For example, changing pagination size should not change the complete collection returned under the same stable snapshot.
However, the model must not invent that relation. Pagination behavior, ordering guarantees, consistency windows, and filtering rules must support it.
A particularly dangerous workflow is to show the model the application’s current response and ask it to generate the expected response for the same test. That can turn an existing defect into an approved expectation.
Prefer constrained test plans over arbitrary executable code
Instead of immediately requesting Python or JavaScript, ask the model for a declarative plan using an approved vocabulary.
A generation instruction could be:
Using only the supplied API operations, fixtures, and requirement IDs, propose tests for uncovered behavior. Select approved execution templates and assertion references. Do not invent expected status codes. Mark scenarios with missing requirements as unresolved.
An illustrative output might be:
{
"case_id": "order-replay-boundaries",
"operation_id": "createOrder",
"template": "repeat_create_then_query",
"fixture": "isolated_tenant_with_stock",
"parameters": {
"quantity": [1, 10]
},
"assertion_refs": ["ORDER-IDEMPOTENCY-001"],
"source_refs": [
"openapi@api-revision:createOrder",
"order-rules@rules-revision:ORDER-IDEMPOTENCY-001"
]
}
Validate more than JSON syntax. Confirm that the operation exists, the fixture is available, the template permits the requested action, and the assertion reference resolves to an approved rule.
Also distinguish plan validation from API-input validation. Negative tests intentionally contain invalid API inputs. Rejecting every payload that violates the API schema would eliminate precisely the cases a negative-testing workflow needs.
The model proposes the plan; a controlled compiler or reviewed implementation turns it into executable tests.
A practical example: testing idempotent order creation
The following example implements the proposed replay scenario using pytest and HTTPX. Pytest parametrization runs the same behavior against multiple inputs, while an HTTPX client provides shared request configuration and connection management.
This is an illustrative API contract, not a universal definition of idempotency: the first POST /orders returns 201 with a string id. An identical request using the same Idempotency-Key, within its retention window, returns 200 with that same ID. A filtered GET /orders provides a read-after-write-consistent result containing items and total.
The CI environment must provision an isolated tenant, a scoped token, and an in-stock SKU. It must also destroy the tenant after the run, including when tests fail.
# test_orders.py
import os
from collections.abc import Iterator
from uuid import uuid4

import httpx
import pytest


@pytest.fixture
def api() -> Iterator[httpx.Client]:
    required = ("API_TEST_BASE_URL", "API_TEST_TOKEN", "TEST_SKU")
    missing = [name for name in required if not os.getenv(name)]
    if missing:
        pytest.fail(f"Missing test configuration: {', '.join(missing)}")
    with httpx.Client(
        base_url=os.environ["API_TEST_BASE_URL"],
        headers={
            "Authorization": f"Bearer {os.environ['API_TEST_TOKEN']}"
        },
        timeout=httpx.Timeout(10.0, connect=3.0),
        follow_redirects=False,
    ) as client:
        yield client


@pytest.mark.parametrize(
    "quantity",
    [1, 10],
    ids=["minimum-quantity", "maximum-quantity"],
)
def test_create_order_is_idempotent(
    api: httpx.Client,
    quantity: int,
) -> None:
    reference = uuid4().hex
    headers = {"Idempotency-Key": uuid4().hex}
    payload = {
        "sku": os.environ["TEST_SKU"],
        "quantity": quantity,
        "client_reference": reference,
    }
    first = api.post("/orders", json=payload, headers=headers)
    assert first.status_code == 201, (
        f"Initial creation returned {first.status_code}"
    )
    order_id = first.json()["id"]
    assert isinstance(order_id, str) and order_id
    replay = api.post("/orders", json=payload, headers=headers)
    assert replay.status_code == 200, (
        f"Replay returned {replay.status_code}"
    )
    assert replay.json()["id"] == order_id
    listing = api.get(
        "/orders",
        params={"client_reference": reference},
    )
    assert listing.status_code == 200
    result = listing.json()
    assert result["total"] == 1
    assert len(result["items"]) == 1
    assert result["items"][0]["id"] == order_id
    assert result["items"][0]["quantity"] == quantity
With the environment configured, run it using:
python -m pip install pytest httpx
python -m pytest -q test_orders.py
Pin dependencies in the project’s lockfile when adopting the example.
Notice what the test does, and does not, establish. It checks both response identity and the visible number of persisted orders. It does not prove that inventory was reserved only once or that a downstream event was emitted only once. Those effects require additional observers and assertions.
It also tests sequential replay, not overlapping requests. Concurrency testing needs a separate scenario with controlled overlap and its own evidence collection.
Finally, HTTPX’s connect, read, write, and pool timeouts are operation-specific limits, not a complete wall-clock deadline for the test suite. Configure a separate CI execution deadline.
2. Failure Analysis: From Error Messages to Evidence-Backed Hypotheses
Generating tests is only part of the problem. The next challenge is explaining what a failure actually means.
Related cloud-incident research provides a useful architectural example: RCACopilot combines runtime diagnostic collection with language-model-based categorization and explanations. Its results concern cloud incidents, however, and should not be assumed to transfer directly to a particular API test suite.
For API testing, build an evidence-first workflow rather than asking a model to diagnose an isolated stack trace.
Create a structured failure bundle
Before invoking AI, collect the test and requirement revisions, expected and actual results, sanitized request details, fixture identity, execution attempt, deployment version, and relevant diagnostic references.
Include distributed traces when available. OpenTelemetry defines standard HTTP attributes such as http.request.method, http.response.status_code, and the server-side route template http.route, which can provide consistent fields for comparing failures across services.
Keep the bundle focused. A specific assertion, its request sequence, and the relevant downstream spans are generally a better input design than an unrestricted dump of unrelated logs.
Also preserve the distinction between a response and a transport failure. “The API returned an unexpected status” and “the client never received a response” require different investigations.
Separate observations from interpretation
An analysis result should distinguish established facts, hypotheses, alternative explanations, and the next checks needed to discriminate between them.
Suppose a follow-up investigation of the order test produces this illustrative report:
Observed: Two requests used the same tenant, payload, and idempotency key. Both returned 201, with different order IDs. A subsequent state query found two orders.
Hypothesis: The second request bypassed or failed the deduplication lookup.
Alternative explanations: The requests reached instances with inconsistent configuration, or the server calculated different internal key scopes.
Next checks: Compare the computed deduplication keys, inspect the relevant request paths, and repeat against a controlled deployment configuration.
This is useful because every proposed explanation has a verification path.
By contrast, “the cache is broken” is not a root-cause analysis unless the evidence establishes that conclusion.
Require references to the trace, log event, assertion, or configuration supporting each factual observation. Allow the model to return “insufficient evidence.” A confidence number should not replace missing diagnostics.
Group failures without merging unrelated defects
Use deterministic attributes for initial grouping: the violated invariant, normalized exception frames, operation, failing dependency, and deployment revision.
AI can then suggest broader relationships, for example, that several apparently different failures may share an authentication setup problem. Verify those proposed groups against the underlying evidence before treating them as one defect.
Avoid grouping by status code alone. Two 500 responses may have different causes, while a single dependency failure may produce timeouts, validation failures, and unexpected empty responses across the suite.
The same discipline applies to flaky tests. A passing retry does not prove the original failure was harmless. Preserve the first result and investigate whether controlled reruns implicate timing, shared state, infrastructure, or a genuine race condition.
Reduce failures into reproducible regressions
After identifying a meaningful failure, reduce the request sequence and payload while preserving the same violated invariant.
AI can suggest which fields or steps appear unnecessary. The runner must confirm that removing them still reproduces the original failure, not merely some other error.
Save the resulting test artifact, fixture recipe, request sequence, environment revision, and relevant random seeds. Preserve generated identifiers as diagnostic evidence, while recreating valid resources during replay.
The desired output is not just a readable explanation. It is a small, reviewable regression test and enough evidence for an engineer to act.
3. Smarter Automation: Prioritization, Maintenance, and Controlled Execution
The third opportunity is to improve how the suite operates without allowing AI to redefine its obligations.
Prioritize tests using change and risk
Build a mapping between tests, operations, shared schemas, authorization components, and downstream dependencies. Use that mapping to identify which tests a change may affect.
An AI-assisted scheduler can propose priorities using change relevance, business impact, previous defect history, and estimated runtime. Treat those priorities as recommendations within explicit coverage rules.
For example, make critical smoke, authorization, and core lifecycle tests mandatory. Run affected dependency and contract tests next. Reserve a fixed exploration budget for scenarios that the prioritizer did not select, and retain broader scheduled runs.
When dependency metadata is missing, expand execution rather than silently assuming an operation is unaffected.
Do not optimize exclusively around previously failing tests or frequently observed traffic. That would make rare workflows and previously unseen defects easy to neglect.
Make maintenance reviewable, not self-concealing
AI-assisted maintenance should produce a proposed patch with a reason, a supporting requirement, and a visible assertion diff.
Updating a fixture to match an approved request-field change is different from weakening an assertion because the implementation changed unexpectedly.
For example, changing:
assert response.status_code == 403
to:
assert response.status_code in (200, 403)
may make a test pass while removing its ability to detect unauthorized access.
Require review for changes to authorization expectations, accepted status codes, required fields, side-effect checks, and business invariants. Preserve the original failing result so the proposed repair can be evaluated against it.
A green pipeline is not evidence of correctness when the system is allowed to relax its own expectations.
Keep generation separate from routine execution
A practical architecture is:
Versioned API specifications, rules, and fixture definitions
↓
AI-generated test plan
↓
Structural, semantic, and policy validation
↓
Reviewed test artifact
↓
Isolated test runner
↓
Sanitized evidence bundle
↓
AI triage and maintenance suggestions
↓
Reviewed regression update
This separation keeps model availability out of the critical path for already-approved regression tests.
Generate or revise tests when requirements change. Run the saved artifacts normally. Invoke AI analysis for new or meaningfully changed failure groups rather than repeatedly submitting identical failures.
Use deterministic logic where it is sufficient. A model does not need to calculate minimum minus 1 or enumerate a small declared enum. Spend model calls on ambiguous prose, cross-operation relationships, and domain-specific scenarios.
For performance testing, keep workload definitions and acceptance thresholds explicit as well. AI may summarize a latency change or suggest an investigation, but it should not independently redefine a service-level target or excuse a failing result.
Protect the Testing System Itself
An AI-assisted testing pipeline has its own trust boundaries.
API descriptions, response bodies, issue comments, and logs may contain untrusted text. OWASP identifies indirect prompt injection through external content and recommends controls including tool-call validation, least privilege, and human approval for sensitive actions.
Apply those controls outside the model. Restrict execution to approved origins and operations. Keep credentials in the runner rather than in prompts. Cap request volume, concurrency, and resource creation. Do not give generated plans unrestricted shell access or production-wide permissions.
Sanitize data before it enters prompts, retrieval indexes, or stored analysis artifacts. OpenTelemetry’s HTTP conventions recommend explicit configuration of captured headers, and its URL conventions require scrubbing known sensitive query parameters. Those are useful foundations for a deliberately limited diagnostic bundle.
Maintain an audit trail connecting each generated test to its source revisions, generation configuration, approved assertions, and reviewer. The same traceability should apply to AI-proposed maintenance patches.
Measure Defect Detection, Not Generated Test Volume
Evaluate the addition of AI against a meaningful baseline: the existing suite plus conventional schema-based or property-based testing.
Use historical defective builds, controlled fault injection, and held-out incidents. Keep incident resolutions out of the triage model’s input when evaluating whether it can diagnose those incidents.
Useful measures include:
| S. No |
Measure |
What it reveals |
| 1 |
Executable, applicable proposals divided by all proposals |
Whether generation produces usable scenarios rather than merely valid-looking output |
| 2 |
Confirmed new defects per fixed execution and review budget |
Whether the AI layer adds value beyond existing coverage |
| 3 |
Detection of eligible seeded faults or mutants |
Whether generated assertions respond to deliberately introduced defects |
| 4 |
Correct triage recommendations, alongside abstention rate |
Whether explanations are actionable and appropriately cautious |
| 5 |
Reproduction and flaky-failure rates |
Whether results remain dependable across controlled runs |
| 6 |
End-to-end cost and time to an actionable diagnosis |
Whether operational gains outweigh model and review overhead |
Deduplicate defects rather than counting every failing request as a discovery. Include rejected and unexecutable proposals in generation-quality measurements.
Evaluate generation and diagnosis separately. A system may propose useful tests while producing weak explanations, or diagnose failures well while adding little new coverage.
Start with reviewed test proposals and non-blocking triage suggestions. Expand automation only after measuring their performance on the actual service, and repeat the evaluation when models, prompts, or retrieval logic change.
Conclusion
AI API testing is most useful when it helps engineers ask better questions and work through evidence more effectively. For test case generation, ground proposals in versioned contracts, business rules, and realistic workflows. For failure analysis, require observations, evidence references, competing hypotheses, and reproducible checks. For smarter automation, use AI to recommend priorities and maintenance changes while keeping coverage obligations, permissions, and assertions under explicit control.
The strongest outcome is not the largest generated test suite. It is a collection of meaningful tests whose failures are reproducible, whose expectations are defensible, and whose results engineers can trust. Talk to our API testing team if you want help building this into your own pipeline.
Frequently Asked Questions
-
What is the safest way to use AI for API test case generation?
Ground generation in a versioned OpenAPI description plus approved business rules, authorization policies, and fixtures, rather than letting the model invent its own interface. Ask for a declarative test plan referencing approved operations and assertion IDs first, and let a controlled compiler or reviewed implementation turn that plan into executable tests.
-
Why shouldn't AI generate the expected result from the application's current response?
If a model is shown the application's current output and asked to produce the "expected" value for that same test, it can turn an existing defect into an approved expectation. Expected results should come from approved examples, independently reviewed calculations, or a trusted reference implementation instead.
-
How should AI be used to analyze API test failures?
Build an evidence-first workflow: collect a structured failure bundle (request details, fixture identity, deployment version, distributed traces) before invoking AI, then require the analysis to separate established facts from hypotheses and alternative explanations, each with a verification path. Allow the model to say "insufficient evidence" rather than forcing a confident-sounding guess.
-
Can AI safely rewrite or relax a failing test's assertions?
Only under review. Changing an assertion like status_code == 403 to status_code in (200, 403) can make a test pass while removing its ability to detect unauthorized access. AI-assisted maintenance should produce a proposed patch with a reason and a visible assertion diff, not silently weaken the check to get a green pipeline.
-
What security risks does AI introduce into an API testing pipeline?
API descriptions, response bodies, and logs can contain untrusted text that attempts indirect prompt injection. Controls like tool-call validation, least-privilege execution, keeping credentials in the runner rather than in prompts, and requiring human approval for sensitive actions should be enforced outside the model, not requested from it.
-
How do you measure whether AI is actually improving an API test suite?
Track confirmed new defects found per execution and review budget, the rate of executable versus rejected proposals, detection of seeded faults or mutants, and reproduction and flaky-failure rates, evaluated against a baseline of the existing suite plus conventional schema-based testing. Generated test volume alone is not a useful measure.
by Rajesh K | Sep 28, 2026 | Artificial Intelligence, Blog, Latest Post |
AI test cases can compile, pass in continuous integration, and still verify the wrong behavior. That gap exists because research on generated test oracles, the logic that decides whether a result is correct, has found that models can reproduce what a program currently does rather than what it is supposed to do. A passing test may therefore preserve a defect instead of detecting it. Execution success and testing value are also different outcomes. In a 2024 evaluation of Meta’s TestGen-LLM on Instagram’s Reels and Stories products, 75% of generated test cases built correctly, 57% passed reliably, and 25% increased coverage. Those are results from a particular system and evaluation, not expected success rates for every generator, but they illustrate why AI test cases need several independent checks.
Treat AI test cases as proposed changes to your verification system, not as trusted evidence merely because they look plausible.
How do you evaluate AI test cases before using them?
A practical acceptance framework should answer four questions: does the test check the intended behavior with a justified expectation (accuracy), which important behaviors does it actually exercise and verify (coverage), does it add useful verification beyond existing tests (redundancy), and can it run safely and reproducibly (executability). Our LLM testing services team applies this same four-dimension framework when qualifying AI test cases for clients.
| S. No |
Dimension |
Question to answer |
Evidence to inspect |
| 1 |
Accuracy |
Does the test check the intended behavior using justified expectations? |
Requirements, oracle provenance, input validity, assertion review |
| 2 |
Coverage |
Which important behaviors and failure modes does it actually exercise and verify? |
Scenario traceability, branch coverage, mutation results, known-defect checks |
| 3 |
Redundancy |
Does it add useful verification beyond existing tests? |
Semantic comparison, per-test coverage, fault-detection overlap, removal experiments |
| 4 |
Executability |
Can it run safely and reproducibly in the intended environment? |
Discovery results, setup and teardown outcomes, dependency checks, repeated runs |
These dimensions should remain separate. High coverage cannot compensate for an incorrect expected result. Reliable execution cannot justify a test that asserts nothing meaningful.
Key takeaways
- A passing AI-generated test is not proof of correctness; the oracle behind the assertion needs independent review.
- Build your scenario inventory from the approved contract first, not from what the generator happened to produce.
- Redundancy is a semantic question, not a text-similarity question; two differently worded tests can check the same thing, and two similar-looking tests can protect different boundaries.
- Executability includes discovery, setup, teardown, and stability under realistic conditions, not just “the test passed once.”
- Score accuracy, coverage, redundancy, and executability separately. Do not collapse them into one AI-test-quality score.
Start With an Approved Contract
Before evaluating generated output, define what the tests are allowed to treat as authoritative.
That usually means a versioned combination of acceptance criteria, API contracts, business rules, approved examples, and architectural constraints. Use implementation code to understand interfaces and execution paths, but do not automatically treat its current output as the correct answer.
Consider a shipping service with the following illustrative contract:
| S. No |
Requirement |
Approved behavior |
| 1 |
SHIP-1 |
Standard orders with a subtotal of at least 5,000 cents have free shipping. |
| 2 |
SHIP-2 |
Standard orders below 5,000 cents incur a 499-cent shipping fee. |
| 3 |
SHIP-3 |
Premium orders with nonnegative subtotals have free shipping. |
| 4 |
SHIP-4 |
Negative subtotals raise ValueError, regardless of membership. |
Assume the application accepts integer subtotals and exposes:
shipping_fee(subtotal_cents: int, *, premium: bool) -> int
This contract gives reviewers something concrete to evaluate. It also identifies what is not specified. For example, behavior for strings, floating-point inputs, or None needs clarification rather than an invented expectation.
Keep the generation context alongside the candidates: the requirement revision, source commit, existing-suite revision, model and prompt versions, and any supplied examples. Record unresolved assumptions explicitly.
For manual test cases, require concrete preconditions, test data, actions, expected results, and cleanup instructions. “Verify that shipping works correctly” is not an executable procedure.
For automated cases, require the same information, with a clear mapping to fixtures, application calls, and assertions.
1. Accuracy: Does the Test Verify the Right Behavior?
Accuracy begins with the test oracle, not the test name.
A scenario titled test_free_shipping_threshold might look relevant while asserting the wrong threshold behavior. Review the relationship between its preconditions, inputs, actions, and expected results.
Validate Expectations Independently
Under the shipping contract, this generated assertion is incorrect:
# Incorrect: exactly 5,000 cents qualifies for free shipping.
assert shipping_fee(5000, premium=False) == 499
The assertion is syntactically valid. It might even pass against a faulty implementation using subtotal > 5000. Neither fact makes the test correct.
A different candidate might contain a true but insufficient assertion:
# Too weak to verify either the threshold or the correct fee.
assert shipping_fee(5000, premium=False) >= 0
This test accepts both 0 and 499. It cannot distinguish correct threshold behavior from the defect above.
That distinction matters: an assertion can be logically true without adequately verifying the requirement it claims to cover.
For each candidate, ask: what plausible incorrect implementation would this test reject? A reviewer should be able to identify a specific answer: an off-by-one threshold, the wrong fee, an unauthorized state change, an omitted database write, or another relevant failure.
Watch for Circular Verification
A generated test can also calculate its expected result from the same system it is supposed to verify:
expected = shipping_fee(5000, premium=False)
actual = shipping_fee(5000, premium=False)
assert actual == expected
This checks repeatability for that input, not compliance with the shipping rules.
The same problem appears when generated tests copy production calculations into their expected-value logic or mock the function under test and then assert the mocked return value.
Prefer expectations justified by approved examples, independently reviewed calculations, or a trusted reference implementation. Differential testing against another implementation is useful evidence, but agreement between implementations is not proof that both satisfy the contract.
Likewise, ask a second model to identify suspicious assertions, but do not treat model agreement as independent ground truth.
Review the Whole Scenario
Oracle review alone is insufficient. A correct expected result attached to the wrong setup still makes a misleading test.
Suppose a scenario claims to verify standard-account shipping, but its fixture creates a premium account. An expected zero fee might pass for the wrong reason.
Inspect account roles, feature flags, initial state, request payloads, and mocked dependencies. For state-changing operations, check the relevant side effects as well as the immediate response. A successful API response and a correctly persisted order are different observations.
When evaluating existing behavior during a legacy-system migration, distinguish characterization tests, which record current behavior, from requirements tests, which assert intended behavior. Do not silently promote the former into proof of the latter.
Use a Review-Based Accuracy Metric
A practical metric is:
Validated-case rate = (Cases confirmed semantically valid ÷ Cases reviewed) × 100
Classify reviewed cases as valid, incorrect, or unresolved. Keep unresolved cases in the denominator rather than making uncertainty disappear.
For example, if 80 of 100 reviewed cases are valid, 12 have incorrect expectations, and eight depend on unresolved requirements, the validated-case rate is 80%. The unresolved 8% should be reported separately.
This is a measure of review outcomes, not an estimate of the application’s correctness. Report whether the review covered every candidate or a sample, and examine high-risk cases individually.
2. Coverage: What Does the Suite Actually Verify?
Coverage needs more than one view.
Code coverage describes execution. Requirements coverage describes which obligations have tests. Fault-detection evidence describes whether those tests reject relevant incorrect behavior.
Google’s testing guidance explicitly warns that covered lines and branches have been executed, but have not necessarily been tested correctly. It recommends using coverage alongside other evidence rather than treating it as a complete measure of test quality.
Build the Scenario Inventory Independently
Do not ask the generator to create tests and then judge completeness only against the scenarios it generated.
Create a reviewed inventory from the contract first. For the shipping service, useful obligations include:
| S. No |
Scenario |
Expected outcome |
Why it matters |
| 1 |
Standard account, subtotal 4999 |
Fee 499 |
Immediately below the threshold |
| 2 |
Standard account, subtotal 5000 |
Fee 0 |
Exact inclusive boundary |
| 3 |
Standard account, subtotal 5001 |
Fee 0 |
Immediately above the threshold |
| 4 |
Standard account, subtotal 0 |
Fee 499 |
Lowest nonnegative subtotal |
| 5 |
Premium account, subtotal 0 |
Fee 0 |
Membership overrides the standard fee |
| 6 |
Negative subtotal, standard account |
ValueError |
Input validation |
| 7 |
Negative subtotal, premium account |
ValueError |
Validation still applies to premium accounts |
The last scenario protects a different failure mode from the preceding one. An implementation could return free shipping for premium customers before validating the subtotal.
For a larger application, extend the inventory to state transitions, permissions, retries, partial failures, configuration combinations, and integration boundaries. Define nonfunctional obligations separately. A unit-test suite cannot establish a latency requirement without a suitable workload, measurement method, and environment.
Measure Coverage Against Explicit Obligations
A useful scenario-coverage measure is:
Scenario coverage = (Applicable obligations with valid, executed checks ÷ Total applicable obligations) × 100
A requirement ID in a comment is not enough. The test must actually exercise the scenario and evaluate a relevant outcome.
Also distinguish planned coverage from demonstrated coverage. A reviewed test that cannot run represents planned verification, not completed evidence.
For risk-sensitive systems, use a weighted version:
Risk-weighted coverage = (Σ wi × ci ÷ Σ wi) × 100

where wi is a pre-agreed risk weight for obligation i,
and ci is 1 when the obligation has a valid, executed check, and 0 otherwise.
Set weights before evaluating the generated suite. Otherwise, changing weights can become another way to improve the dashboard without improving testing.
Keep critical gaps visible individually. An aggregate score should not conceal an untested authorization rule.
Finally, coverage is not a pass rate: a valid test that exposes a product defect can cover an obligation while showing that the implementation violates it.
Measure Incremental Code Coverage
Evaluate candidates against the existing suite:
Incremental coverage = coverage(existing suite + candidates) − coverage(existing suite)
Keep the source revision, measurement scope, exclusions, and environment constant.
Prefer branch information where decisions matter. Coverage.py’s documentation illustrates how statement coverage can report all lines executed even when one outcome of an if condition was never taken; branch measurement exposes that missing transition.
Inspect which branches were added, not only the percentage-point increase. Newly executed error-handling logic may be more valuable than additional incidental initialization coverage.
Conversely, zero additional branch coverage does not automatically make a candidate useless. A stronger assertion may detect a defect on a path the existing suite already executes.
Test the Tests With Mutations
Mutation testing introduces controlled changes to application code and checks whether the tests detect them. A mutant is typically considered killed when the altered program causes a test to fail. PIT and Stryker document this approach as a way to assess test effectiveness beyond execution coverage.
For the shipping service, useful mutations include changing >= 5000 to > 5000, returning the wrong fee, removing negative-input validation, or allowing the premium check to bypass validation.
Measure which baseline-surviving mutants the candidates newly detect. Keep mutation operators and the evaluated code scope fixed when comparing suites.
Inspect result categories, not just the headline score. Tools can distinguish killed, surviving, uncovered, invalid, and timed-out mutants, and their scoring conventions matter. Equivalent mutants, changes that do not alter observable behavior, also limit the interpretation of a perfect-score target.
A mutant failing because the test environment crashed is not the same evidence as a targeted assertion detecting the intended behavioral change.
Add Properties Where They Strengthen the Contract
Property-based testing can complement concrete examples by generating inputs from a defined domain and searching for violations of an asserted property. Hypothesis supports this style of testing in Python.
For the illustrative contract, a reviewed property could state that the fee for a standard account never increases when a nonnegative subtotal increases.
That property is useful, but insufficient alone: an implementation returning zero for every subtotal would satisfy it. Retain concrete examples for exact fees and boundaries.
Generated properties and metamorphic relationships need oracle review just as much as generated example-based assertions.
3. Redundancy: Does Each Test Add Useful Evidence?
Redundancy is not the same as textual similarity.
Two differently named tests may perform the same setup, use inputs from the same partition, and assert the same outcome. Conversely, two almost identical tests at 4999 and 5000 protect different sides of a boundary.
Evaluate duplication both within the generated batch and against the existing suite.
Compare Semantics Before Deleting Tests
A useful comparison record includes the requirement, initial state, input partition, action, expected outcome, assertion target, and test layer.
Text similarity, embeddings, or normalized syntax trees can help identify candidates for review. Treat their output as a shortlist, not a deletion decision. Normalization that removes literal values can erase the difference between an ordinary input and a critical boundary.
Where available, add execution evidence. Coverage.py can record measurement contexts, allowing execution information to be associated with individual tests or other contexts.
However, identical execution coverage is still not proof of redundancy. One test might check a response code while another checks that no unauthorized state change occurred.
Use Controlled Removal Experiments
A defensible removal process is to temporarily remove a suspected duplicate, rerun the relevant evidence checks, and compare what was lost.
Evaluate scenario coverage, important mutant kills, known-defect detection, and diagnostic usefulness. Preserve deliberate verification at different layers when it protects distinct risks, for example, a unit test for a calculation and an integration test for the API’s mapping of that result.
Remove candidates incrementally. If two tests are interchangeable, either may be removable individually, but deleting both can create a gap.
A practical reporting metric is:
Redundancy reduction rate = (Candidates removed as unnecessary duplicates ÷ Valid, executable candidates before deduplication) × 100
Record the evidence supporting each removal. This measures redundancy under the chosen evaluation criteria, not universal equivalence under every future code change.
Parameterization is often a better outcome than deletion. It reduces repeated test code while preserving separate input scenarios and failure identities.
The objective is useful verification at reasonable maintenance and execution cost, not the smallest possible test count.
4. Executability: Can the Test Run Safely and Reproducibly?
Executability has several stages: discovery, dependency resolution, setup, application interaction, outcome evaluation, and cleanup.
A test that parses successfully has completed only an early check.
Review Before Running
Inspect generated imports, fixtures, API calls, selectors, dependency changes, filesystem operations, and external requests.
Reject or repair candidates that invent helper methods, reference unavailable fixtures, require undocumented accounts, or depend on local state that CI does not have. Do not automatically install every package a generated test requests.
Treat generated code as untrusted during evaluation. OpenAI’s HumanEval repository, for example, explicitly warns against executing model-generated code outside a robust security sandbox.
Use a security-reviewed disposable environment with synthetic data, restricted credentials, controlled network access, and resource limits. Do not expose production secrets, privileged host interfaces, or unrestricted write access.
Place test collection inside that boundary too: pytest imports test modules as part of its integration and discovery behavior, so collection should not be treated as passive text inspection.
Confirm That the Intended Tests Actually Ran
Compare expected scenario IDs with collected and executed IDs. A successful job is insufficient when the intended tests were skipped, deselected, or never discovered.
Pytest supports collection-only inspection and reports a distinct exit code when no tests are collected. Its skip and expected-failure mechanisms also require explicit review: an expected failure is not an ordinary passing assertion.
Track setup errors, assertion outcomes, teardown errors, skipped cases, expected failures, and unexpected passes separately.
A useful metric is:
Executable-case rate = (Scheduled cases that reach a verdict and complete cleanup ÷ Cases scheduled for execution) × 100
An assertion failure can still be a valid execution outcome. A missing fixture is a different category.
Investigate Failures Before Repairing Tests
When a candidate fails, determine whether the cause is an incorrect test, a product defect, an environment problem, or an unresolved contract.
Do not replace an expected value with the observed value merely to obtain a green run.
A valid test exposing a confirmed defect should enter the defect-management workflow. Preserve it as a reproducer and, after the fix, as regression protection. Any temporary expected-failure treatment should have an owner, a linked issue, and a removal condition.
This distinction prevents a generator’s “repair” loop from turning defect detection into defect acceptance.
Evaluate Stability Under Meaningful Variations
Run candidates in isolation, with the existing suite, in different orders, and under the intended parallelism. Control or record clocks, time zones, random seeds, database state, and external-service behavior.
Pytest’s documentation identifies insufficiently controlled state, ordering dependencies, cleanup problems, and overly strict assertions as potential causes of flaky tests.
For UI tests, prefer observable readiness conditions over arbitrary sleeps. Playwright supports actionability checks and retrying assertions; its guidance recommends resilient locators based on user-facing attributes and explicit contracts.
Report the number and conditions of repeated runs. “No failures observed in 20 runs” is evidence, not proof of determinism. Under independent runs with a true 1% failure probability, the probability of seeing 20 consecutive passes is:
Retries should not erase the first failure from evaluation records. Distinguish a consistently passing test from one that passes only after reruns.
For manual cases, perform an independent walkthrough using the documented environment and data. When an evaluator must invent missing steps, the procedure is not yet executable as written.
A Worked Example: From Contract to Reviewable Tests
For the illustrative application interface, the shipping scenarios can be expressed as follows:
# tests/generated/test_shipping.py
import pytest
from checkout.shipping import shipping_fee

@pytest.mark.parametrize(
    ("subtotal_cents", "premium", "expected_fee"),
    [
        pytest.param(0, False, 499, id="SHIP-2-zero"),
        pytest.param(4999, False, 499, id="SHIP-2-below-threshold"),
        pytest.param(5000, False, 0, id="SHIP-1-at-threshold"),
        pytest.param(5001, False, 0, id="SHIP-1-above-threshold"),
        pytest.param(0, True, 0, id="SHIP-3-premium-zero"),
    ],
)
def test_shipping_fee(
    subtotal_cents: int,
    premium: bool,
    expected_fee: int,
) -> None:
    actual_fee = shipping_fee(subtotal_cents, premium=premium)
    assert actual_fee == expected_fee

@pytest.mark.parametrize(
    "premium",
    [
        pytest.param(False, id="standard"),
        pytest.param(True, id="premium"),
    ],
)
def test_negative_subtotal_is_rejected(premium: bool) -> None:
    with pytest.raises(ValueError):
        shipping_fee(-1, premium=premium)
Pytest parameterization supports executing a test function with multiple argument sets and distinct case identifiers.
This module represents seven scenarios, not two merely because it contains two test functions.
Its expected values come directly from the stated contract. The threshold cases protect different boundaries, while the negative-input cases check that membership does not bypass validation.
It remains a candidate suite until it runs against the actual application and its contribution is compared with existing tests. It makes no claim to cover API serialization, checkout persistence, or other behavior outside this function’s contract.
Collect Execution Evidence Without Hiding Failures
For a repository containing the illustrative checkout package, the following shell script captures execution and coverage artifacts. Run it from the repository root inside the approved sandbox, with the application and approved versions of pytest and Coverage.py already installed.
#!/usr/bin/env bash
mkdir -p artifacts || exit "$?"

# Discovery must succeed before execution.
python -m pytest tests/generated --collect-only -q || exit "$?"

run_status=0
python -m coverage run --branch --source=checkout \
  -m pytest tests/generated \
  -q -ra --strict-markers \
  --junitxml=artifacts/generated.xml || run_status=$?

# Attempt to retain coverage evidence even when tests fail.
report_status=0
python -m coverage json \
  -o artifacts/generated-coverage.json || report_status=$?

# A successful report command must not hide a failed test run.
if [ "$run_status" -ne 0 ]; then
  exit "$run_status"
fi

exit "$report_status"
Coverage.py supports running Python modules under measurement, limiting source scope, and exporting JSON reports.
This script collects evidence; it is not a complete acceptance gate. CI must still audit expected versus executed cases, review skips and expected failures, evaluate security constraints, and enforce the agreed coverage policy.
Run baseline-only and combined-suite measurements separately, using clean coverage data and identical settings, to calculate incremental value.
Turn the Evaluation Into an Acceptance Gate
Use a staged workflow: quarantine candidates, validate their contracts and code, execute them safely, measure their contribution, review the evidence, and then promote selected tests.
The following is an example policy to adapt to the application’s risk, not an industry-standard threshold:
| S. No |
Dimension |
Example promotion condition |
| 1 |
Accuracy |
Every retained case has an approved oracle, correct setup, and no unresolved material assumptions. |
| 2 |
Coverage |
Pre-agreed critical obligations have demonstrated checks; remaining gaps and incremental contributions are documented. |
| 3 |
Redundancy |
Each retained case adds a distinct check or has a documented reason for deliberate overlap. |
| 4 |
Executability |
Every retained case is discoverable, safe, reproducible under the evaluation conditions, and has a triaged outcome. |
Do not collapse these conditions into one weighted “AI test quality” score. A serious failure in one dimension should remain visible.
Separate candidate yield from the quality of the accepted suite. Keep counts of initial candidates, rejected cases, repaired cases, duplicates removed, confirmed defects discovered, and tests promoted. Otherwise, repeated regeneration can make the final output look strong while concealing substantial review effort.
Attach evidence to retained tests: their requirement and oracle sources, relevant code and environment revisions, execution results, incremental verification value, reviewer, and maintenance owner.
Acceptance also needs lifecycle management. Re-evaluate generated tests when contracts, interfaces, fixtures, or dependencies change, just as you would other verification code.
Conclusion
AI test cases should earn a place in QA through evidence. Accuracy establishes that the test checks the intended behavior. Coverage shows which obligations it verifies. Redundancy analysis explains why it belongs alongside existing tests. Executability demonstrates that the check can run safely and produce interpretable results.
The most useful acceptance question is not, “How many tests did the model generate?” It is: “Which important failures can this suite now detect, and what evidence shows that those checks are correct, necessary, and reliable?” Talk to our LLM testing team if you want help building this evaluation gate into your own pipeline.